Model specification and fitting
We developed this work in two major versions. The first aimed to evaluate both model structure and geographic target specificity (one or multiple countries) and their effect on model performance. The second substantially revised the aim and scope:
- Limited aim to developing the use of a modelling approach to evaluate forecast performance
- Specified a single response (model structure) and treating other covariates as confounding factors
- Improved range of confounding factors (epidemiological outcomes covering both cases and deaths; adding a covariate for dominant variant phase)
- More extensive model checking and diagnostics to address highly skewed residuals
See the sensitivity analyses below for alternative model specifications.
Covariate selection
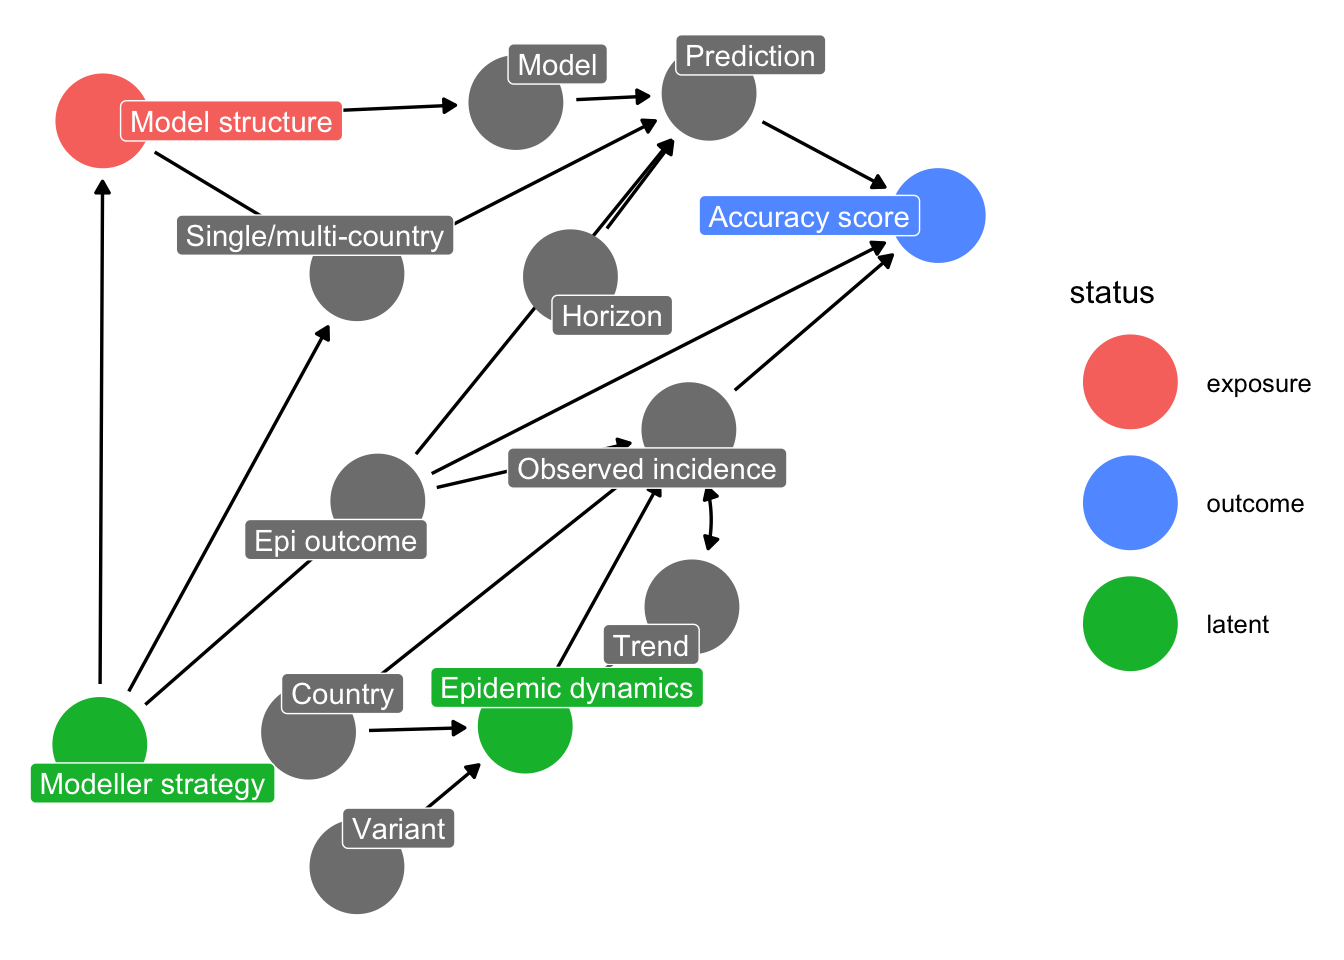
We aimed to assess the direct relationship betwen Method (i.e. model structure), and LWIS. We show the assumptions underlying our strategy in a causal diagram. We emphasise that model specification is extremely flexible, and we approach this work is exploratory rather than fully inferential.
The epidemiological outcome enters the diagram as a confounder rather than simply a covariate. Forecasters chose which outcomes to submit predictions for, and that choice is associated with model structure, opening a backdoor path from structure to the score through modeller strategy. The outcome also changes the scale and reporting characteristics of the series being scored.
The joint model therefore adjusts for:
- Forecast target difficulty (which block backdoor paths from epidemic dynamics into the score), as:
EpiTarget,Trend,Horizon,Incidence,Location,VariantPhase
- Forecaster strategy, as:
CountryTargets,Model
Querying the diagram for a minimal sufficient adjustment set returns this exact set of covariates, for the direct effect of model structure on the score. It returns no valid adjustment set for the total effect: modeller strategy is unobserved and confounds model structure with the choice of geographic scope, so no set of measured covariates blocks that path. This is why we report a partial, direct association throughout rather than a total effect, and why residual confounding by unmeasured forecaster characteristics remains a limitation.
Adjustment gives the partial association between model structure and LWIS with these covariates held fixed at their observed values.
The joint model also fits an interaction between model structure and the epidemiological outcome, allowing a structure to predict one outcome relatively better than the other. This is effect modification rather than confounding. A causal diagram encodes conditional independence and not effect modification, so the interaction does not appear in the diagram and does not change the adjustment set.
Why no separate structure main effect
The crossed term s(Method, Epi_target, bs = "re") is an unconstrained zero-mean effect over all structure-by-outcome cells, so its average across outcomes is what a structure main effect would represent. With both terms in the model and both penalised, the division between them follows the relative variance estimates rather than the data: fitted together, mgcv gave the main effect 0.001 effective degrees of freedom against 4.9 for the crossed term, and dropping it left AIC, deviance explained and residuals unchanged. We therefore fit the crossed term alone and recover the pooled per-structure effect as a contrast averaging a structure’s two cells.
The same aliasing applies to the epidemiological outcome, whose main effect is the average of the crossed effects within an outcome. Here only one of the two terms is penalised, so the unpenalised fixed effect takes the component common to all structures and the crossed term keeps only departures from it. In the fitted model the crossed effects average to zero within each outcome to numerical precision, so the whole deaths-versus-cases difference sits in the fixed coefficient. This is emergent rather than imposed: the smooth retains all ten coefficients, so no centring constraint was applied. We did not treat the outcome as a random effect, which with two levels gives no basis for estimating a variance and would shrink a large, well-identified contrast toward zero.
Forecast horizon and individual models
Performance is known to worsen with horizon, so the model includes one horizon curve shared by all models, s(Horizon, k = 4), and a factor smooth giving each model its own deviation from it, s(Horizon, Model, k = 4, bs = "fs"). The factor smooth penalises each model’s whole deviation, including its level and slope, towards zero. It therefore also carries the individual model effect, and there is no separate s(Model, bs = "re"): with both terms, a model’s level would be split between them by the relative variance estimates. We report a model’s effect as its deviation averaged over the horizons it forecast, so no model is judged on horizons it did not forecast. The same deviation at one week ahead, which every model forecast, is given under Estimates.
Alternative specifications are compared in R/sensitivity/check-horizon-spec.qmd.
Model fitting
We noted our outcome of LWIS had a strongly skewed PDF.
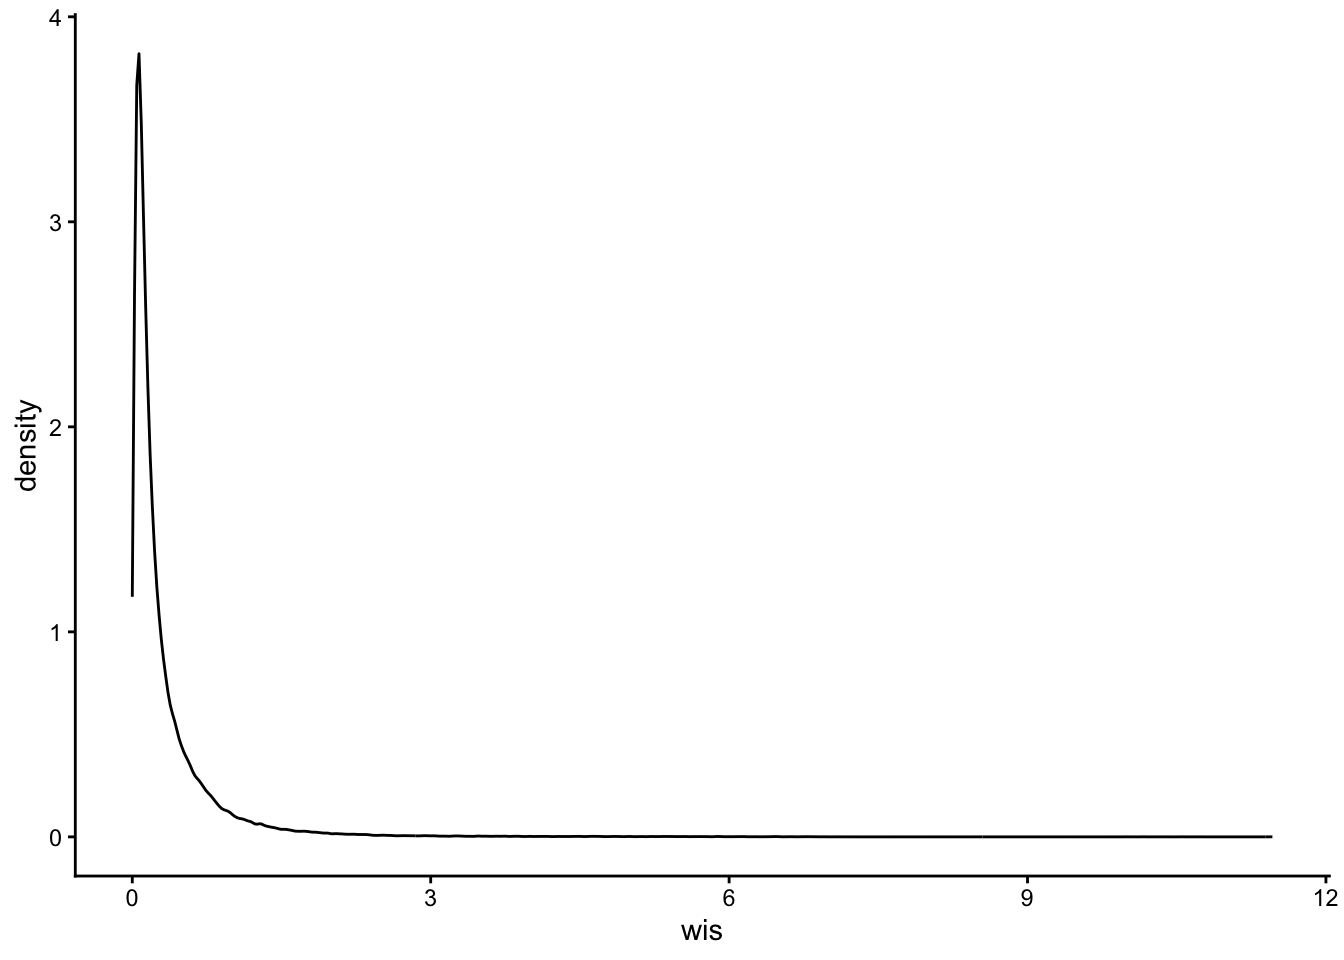
We therefore compared three error families on this specification, holding the formula and data fixed and varying only the family. The Gaussian family leaves the skew in the residuals rather than modelling it. The Gamma and Tweedie families both accommodate a right-skewed positive outcome, and fit this data almost identically. mgcv restricts the Tweedie power parameter to \(1 < p < 2\), and the estimate sits near the top of that range, so the data are asking for a variance function close to the Gamma (\(p = 2\)). The two fit this data almost identically, and both converge. We report the Tweedie fit because a Gamma has no support at zero: fitting it requires adding a constant to every score, which displaces the 553 forecasts that score exactly zero to a value set by the size of that constant.
The choice of family matters a great deal more the log scale than the natural scale. On the log scale, moving from Gaussian to Tweedie reduces residual skew from 5.8 to 0.6 and kurtosis from 77.6 to 10. On the natural scale, the WIS is heavily skewed, and the residual skew is essentially unchanged (1.84); there the change resolves the convergence failure rather than improving the distributional fit.
| Family | Deviance explained | AIC | Residual skew | Residual kurtosis |
|---|---|---|---|---|
| gaussian | 0.286 | 262955 | 5.85 | 77.6 |
| Gamma | 0.378 | -103418 | 0.52 | 9.5 |
| Tweedie(p=1.99) | 0.380 | -103165 | 0.58 | 9.3 |
A small share of forecasts (553, or 0.27%) score exactly zero: perfect predictions of zero-incidence targets, almost all deaths in the smallest countries. Gamma has no support at zero, so fitting it requires displacing these scores by a small constant. A Tweedie family with power parameter between 1 and 2 has a point mass at zero and admits them directly, so the primary model retains the exact zeros and adds no constant. Adding a constant of 1e-7 back to every score changes the fit very little (residual skew 0.58 against 0.57, deviance explained 0.380 against 0.382), so the choice is not consequential; we prefer the specification that represents the scores as they are.
We used the mgcv package v1.9-4 using R 4.5, with the formula:
wis ~ s(Method, Epi_target, bs = “re”) + Epi_target + s(CountryTargets, bs = “re”) + s(Incidence) + s(Trend, bs = “re”) + s(Location, bs = “re”) + s(VariantPhase, bs = “re”) + s(Horizon, k = 4) + s(Horizon, Model, k = 4, bs = “fs”)
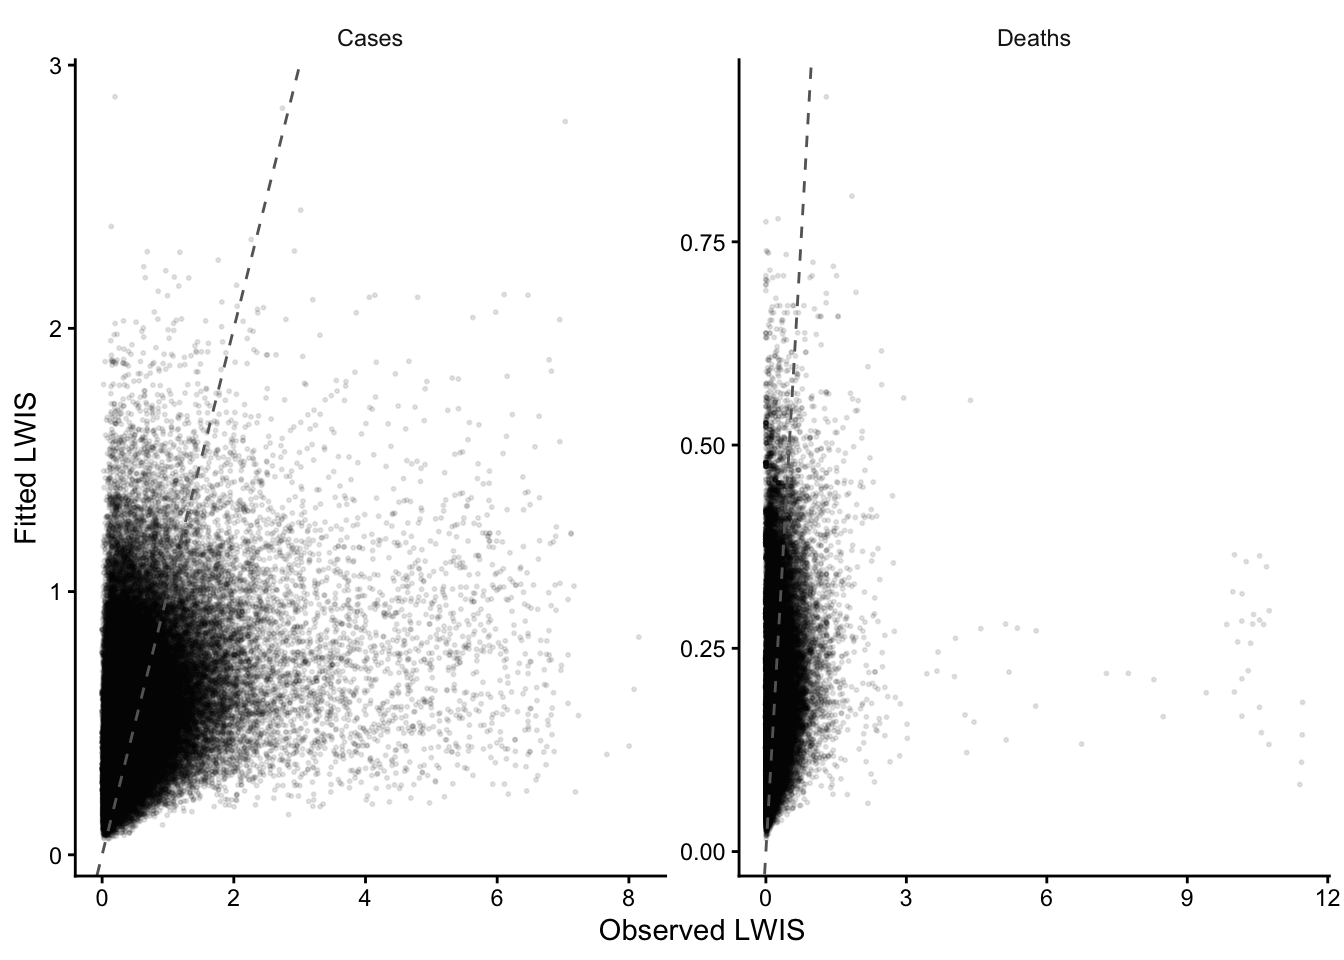
We assessed model fit visually plotting observed-versus-fitted values and inspecting residuals in Q-Q and histogram plots.