In-sample checks
Whether the fitted joint model reproduces the national data it was fitted to. The same checks by province are on the province in-sample checks page and by health zone on the health-zone in-sample checks page. How the model predicts data it has not seen is on the forecast evaluation page.
Load packages, data and fitted chains
# Shared setup: packages, observations and the fit registry. See
# `docs/pages/_setup.jl`.
using BVDOutbreakSize
include(joinpath(pkgdir(BVDOutbreakSize), "docs", "pages", "_setup.jl"))
validation_forecast_from (generic function with 1 method)# The fits and prior draws this page reads, loaded from the cache here.
chn_joint = load_fit("joint")
prior_chn = joint_prior_draws();Summary
Whether each stream is reproduced, from the checks further down this page. Bias runs from −1 to 1 and is negative when the model under-predicts, and coverage is the fraction of vintages inside the predictive interval.
Streams: 12 of 17 fitted streams have 90% coverage of at least 0.8.
Least well reproduced: Specimens analysed (cumulative) (bias -0.13, 90% coverage 0.5); In-care deaths/day (bias 0.13, 90% coverage 0.88); Admissions/day (bias 0.12, 90% coverage 0.81).
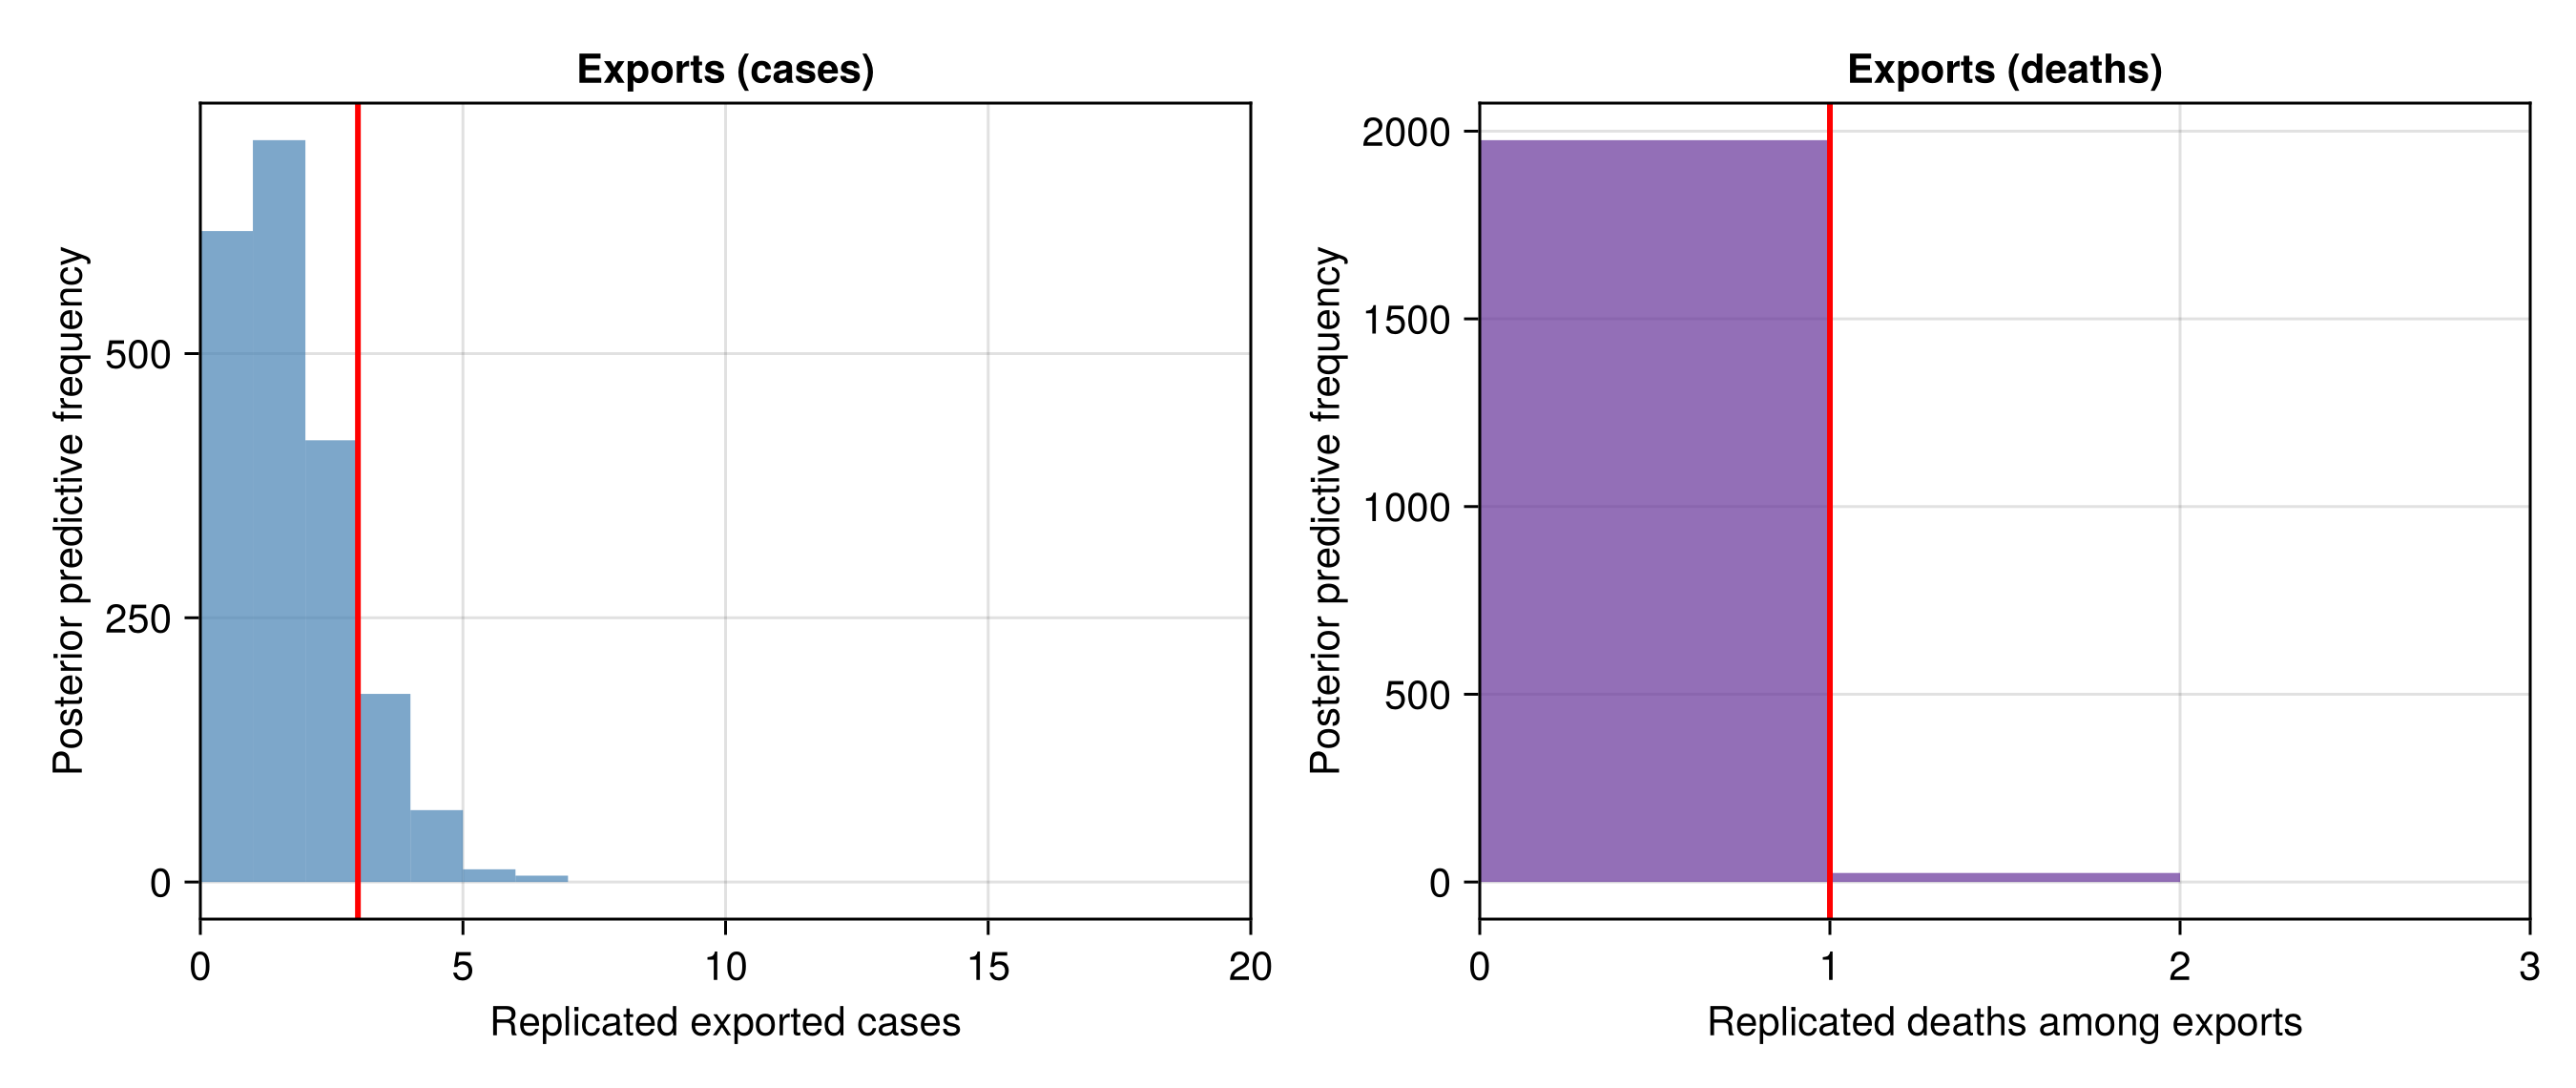
Exports: Uganda exports observed 3 against a predictive median of 1 (90% interval 0–3), and export deaths observed 1 against a predictive median of 0 (90% interval 0–0).
Streams still reporting
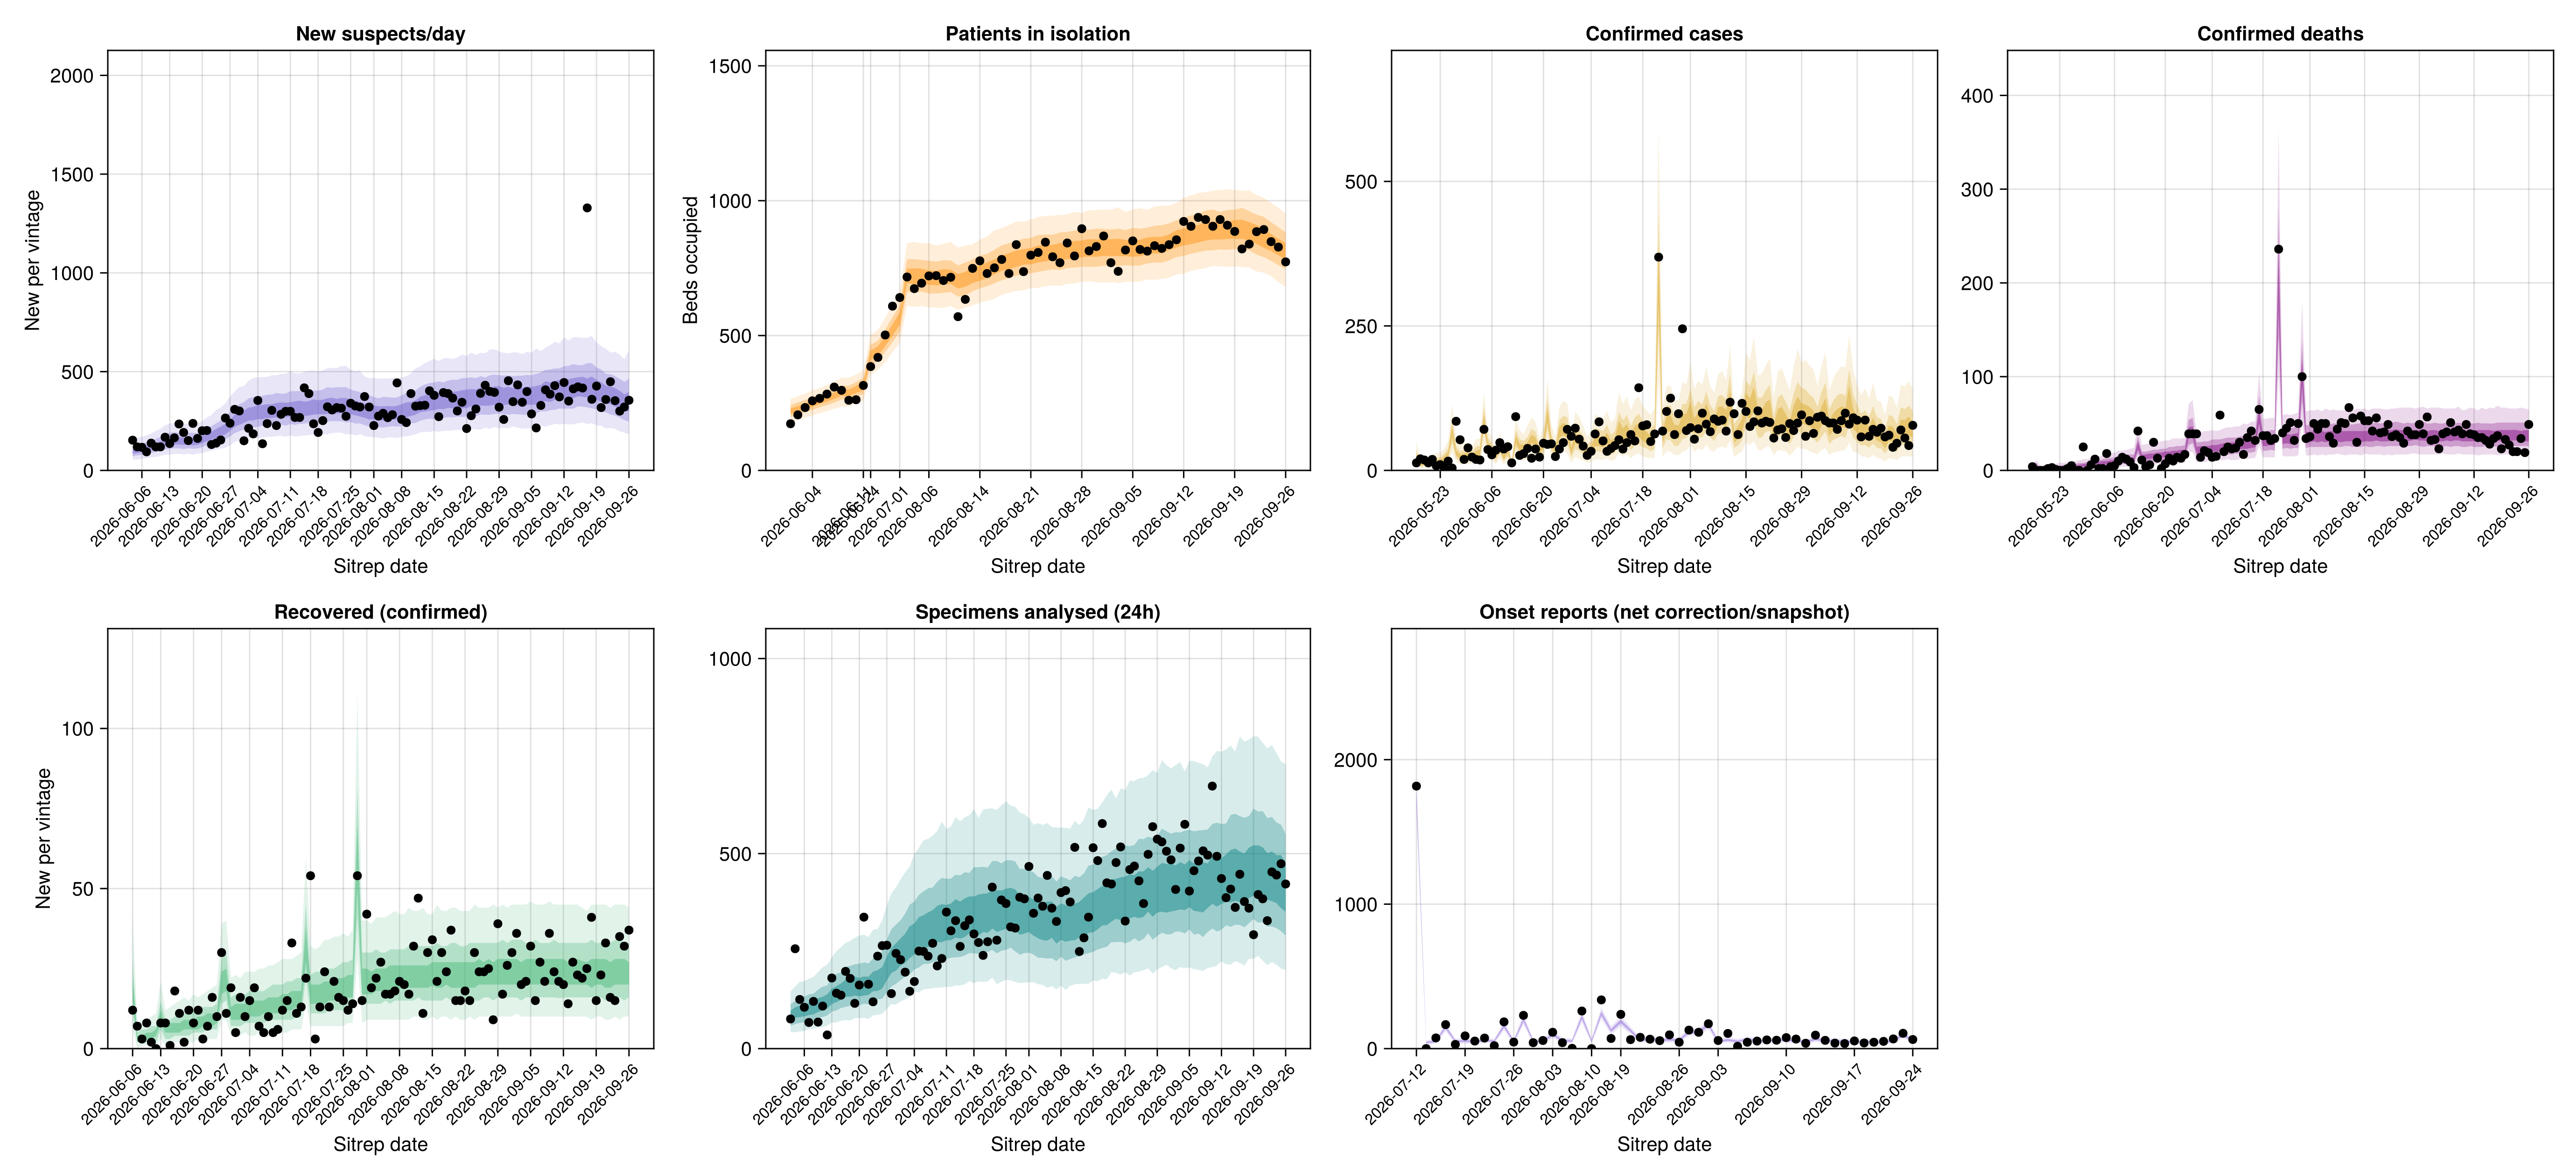
New suspects/day: bias 0.04, 90% coverage 0.96 over 108 vintages.
Patients in isolation: bias 0.02, 90% coverage 0.97 over 69 vintages.
Confirmed cases: bias 0.07, 90% coverage 0.93 over 126 vintages.
Confirmed deaths: bias 0.04, 90% coverage 0.91 over 128 vintages.
Recovered (confirmed): bias 0.03, 90% coverage 0.92 over 107 vintages.
Specimens analysed (24h): bias -0.05, 90% coverage 0.97 over 109 vintages.
Onset reports (net correction/snapshot): bias -0.09, 90% coverage 0.67 over 52 vintages.
Streams no longer reporting
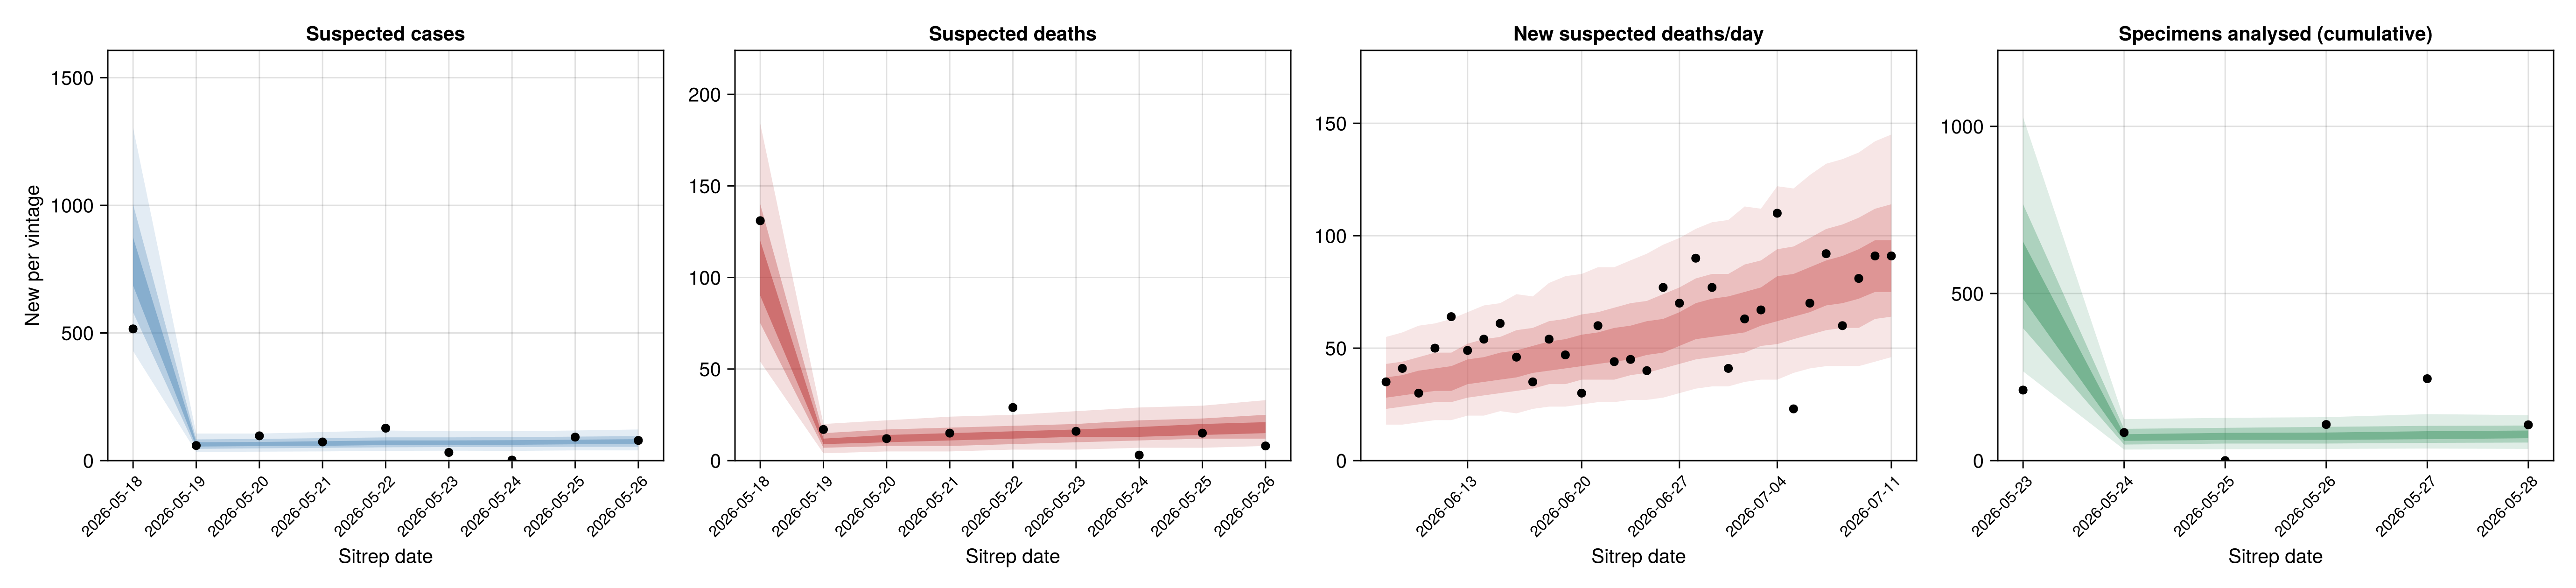
Suspected cases: bias 0.02, 90% coverage 0.67 over 9 vintages.
Suspected deaths: bias -0.06, 90% coverage 0.78 over 9 vintages.
New suspected deaths/day: bias -0.1, 90% coverage 0.94 over 32 vintages.
Specimens analysed (cumulative): bias -0.13, 90% coverage 0.5 over 6 vintages.
Admissions/day: bias 0.12, 90% coverage 0.81 over 42 vintages.
In-care deaths/day: bias 0.13, 90% coverage 0.88 over 42 vintages.
Rule-outs/day: bias -0.06, 90% coverage 0.61 over 41 vintages.
Absconded/day: bias 0.07, 90% coverage 0.83 over 42 vintages.
Confirmed in care: bias -0.04, 90% coverage 1.0 over 38 vintages.
Suspects in care: bias -0.09, 90% coverage 0.97 over 38 vintages.
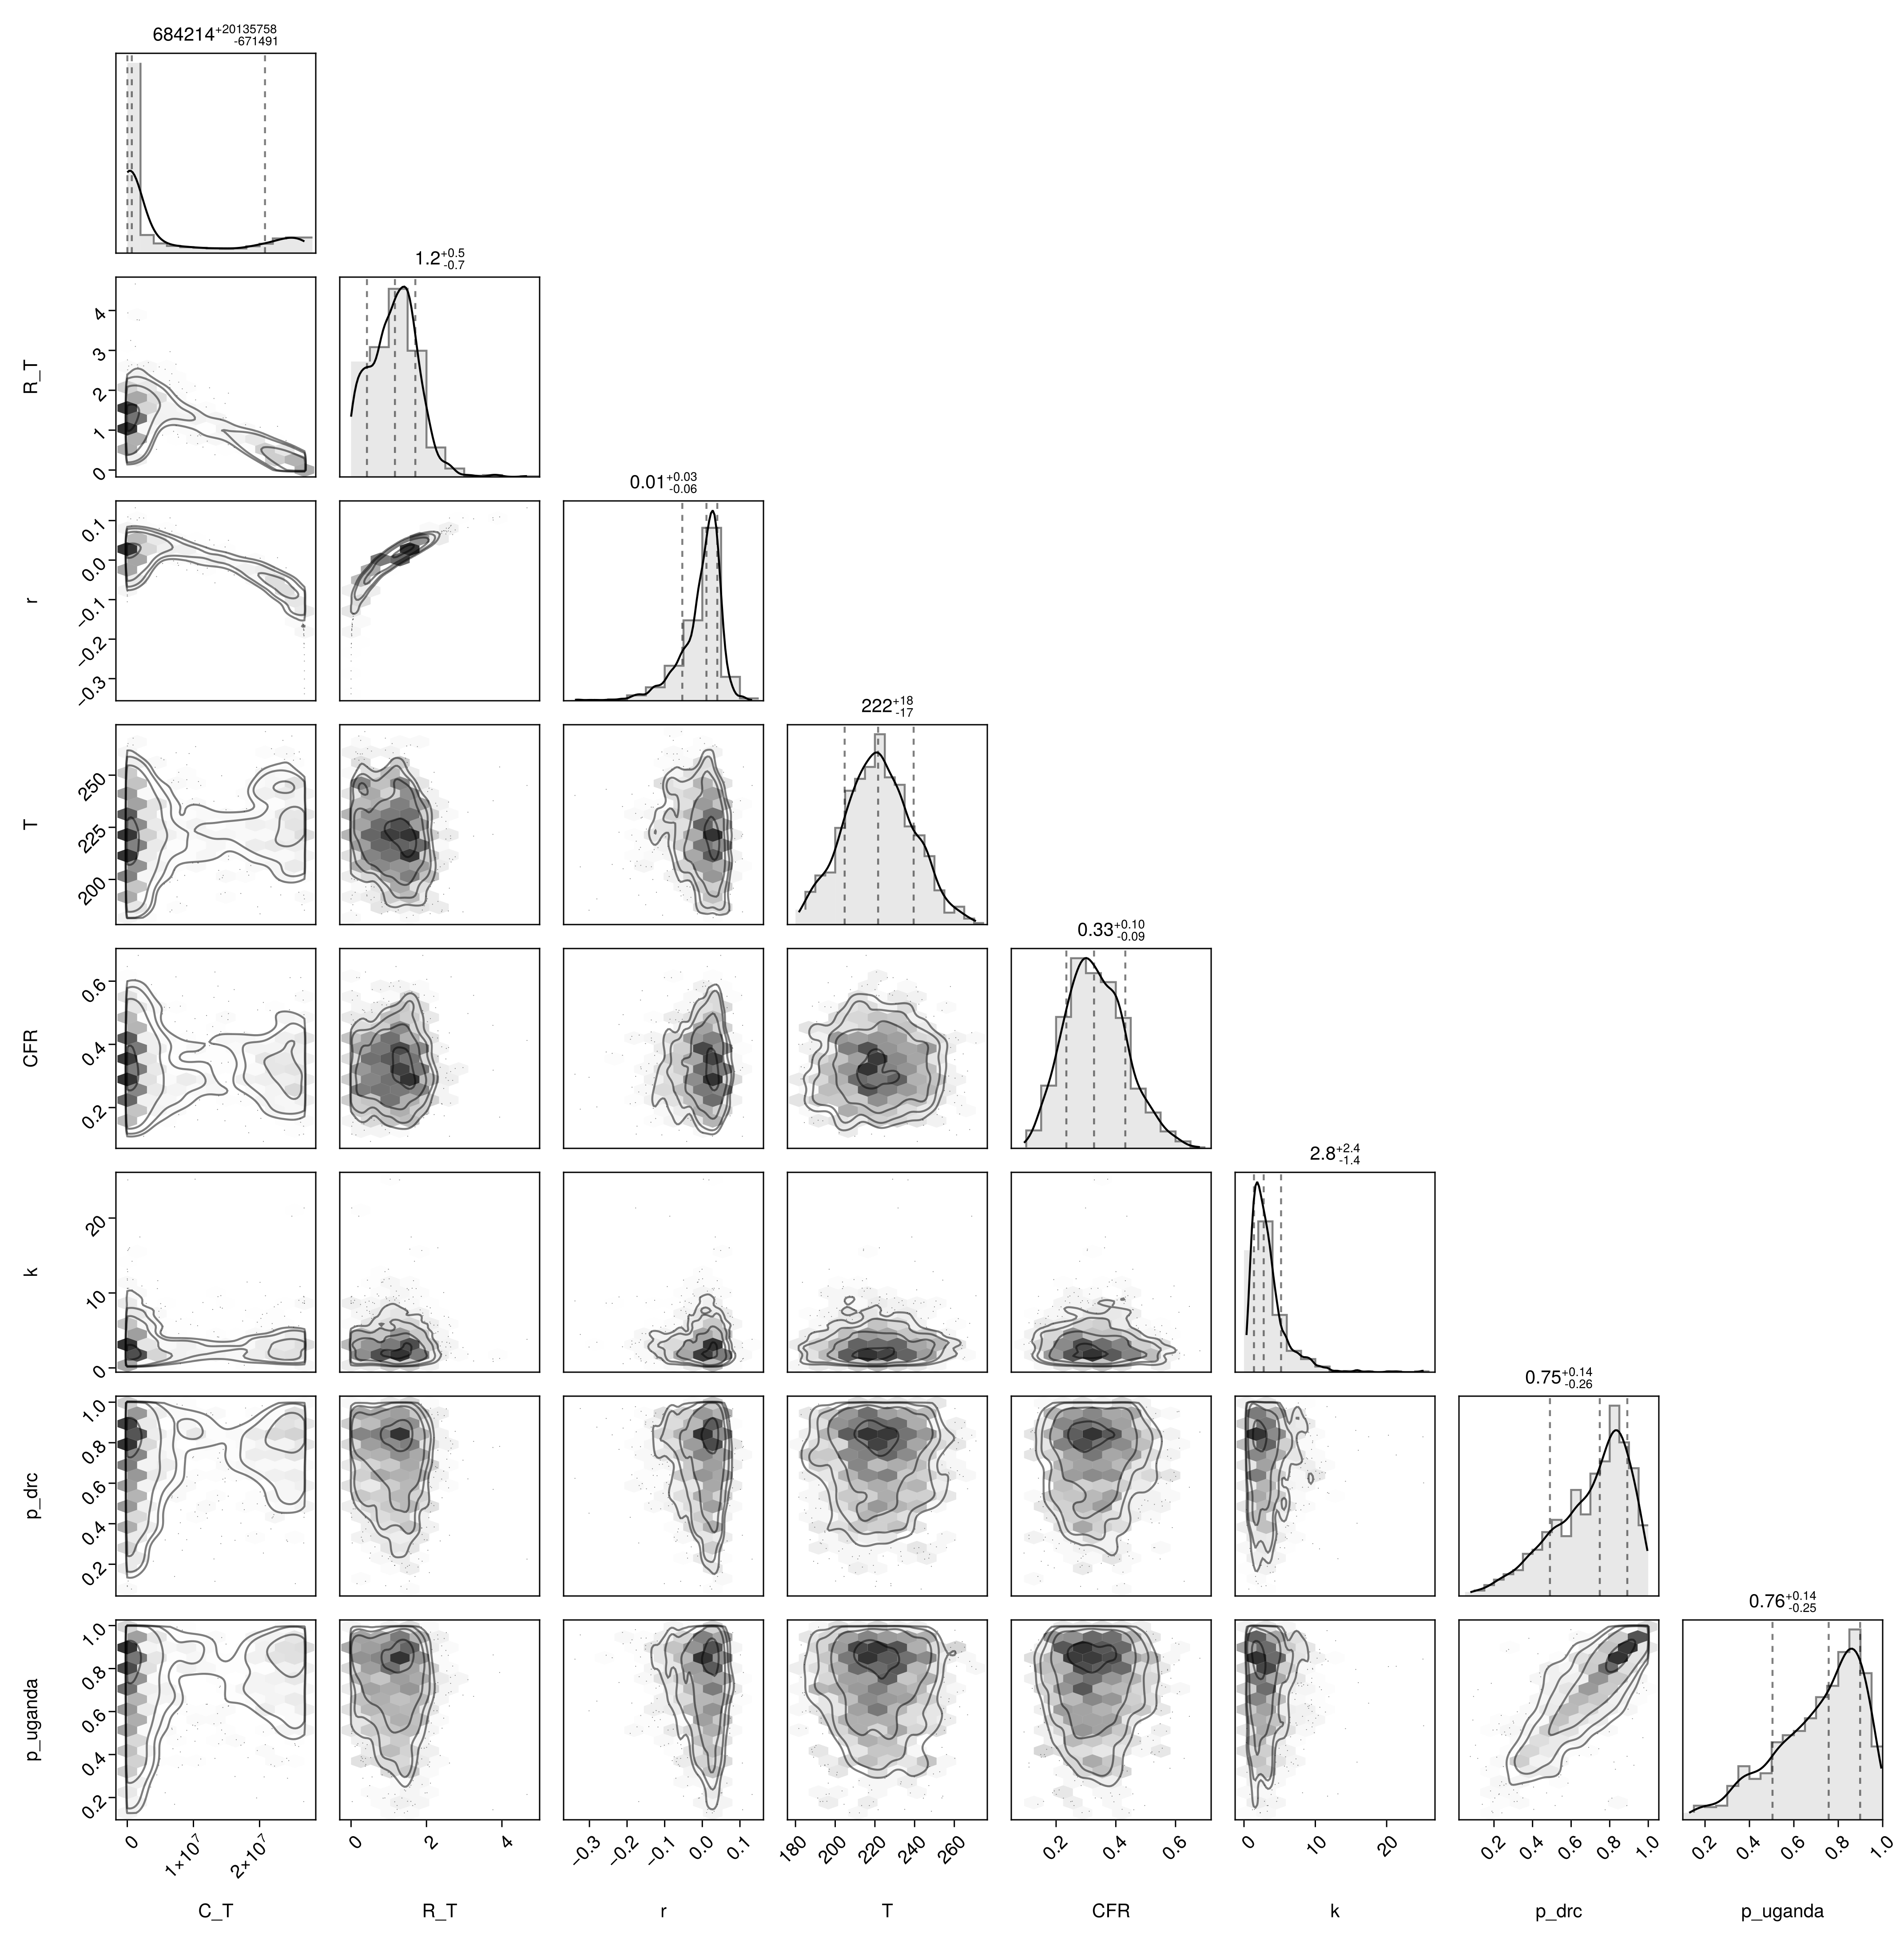
Prior predictive check
Whether the prior, before any data are fitted, brackets the observed counts.
Summarise the joint prior
prior_C_table = summary_table(prior_chn, [:C_T]; digits = 0);Show prior summary table
| Row | Quantity | Lower 90% | Lower 60% | Lower 30% | Upper 30% | Upper 60% | Upper 90% |
|---|---|---|---|---|---|---|---|
| String | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | |
| 1 | C_T | 2210.0 | 20704.0 | 117847.0 | 3.31167e6 | 1.61375e7 | 2.59409e7 |
Prior pair plot
prior_pair_fig = plot_pair(
    prior_chn,
    [
        :C_T, :R_T, :r, :T, :CFR, :k,
        :p_drc, :p_uganda,
    ]
);
Posterior predictive checks
Whether data replicated from the fitted model reproduce each observed stream.
Streams still reporting
Whether the streams reported within a week of the cut-off are reproduced.
Cumulative
Whether the replicated running totals, or daily counts for a daily stream, track the observed ones.
Joint posterior predictive plot
# The joint posterior predictive, shared with the province page (see
# `joint_posterior_predictive` in `docs/pages/_setup.jl`).
pp_joint = joint_posterior_predictive();

# `predict` stores each stream's per-vintage increments as one
# vector-valued variable (`<stream>_increments.increments`); the slice is
# an iter×chain matrix of per-draw increment vectors, exactly the
# `replicates` shape `plot_vintage_conditional_ppc` grounds on each
# vintage's observed previous cumulative for the one-step-ahead
# predictive. Look it up by its VarName with FlexiChains' `Prefixed`, which
# matches a (submodel-prefixed) key by its varname tail: `Prefixed(@varname(
# reported_increments.increments))` finds `cases_state.reported_increments.
# increments` without hard-coding the `cases_state.` prefix, and matches by
# the varname tail rather than a loose substring, so it cannot be fooled by a
# scalar `expected_*_T` deterministic. `FlexiChains` is a package
# dependency (imported, not exported), so it is reached through the package
# namespace.
const _Prefixed = BVDOutbreakSize.FlexiChains.Prefixed;
_vintage_replicates(pp, vn) = collect(pp[_Prefixed(vn)]);

# Grid day-index → INSP situation-report date label.
_vintage_dates(days) = string.(obs.seeding .+ Day.(days .- 1));

reported_panel = (;
    id = :suspected_cases,
    title = "Suspected cases",
    dates = _vintage_dates(obs.reported_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(reported_increments.increments)
    ),
    observed = obs.reported_history.counts, colour = :steelblue,
);
# Daily new-suspect inflow: a per-day count (not cumulative), so the panel
# is drawn with `cumulative = false` — each replicate is its own daily
# count against the observed daily count rather than a running total. Its
# days pick up where the cumulative suspected panel freezes.
suspected_daily_panel = (;
    id = :suspected_daily,
    title = "New suspects/day",
    dates = _vintage_dates(obs.suspected_daily_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(suspected_daily.increments)
    ),
    observed = obs.suspected_daily_history.counts,
    colour = :slateblue, cumulative = false,
);
# Isolation/treatment-bed occupancy: a census stock, so the panel is drawn
# with `cumulative = false` — each replicate is the modelled bed count on a
# report day against the observed "Patients en isolement" count. It is a
# level, not a count of new events, so it carries its own `ylabel` rather
# than the "Daily count" and "New per vintage" defaults, which would read as
# an accumulating total on a series that rises through the outbreak. The count
# is the suspect inflow carried through a length-of-stay survival, so its
# level and lag reflect the admission proportion and the stays. The censored-
# occupancy likelihood stores its per-day predictive draws under the submodel
# `obs` variable (not `increments`), so the replicates are read from that key.
# The treatment model scores the total occupancy only on the days without a
# published confirmed/suspect split (a per-day total-or-split switch): on the
# split days the two sub-stock census panels carry the fit instead, so the
# `isolation.obs` predictive holds only the non-split days. Drop the split
# days from the panel's dates and observed counts to match that length.
_iso_split_days = Set(Int.(obs.treatment_confirmed_incare_history.days))
_iso_keep = [!(Int(d) in _iso_split_days) for d in obs.isolation_history.days]
isolation_panel = (;
    id = :isolation_beds,
    title = "Patients in isolation",
    dates = _vintage_dates(obs.isolation_history.days[_iso_keep]),
    replicates = _vintage_replicates(
        pp_joint, @varname(isolation.obs)
    ),
    observed = obs.isolation_history.counts[_iso_keep],
    colour = :darkorange, cumulative = false,
    ylabel = "Beds occupied",
);
deaths_panel = (;
    id = :suspected_deaths,
    title = "Suspected deaths",
    dates = _vintage_dates(obs.deaths_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(death_increments.increments)
    ),
    observed = obs.deaths_history.counts, colour = :firebrick,
);
# Daily new suspected deaths: a per-day count (not cumulative), so the panel
# is drawn with `cumulative = false` — each replicate is its own daily count
# against the observed daily count rather than a running total. Its days
# pick up where the cumulative suspected-death panel freezes, the deaths
# analogue of the new-suspects-per-day panel.
suspected_daily_deaths_panel = (;
    id = :suspected_daily_deaths,
    title = "New suspected deaths/day",
    dates = _vintage_dates(obs.suspected_daily_deaths_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(suspected_daily_deaths.increments)
    ),
    observed = obs.suspected_daily_deaths_history.counts,
    colour = :indianred, cumulative = false,
);
# Specimens analysed is the single modelled laboratory volume (the
# report-to-analysed delay and tested-fraction throughput), fit to the
# cumulative analysed series, so it gets the same cumulative conditional
# check as the suspected streams. This is the testing volume the
# confirmed-positivity denominator is built from.
tests_analysed_panel = (;
    id = :tests_analysed,
    title = "Specimens analysed (cumulative)",
    dates = _vintage_dates(obs.lab_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(analysed_increments.increments)
    ),
    observed = obs.lab_history.counts, colour = :seagreen,
);
# Post-cutoff 24h analysed volume: once the cumulative series stops, INSP
# reports a 24h analysed count on some days. These are fitted as per-day
# volumes (not cumulative), so the panel is a standalone daily check
# (`cumulative = false`): the modelled daily analysed volume against the
# observed 24h count on each reported day.
tests_analysed_daily_panel = (;
    id = :tests_analysed_daily,
    title = "Specimens analysed (24h)",
    dates = _vintage_dates(obs.lab_daily_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(analysed_daily_increments.increments)
    ),
    observed = obs.lab_daily_history.counts, colour = :teal,
    cumulative = false,
);

# Confirmed cases are scored over two groups of laboratory windows: the
# early confirmed vintages (no per-vintage analysed denominator, scored
# as counts against the modelled laboratory volume) and the observed
# windows (a Binomial of the observed analysed denominator). Both groups
# produce per-window replicate increments in `predict`, so concatenating
# them oldest-first gives the per-vintage cumulative confirmed-case
# trajectory, grounded on the observed cumulative confirmed at each window
# end-day. The 24-25 May analysis stall merges into 26 May, so the window
# grid is slightly coarser than the raw confirmed history.
_conf_windows = BVDOutbreakSize.confirmed_positivity_windows(
    obs.confirmed_history, obs.lab_history, obs.lab_daily_history
);
# Oldest-first: early (no denominator) → observed (analysed Binomial) →
# late (post-28 May; trusted 24h-analysed days are Binomial windows, the
# rest unanchored windows scored against the modelled volume).
_conf_window_days = vcat(
    _conf_windows.early_days, _conf_windows.obs_days,
    _conf_windows.late_days
);
function _confirmed_at(day)
    i = searchsortedlast(obs.confirmed_history.days, day)
    return i == 0 ? 0 : Int(obs.confirmed_history.counts[i])
end;
_conf_early = _vintage_replicates(
    pp_joint, @varname(early_increments.increments)
);
_conf_obs = collect(
    first(
        pp_joint[k]
            for k in keys(pp_joint)
            if occursin("confirmed_state.confirmed_positives.positives", string(k))
    )
);
_conf_late = _vintage_replicates(
    pp_joint, @varname(late_increments.increments)
);
confirmed_panel = (;
    id = :confirmed_cases,
    title = "Confirmed cases",
    dates = _vintage_dates(_conf_window_days),
    replicates = [
        vcat(collect(e), collect(p), collect(l))
            for (e, p, l) in zip(vec(_conf_early), vec(_conf_obs), vec(_conf_late))
    ],
    observed = [_confirmed_at(d) for d in _conf_window_days],
    colour = :goldenrod,
);

# Confirmed deaths are a per-vintage stream, scored as increments of the
# modelled confirmed-death trajectory up to the cut-off, so they get the
# same cumulative conditional check.
confirmed_deaths_panel = (;
    id = :confirmed_deaths,
    title = "Confirmed deaths",
    dates = _vintage_dates(obs.confirmed_deaths_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(cdeath_increments.increments)
    ),
    observed = obs.confirmed_deaths_history.counts, colour = :purple,
);

# Recovered among confirmed ("cumul guéris") is a cumulative per-vintage
# stream fitted through the increments of the modelled recovered trajectory
# (the confirmation-to-recovery convolution of the daily confirmed cases) up
# to the cut-off, so it gets the same cumulative conditional check.
recovered_panel = (;
    id = :recovered,
    title = "Recovered (confirmed)",
    dates = _vintage_dates(obs.recovered_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(recovered_increments.increments)
    ),
    observed = obs.recovered_history.counts, colour = :mediumseagreen,
);

# Tableau 6 treatment-centre daily flows (the new patient-movement data
# sources): admissions and the discharge reasons (in-care deaths, rule-outs,
# absconded). Per-day counts, so drawn with `cumulative = false` — each
# replicate is the modelled daily flow on a report day against the observed
# Tableau 6 count.
admissions_panel = (;
    id = :treatment_admissions,
    title = "Admissions/day",
    dates = _vintage_dates(obs.treatment_admissions_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(admissions.increments)
    ),
    observed = obs.treatment_admissions_history.counts,
    colour = :teal, cumulative = false,
);
incare_deaths_panel = (;
    id = :treatment_deaths,
    title = "In-care deaths/day",
    dates = _vintage_dates(obs.treatment_deaths_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(incare_deaths.increments)
    ),
    observed = obs.treatment_deaths_history.counts,
    colour = :darkred, cumulative = false,
);
ruleouts_panel = (;
    id = :treatment_ruleouts,
    title = "Rule-outs/day",
    dates = _vintage_dates(obs.treatment_ruleout_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(ruleouts.increments)
    ),
    observed = obs.treatment_ruleout_history.counts,
    colour = :goldenrod, cumulative = false,
);
absconded_panel = (;
    id = :treatment_absconded,
    title = "Absconded/day",
    dates = _vintage_dates(obs.treatment_absconded_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(absconded.increments)
    ),
    observed = obs.treatment_absconded_history.counts,
    colour = :slategray, cumulative = false,
);

# Tableau 6 occupancy split (`dont confirmes` / `dont suspects`): the two
# in-care prevalence sub-stocks. Per-day census counts, so drawn with
# `cumulative = false` — each replicate is the modelled confirmed-in-care or
# suspect-in-care bed count on a report day against the observed sub-stock.
# On these split days the total-occupancy panel is not scored, so the two
# sub-stock panels carry the window instead.
confirmed_incare_panel = (;
    id = :treatment_beds,
    title = "Confirmed in care",
    dates = _vintage_dates(obs.treatment_confirmed_incare_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(confirmed_incare_obs.increments)
    ),
    observed = obs.treatment_confirmed_incare_history.counts,
    colour = :darkgoldenrod, cumulative = false,
    ylabel = "Beds occupied",
);
suspect_incare_panel = (;
    id = :suspect_beds,
    title = "Suspects in care",
    dates = _vintage_dates(obs.treatment_suspect_incare_history.days),
    replicates = _vintage_replicates(
        pp_joint, @varname(suspect_incare_obs.increments)
    ),
    observed = obs.treatment_suspect_incare_history.counts,
    colour = :chocolate, cumulative = false,
    ylabel = "Beds occupied",
);

# Symptom-onset reporting triangle: one cell per (onset day, report day)
# pair. The cells sharing a report day are summed into one net correction
# per snapshot to fit the per-vintage panel shape. The onset-by-report grid
# is the snapshot nowcast figure further down. A net correction is not a
# running total, so `cumulative = false`.
_onset_ppc_report_days = sort(unique(obs.onset_curve_history.report_days))
_onset_ppc_groups = [
    findall(==(r), obs.onset_curve_history.report_days)
        for r in _onset_ppc_report_days
]
_onset_ppc_replicates_raw = _vintage_replicates(
    pp_joint, @varname(onset_report_state.increments)
)
onset_panel = (;
    id = :onset_reports,
    title = "Onset reports (net correction/snapshot)",
    dates = _vintage_dates(_onset_ppc_report_days),
    replicates = [
        [sum(collect(rep)[g]) for g in _onset_ppc_groups]
            for rep in vec(_onset_ppc_replicates_raw)
    ],
    observed = [
        sum(obs.onset_curve_history.increments[g])
            for g in _onset_ppc_groups
    ],
    colour = :mediumpurple, cumulative = false,
);

# Each panel runs to its own last vintage, so a stream that keeps
# reporting shows the full series the model is fitting rather than the
# window the streams that stopped earlier cover. The per-stream
# calibration table reads this ordered list too, so it stays whole and
# the two stream groups are filtered out of it.
vintage_panels = [
    reported_panel, suspected_daily_panel, isolation_panel, confirmed_panel,
    deaths_panel, suspected_daily_deaths_panel, confirmed_deaths_panel,
    recovered_panel, tests_analysed_panel, tests_analysed_daily_panel,
    admissions_panel, incare_deaths_panel, ruleouts_panel, absconded_panel,
    confirmed_incare_panel, suspect_incare_panel, onset_panel,
];
# The incidence view drops the treatment-centre flow and occupancy-split
# panels, whose per-day counts are already their own incidence.
vintage_incidence_panels = [
    reported_panel, suspected_daily_panel, isolation_panel, confirmed_panel,
    deaths_panel, suspected_daily_deaths_panel, confirmed_deaths_panel,
    recovered_panel, tests_analysed_panel, tests_analysed_daily_panel,
    onset_panel,
];
# Whether a panel's stream was still being reported at the cut-off, from
# the shared registry rule (last vintage within a week of the cut-off)
# rather than a per-page list of dates that goes stale.
_still_reporting(p) = stream_reporting(obs, p.id);
reporting_panels = filter(_still_reporting, vintage_panels);
stopped_panels = filter(!_still_reporting, vintage_panels);
reporting_incidence_panels = filter(
    _still_reporting, vintage_incidence_panels
);
stopped_incidence_panels = filter(
    !_still_reporting, vintage_incidence_panels
);
joint_vintage_ppc_fig = plot_vintage_conditional_ppc(reporting_panels);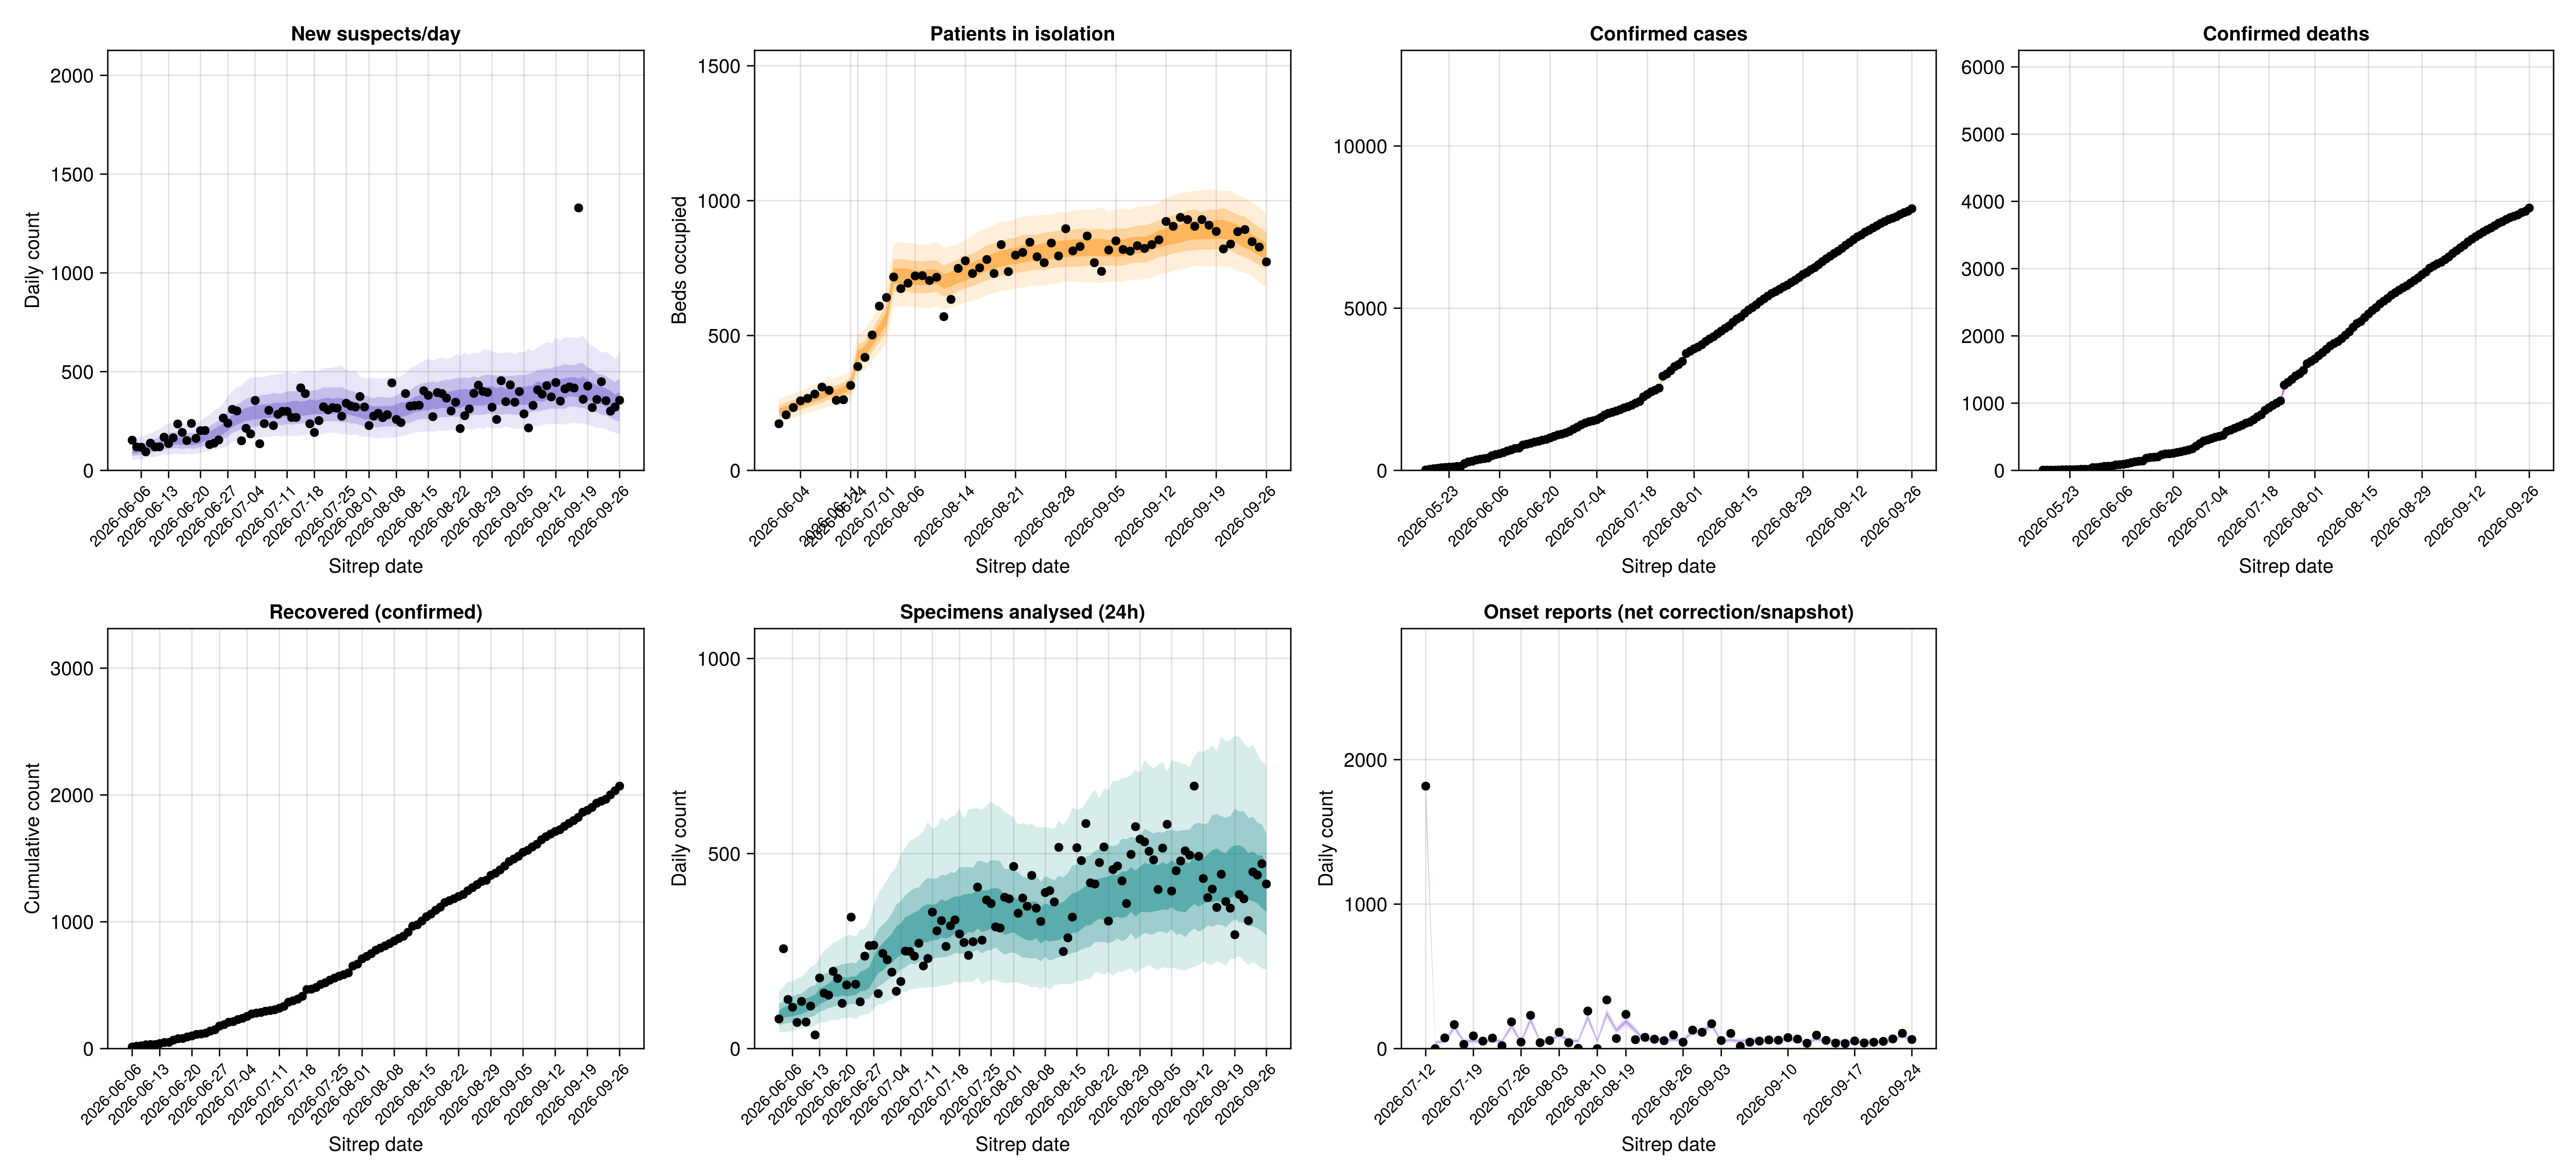
Per-vintage incidence
Whether the count reported between consecutive situation reports is reproduced.
Per-vintage incidence posterior predictive plot
joint_vintage_incidence_fig = plot_vintage_incidence_ppc(
    reporting_incidence_panels
);
Streams no longer reporting
Whether the streams that stopped before the cut-off are reproduced over the dates they cover.
Cumulative
Joint posterior predictive plot
joint_vintage_ppc_stopped_fig = plot_vintage_conditional_ppc(stopped_panels);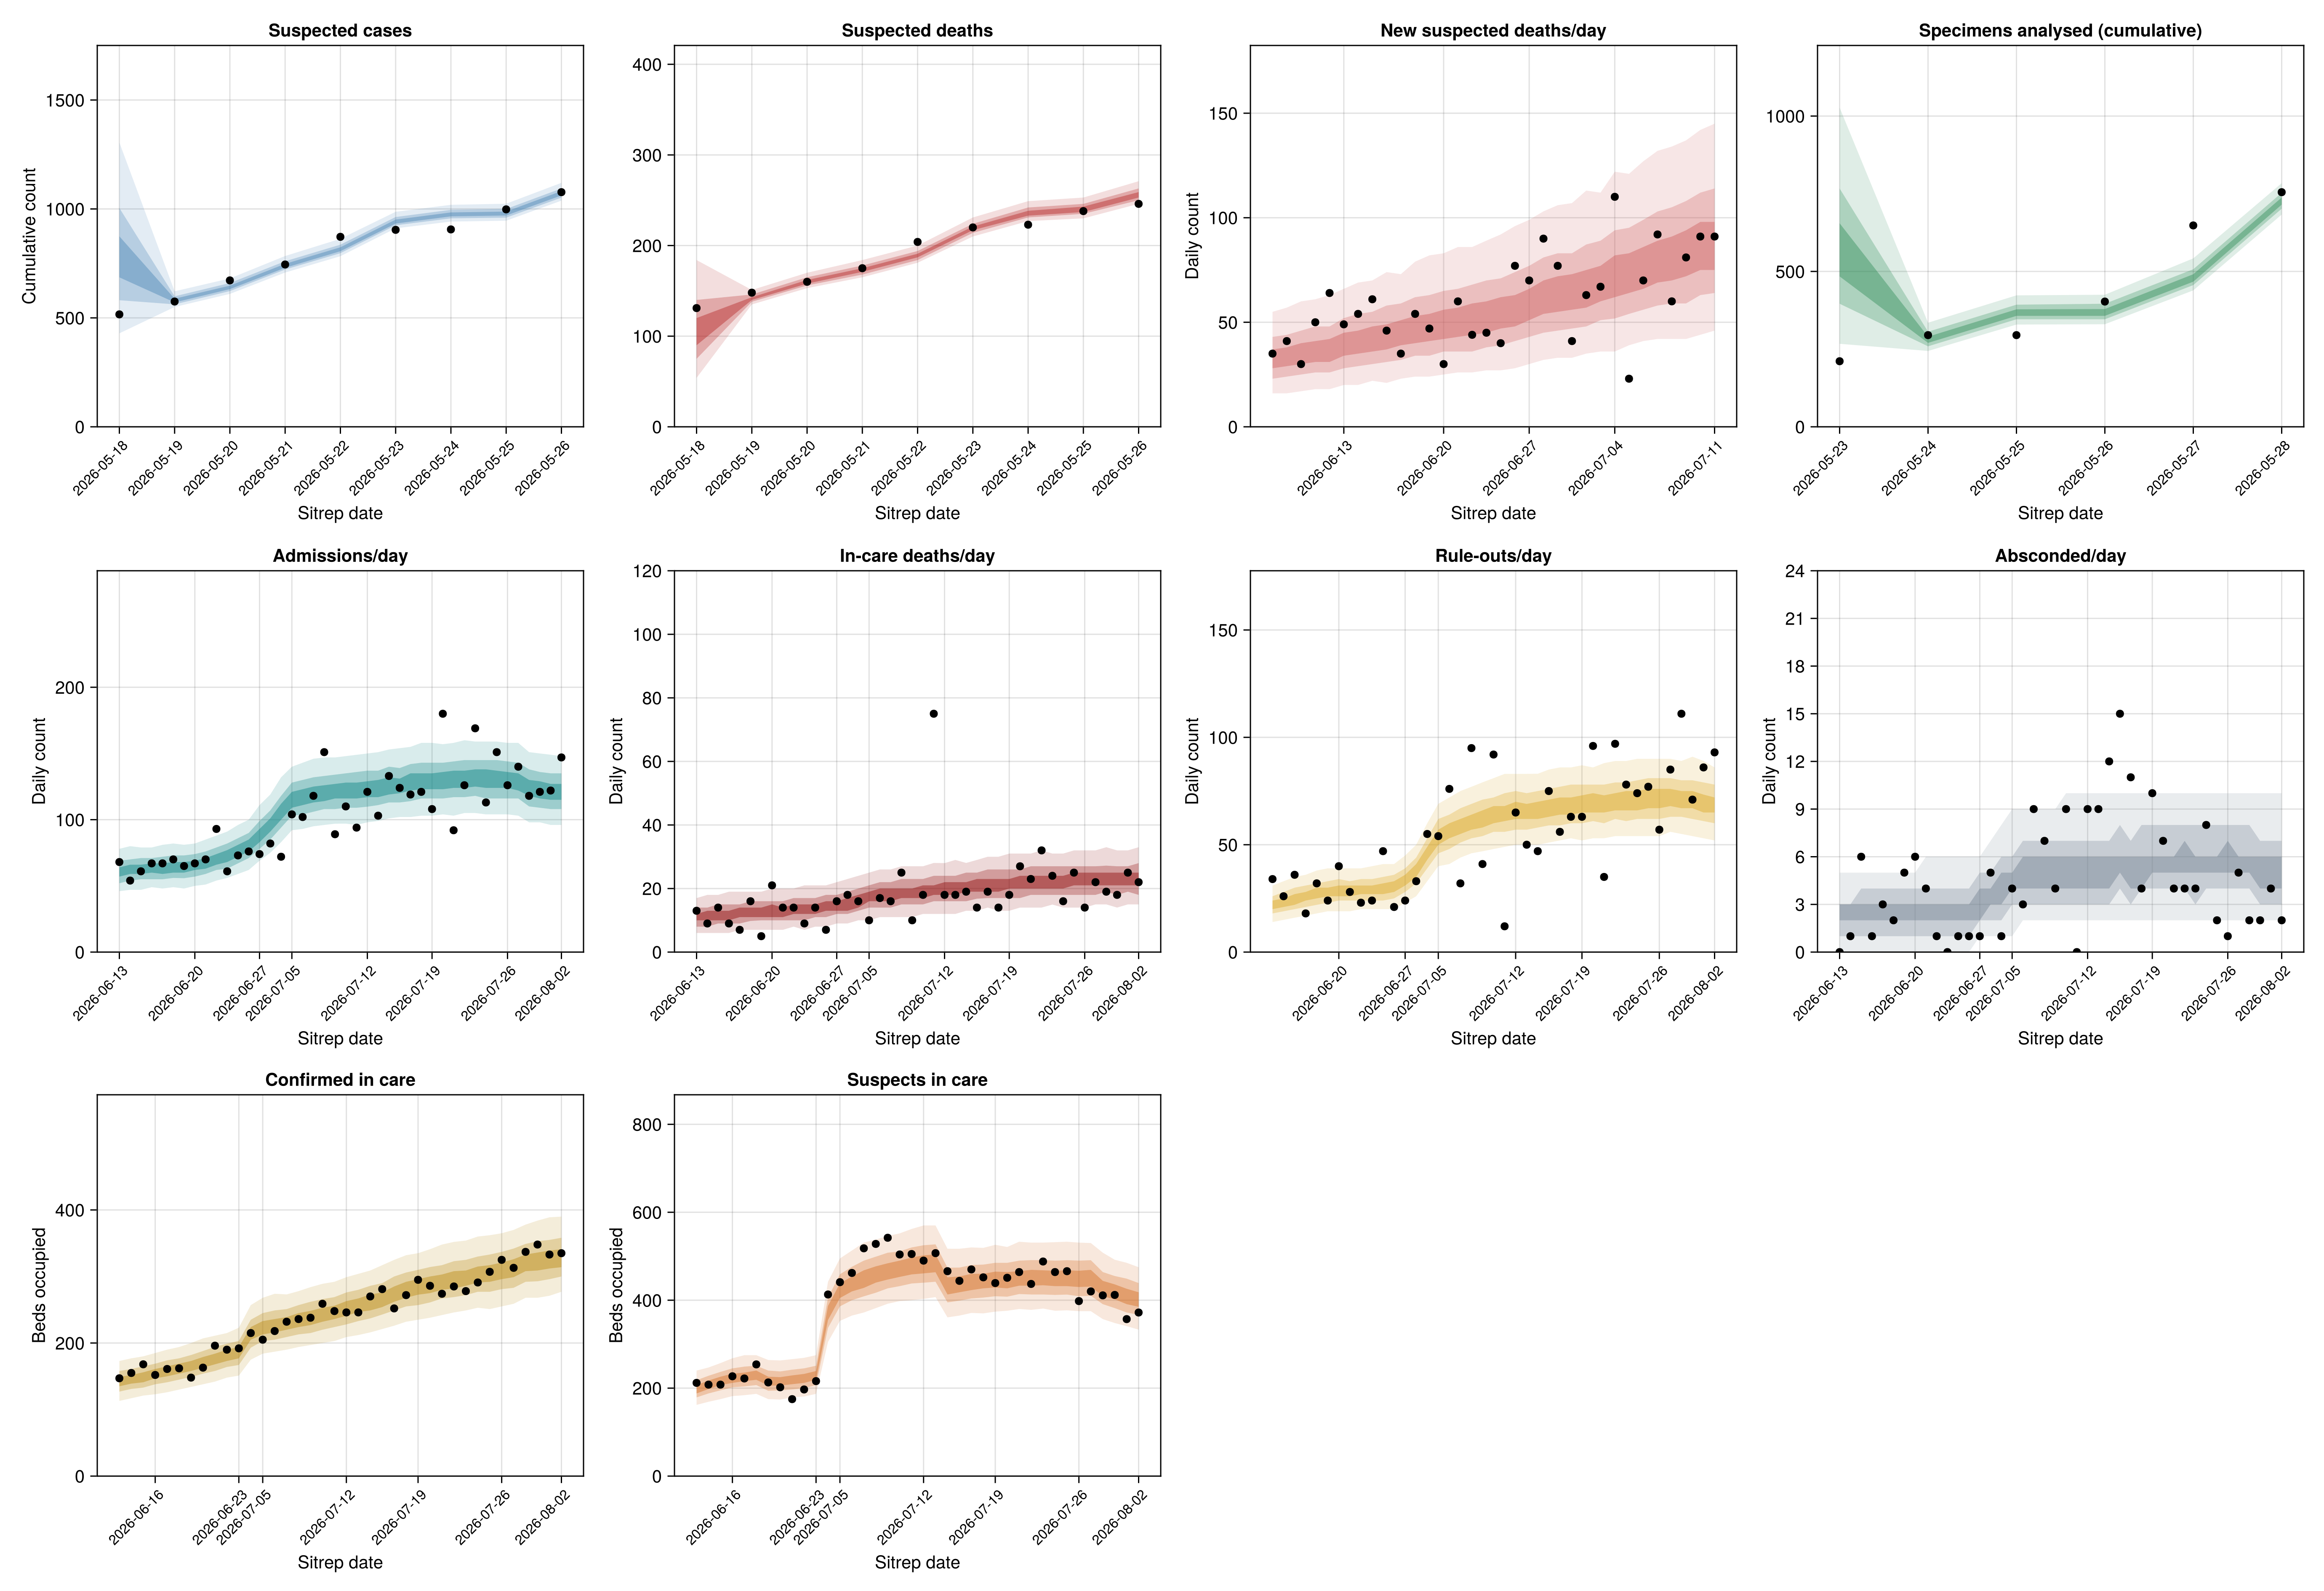
Per-vintage incidence
Per-vintage incidence posterior predictive plot
joint_vintage_incidence_stopped_fig = plot_vintage_incidence_ppc(
    stopped_incidence_panels
);
Stream calibration
Whether each stream's per-vintage predictions are calibrated against the observed counts.
stream_calibration_table = stream_calibration(vintage_panels);Per-stream calibration plot
stream_calibration_fig = plot_stream_calibration(stream_calibration_table);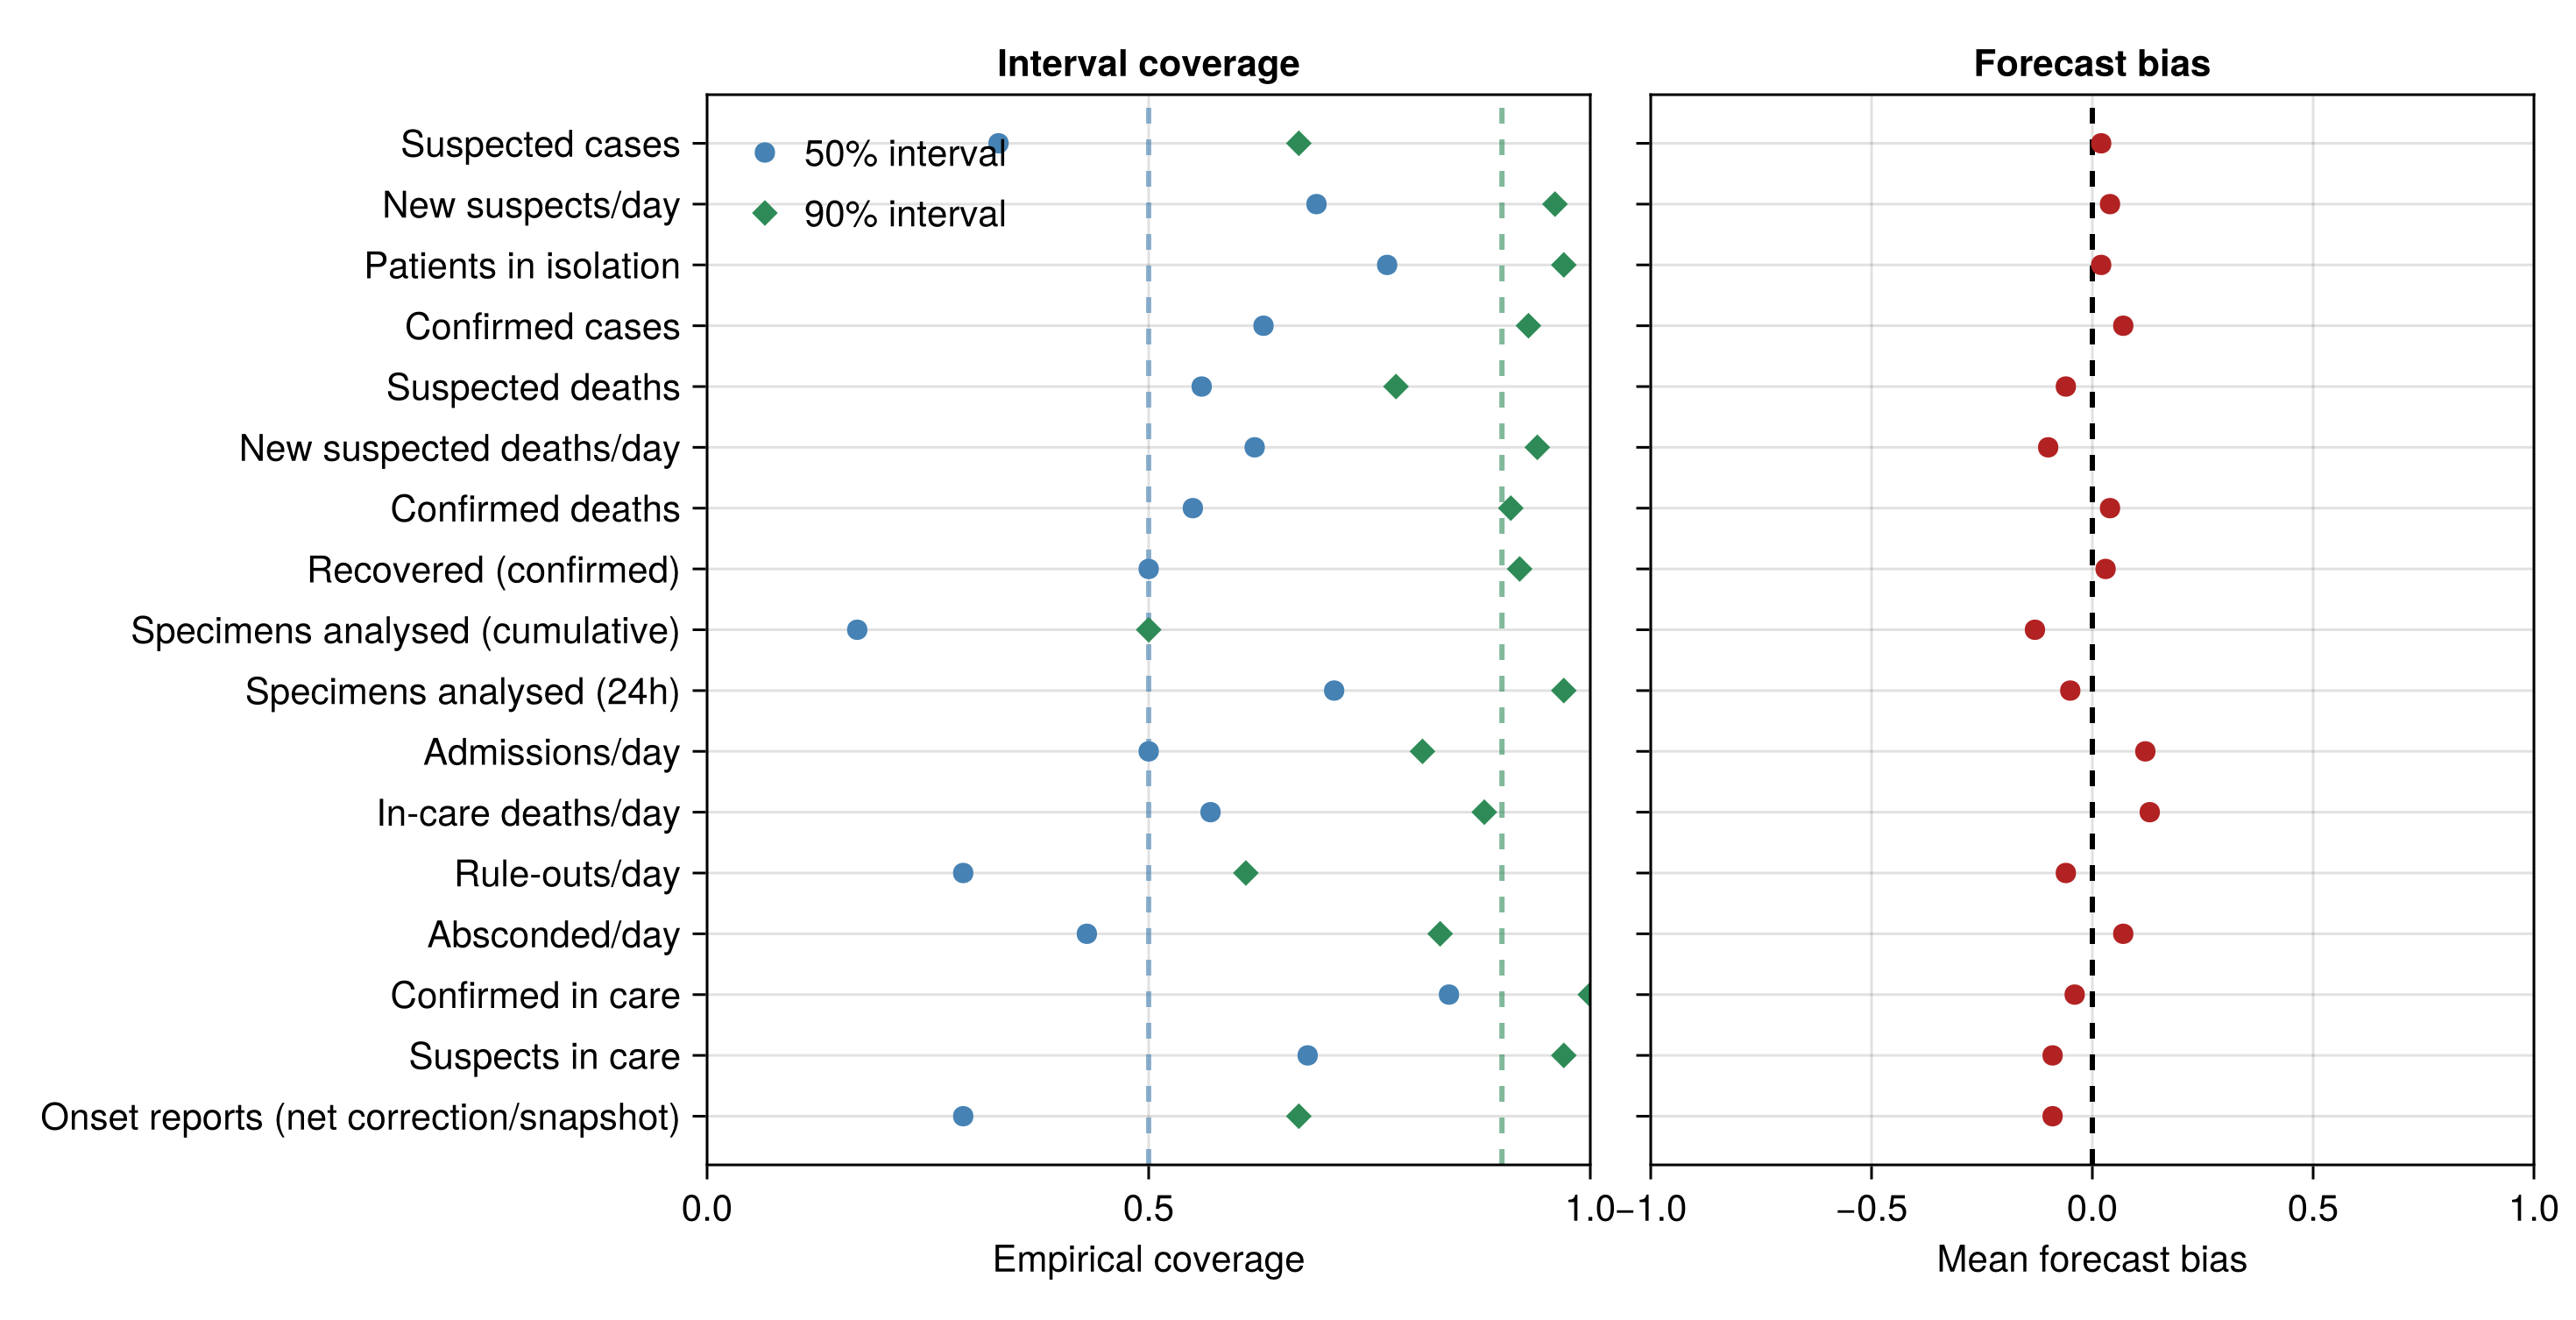
Per-stream calibration table
| Row | Stream | Vintages | Bias | 50% coverage | 90% coverage |
|---|---|---|---|---|---|
| String | Int64 | Float64 | Float64 | Float64 | |
| 1 | Suspected cases | 9 | 0.02 | 0.33 | 0.67 |
| 2 | New suspects/day | 108 | 0.04 | 0.69 | 0.96 |
| 3 | Patients in isolation | 69 | 0.02 | 0.77 | 0.97 |
| 4 | Confirmed cases | 126 | 0.07 | 0.63 | 0.93 |
| 5 | Suspected deaths | 9 | -0.06 | 0.56 | 0.78 |
| 6 | New suspected deaths/day | 32 | -0.1 | 0.62 | 0.94 |
| 7 | Confirmed deaths | 128 | 0.04 | 0.55 | 0.91 |
| 8 | Recovered (confirmed) | 107 | 0.03 | 0.5 | 0.92 |
| 9 | Specimens analysed (cumulative) | 6 | -0.13 | 0.17 | 0.5 |
| 10 | Specimens analysed (24h) | 109 | -0.05 | 0.71 | 0.97 |
| 11 | Admissions/day | 42 | 0.12 | 0.5 | 0.81 |
| 12 | In-care deaths/day | 42 | 0.13 | 0.57 | 0.88 |
| 13 | Rule-outs/day | 41 | -0.06 | 0.29 | 0.61 |
| 14 | Absconded/day | 42 | 0.07 | 0.43 | 0.83 |
| 15 | Confirmed in care | 38 | -0.04 | 0.84 | 1.0 |
| 16 | Suspects in care | 38 | -0.09 | 0.68 | 0.97 |
| 17 | Onset reports (net correction/snapshot) | 52 | -0.09 | 0.29 | 0.67 |
Exports
Whether the modelled Uganda export and export-death totals match the observed ones.
Scalar posterior predictive plot
# The dated counts are nested under their submodel prefix as a single
# per-day count vector `<prefix>.counts`; look it up by its VarName with
# `Prefixed` (matching the key by its `<obs>.counts` tail) so the
# deterministic `expected_*_T` quantities cannot be picked up by a loose
# substring, then sum each replicate's per-day vector into the total.
function _dated_total(pp, vn)
    return [sum(v) for v in vec(Array(pp[_Prefixed(vn)]))]
end;

pp_exports = _dated_total(pp_joint, @varname(export_obs.counts));
pp_exports_deaths = _dated_total(
    pp_joint, @varname(death_obs.counts)
);

joint_ppc_fig = plot_posterior_predictive(
    pp_exports, nothing,
    obs.exported_cases, nothing;
    pp_exports_deaths = pp_exports_deaths,
    obs_exports_deaths = obs.exports_deaths
);
Onset snapshot nowcasts
Whether the fitted reporting delay nowcasts each digitised onset snapshot to the latest figure covering its dates (see the symptom-onset reporting delay Methods section).
Nowcasts of the digitised reporting-triangle snapshots
# Each snapshot's own printed counts, read from the source blocks since the
# fitted stream holds only the corrections between snapshots.
_onset_readings = onset_snapshot_readings()
_onset_snap_by_day = Dict(
    obs.n - value(obs.cutoff - b.report_date) => b
        for b in _onset_readings.snaps
)
_onset_cells_by_report = Dict{Int, Vector{Int}}()
for (i, r) in enumerate(obs.onset_curve_history.report_days)
    push!(get!(_onset_cells_by_report, r, Int[]), i)
end
_onset_hazard = fitted_onset_hazard(fit_model("joint"), chn_joint)
_onset_daily_draws = onset_daily_draws(chn_joint)
_onset_replicated = onset_bar_replicator(
    chn_joint, Random.MersenneTwister(20260729)
)

# Each snapshot is nowcast to the delay of the figure each of its onset
# dates was last printed on, so the band and the latest reading are the
# same quantity.
_onset_panels = map(sort(collect(keys(_onset_cells_by_report)))) do R
    snap = _onset_snap_by_day[R]
    us = sort(obs.onset_curve_history.onset_days[_onset_cells_by_report[R]])
    observed = Float64[get(snap.onsets, grid_date(u), 0) for u in us]
    nowcast = onset_nowcast_draws(
        us, observed, [R - u for u in us],
        _onset_daily_draws, _onset_hazard; grid_start = _onset_grid_start,
        target_delays = [_onset_readings.last_report_day[u] - u for u in us]
    )
    (;
        title = string(snap.report_date), dates = grid_date.(us), observed,
        nowcast = [_onset_replicated(d) for d in nowcast],
        latest = [_onset_readings.last_printed[u] for u in us],
    )
end

onset_fit_fig = plot_onset_nowcast_grid(_onset_panels);
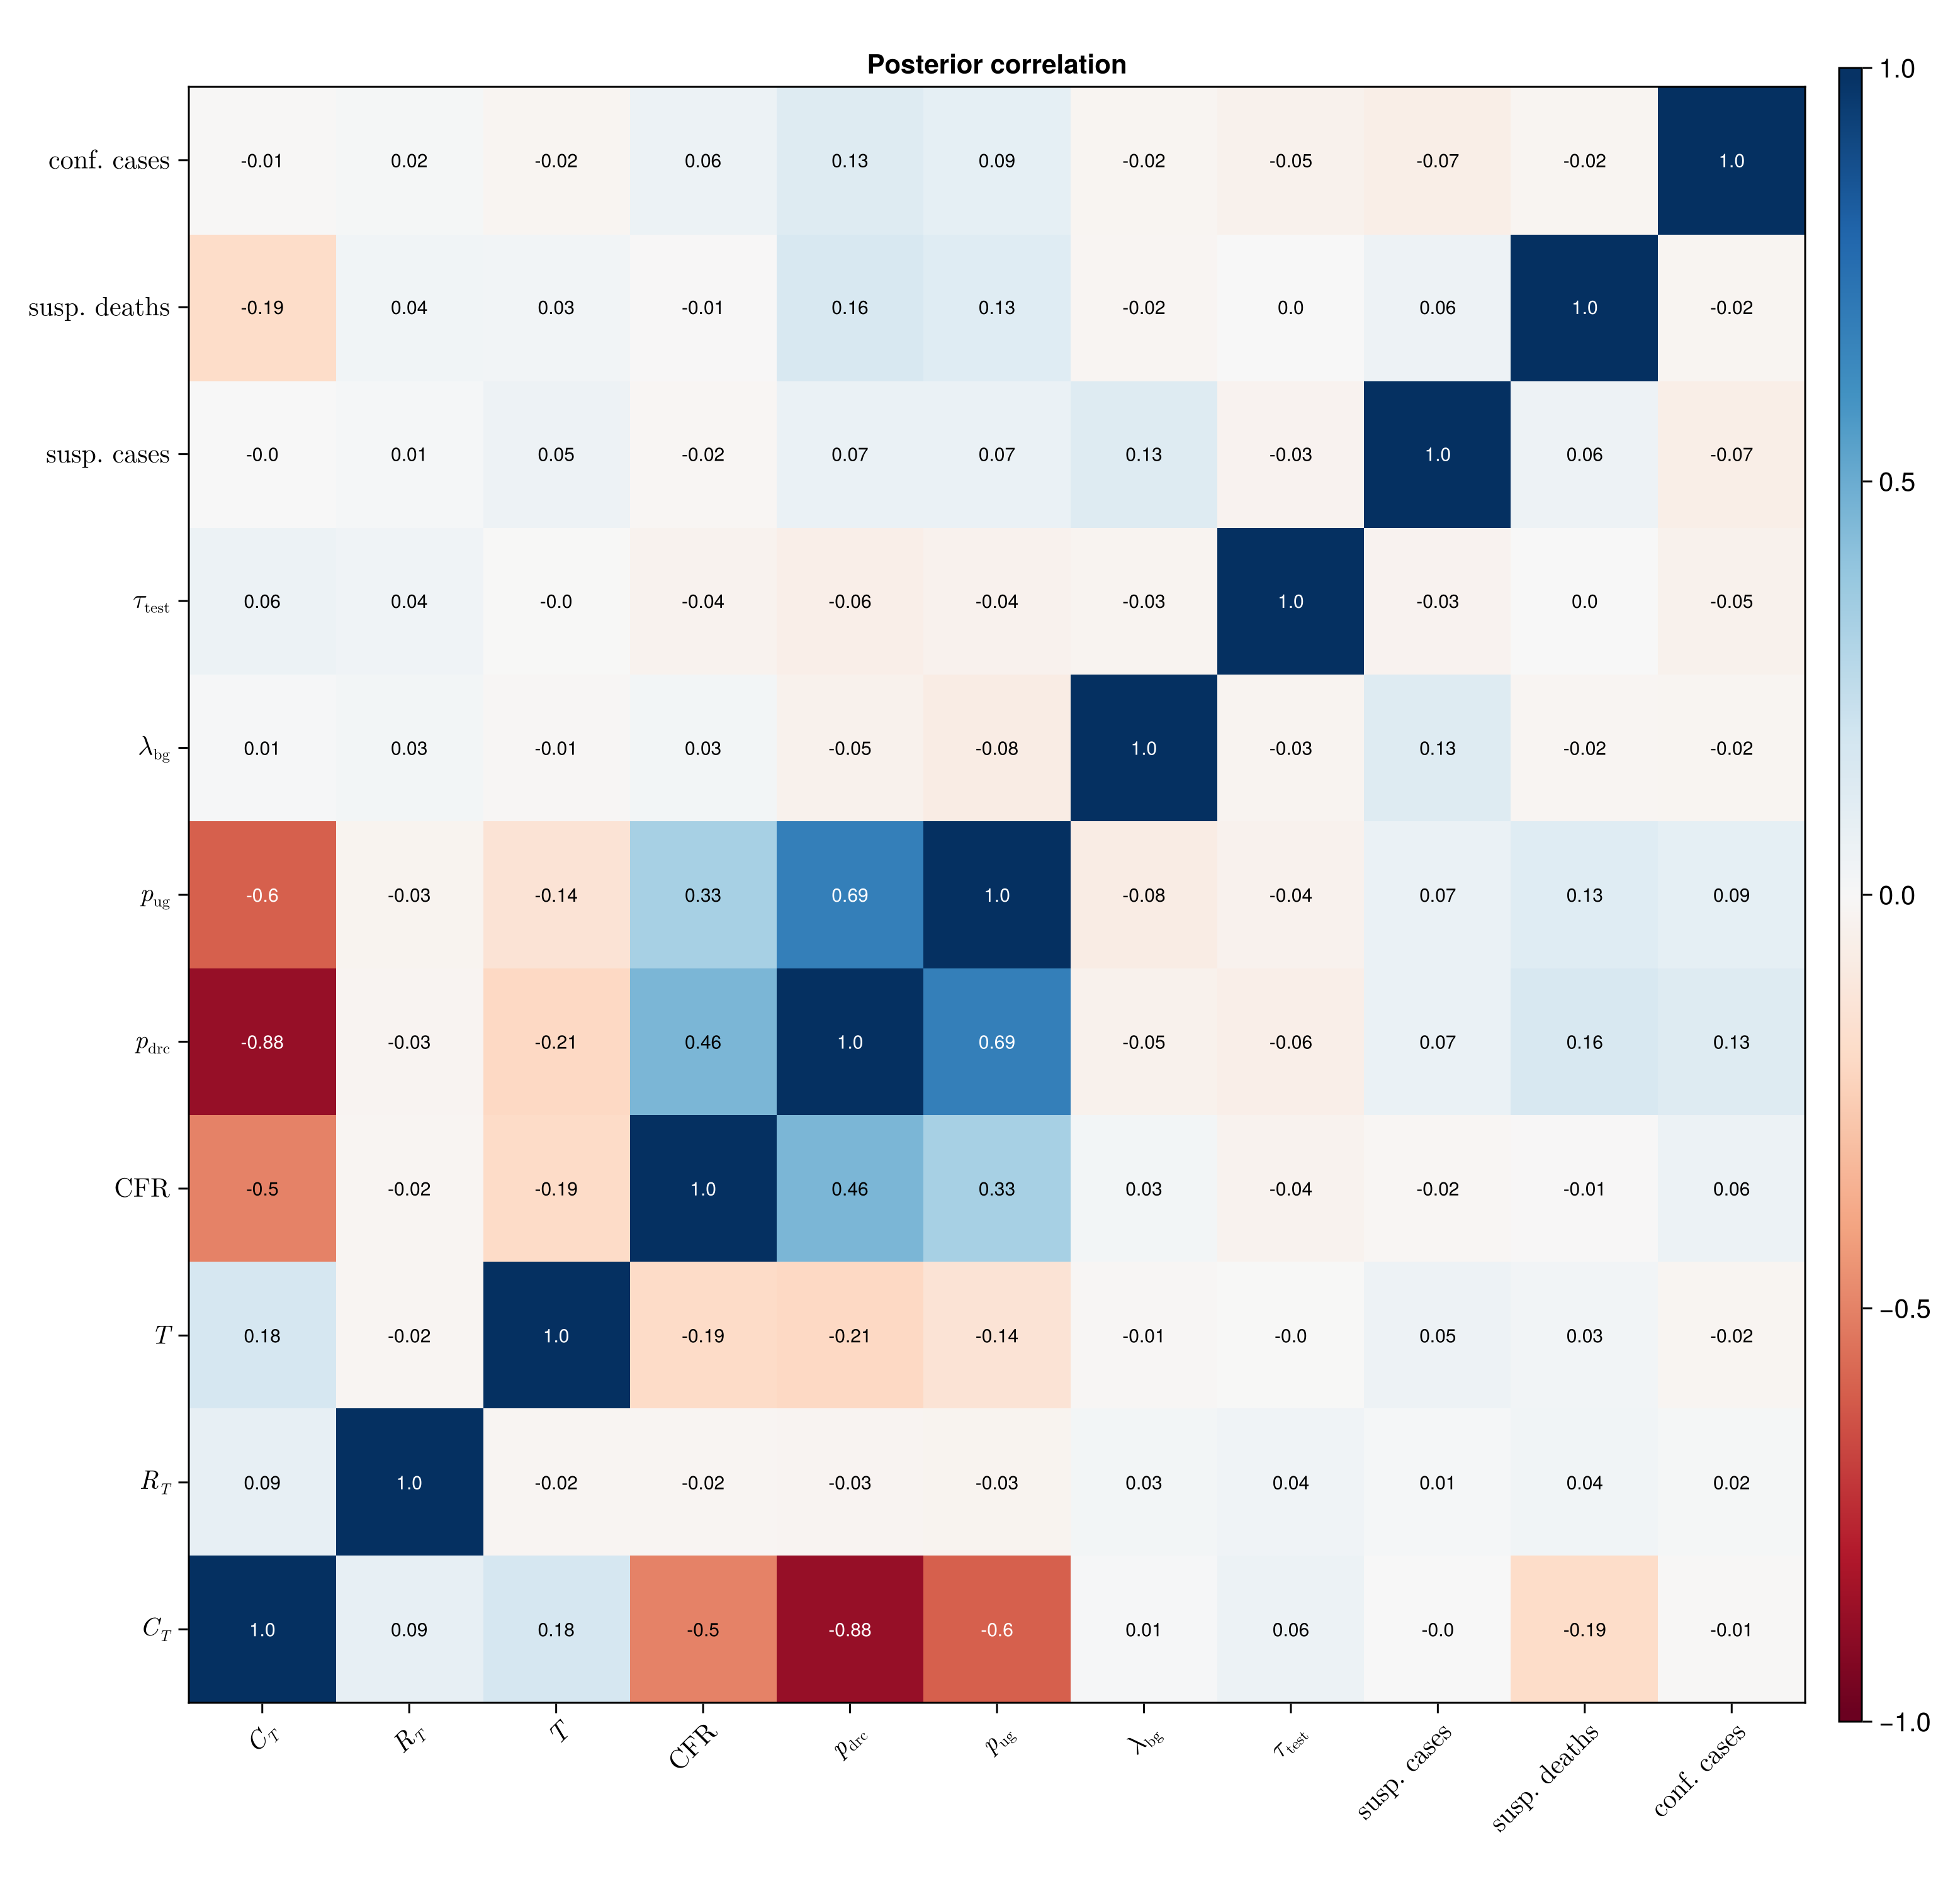
Posterior correlations and stream totals
Which headline quantities trade off against each other, and whether the stream totals match the observed ones.
Posterior correlation heatmap
correlation_fig = plot_correlation_heatmap(
    chn_joint,
    [
        :C_T, :R_T, :T, :CFR, :p_drc, :p_uganda, :lambda_bg, :tau_test,
        :expected_reports_T, :expected_deaths_T, :expected_confirmed_T,
    ];
    labels = Dict(
        :C_T => raw"C_T", :R_T => raw"R_T", :T => raw"T",
        :CFR => raw"\mathrm{CFR}", :p_drc => raw"p_\mathrm{drc}",
        :p_uganda => raw"p_\mathrm{ug}", :lambda_bg => raw"\lambda_\mathrm{bg}",
        :tau_test => raw"\tau_\mathrm{test}",
        :expected_reports_T => raw"\mathrm{susp.\ cases}",
        :expected_deaths_T => raw"\mathrm{susp.\ deaths}",
        :expected_confirmed_T => raw"\mathrm{conf.\ cases}"
    )
);
Stream totals against observed
# Per-draw modelled total of each stream, summed over its own reporting
# vintages (the confirmed total adds the unscored first-vintage baseline),
# reusing the posterior-predictive replicates built for the vintage panels.
_stream_total(reps) = [sum(Float64.(collect(r))) for r in vec(reps)]
_conf_baseline = isempty(obs.confirmed_history.counts) ? 0 :
    Int(obs.confirmed_history.counts[1])
stream_totals = (;
    suspected_cases = _stream_total(reported_panel.replicates),
    suspected_deaths = _stream_total(deaths_panel.replicates),
    confirmed_cases = _stream_total(confirmed_panel.replicates) .+ _conf_baseline,
    confirmed_deaths = _stream_total(confirmed_deaths_panel.replicates),
    analysed = _stream_total(tests_analysed_panel.replicates),
);
stream_observed = (;
    suspected_cases = Float64(obs.reported_history.counts[end]),
    suspected_deaths = Float64(obs.deaths_history.counts[end]),
    confirmed_cases = Float64(obs.confirmed_cases),
    confirmed_deaths = Float64(obs.confirmed_deaths_history.counts[end]),
    analysed = Float64(obs.lab_history.counts[end]),
);
stream_pairs_fig = plot_stream_pairs(stream_totals, stream_observed);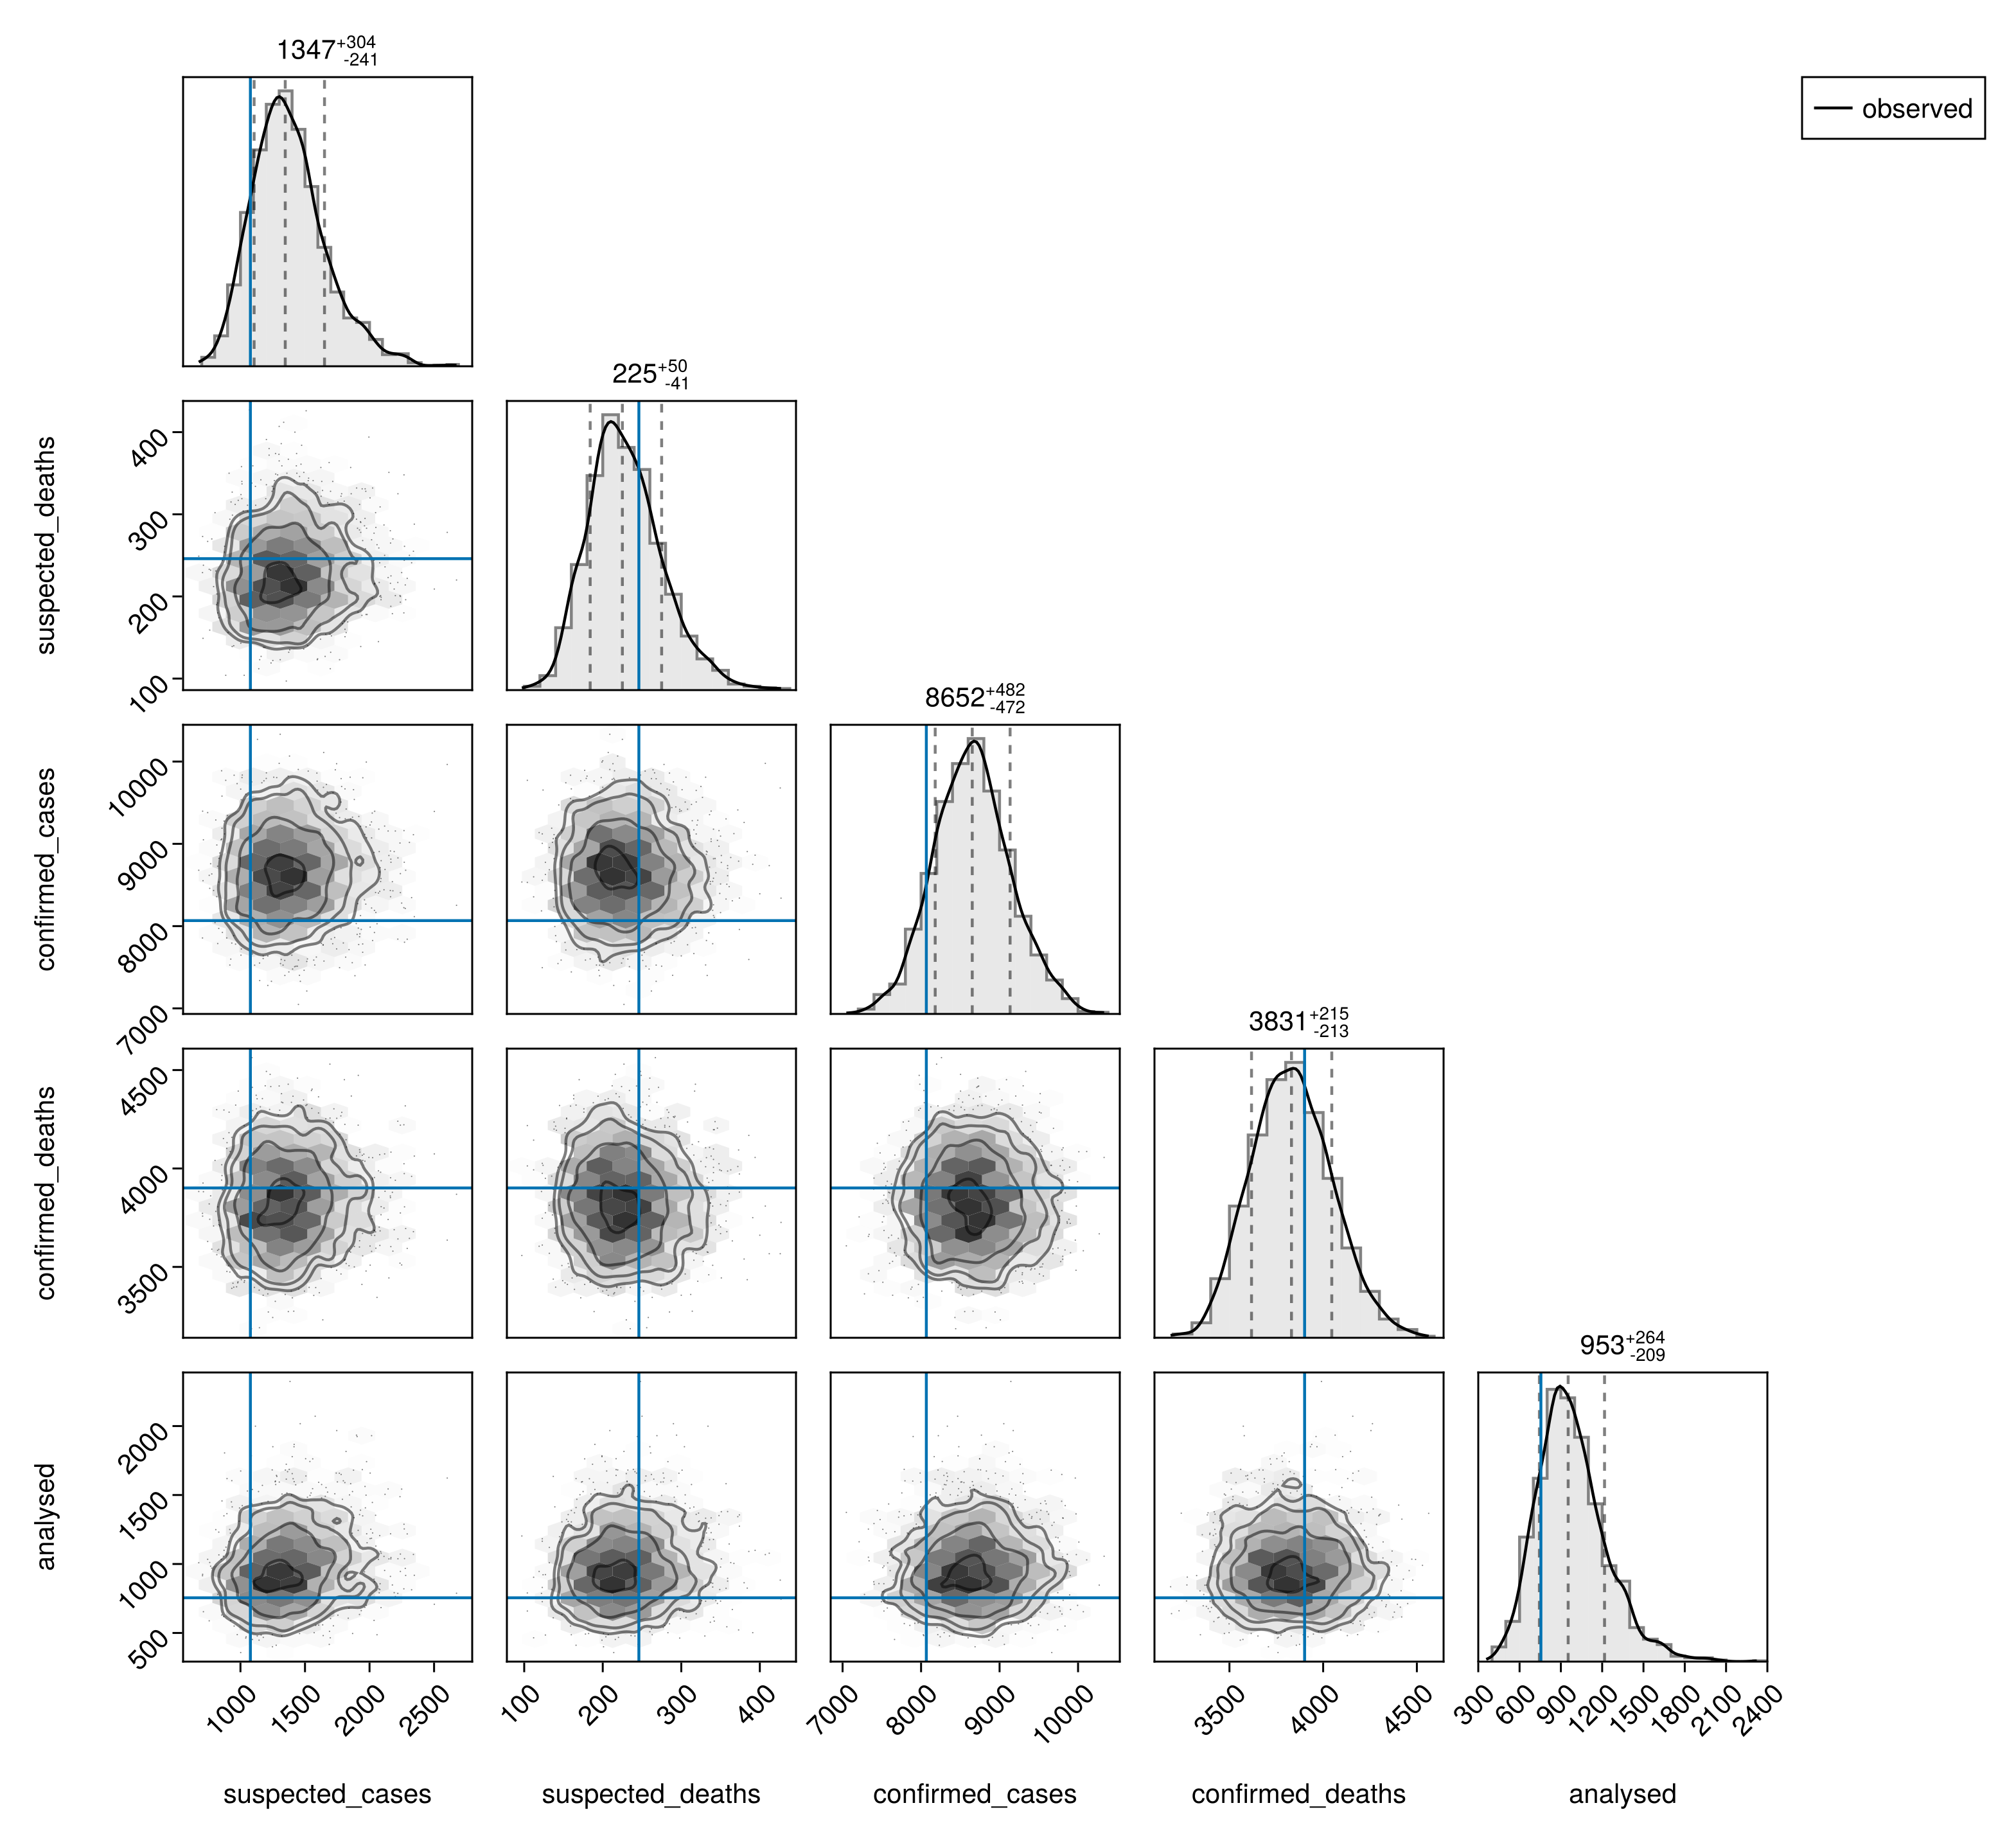
Parameter recovery
Whether the model recovers known values when fitted to data it simulated itself. Each seed is one prior draw of the model run past the cut-off, kept when its outbreak size is within a factor of five of the one observed, and fitted with the headline joint's sampler settings. The top panel shows each seed's posterior median with its 50% and 90% intervals divided by that seed's true value, so a recovered quantity straddles the line at one. The growth rate is shown as the ratio of daily growth factors,
Recovery figure
recovery = recovery_results()
recovery_national_quantities = [
    "C_T", "T", "R_T", "r", "CFR", "p_drc", "tau_test", "lambda_bg",
    "growth_state.G", "rt_state.sigma_rw", "onset_report_state.τ",
    "rt_state.intervention_effect",
]
recovery_labels = Dict(
    "growth_state.G" => "G", "rt_state.sigma_rw" => "Rt step size",
    "onset_report_state.τ" => "onset read SD",
    "rt_state.intervention_effect" => "intervention effect",
)
recovery_fig = isempty(recovery.params) ? nothing : plot_recovery(
        recovery.params, recovery.draws, recovery.prior;
        quantities = recovery_national_quantities,
        labels = merge(
            recovery_labels,
            Dict(
                "r" => "r (as exp(r))",
                "rt_state.intervention_effect" => "intervention effect (as exp)",
            )
        ),
        panel_labels = merge(recovery_labels, Dict("r" => "r")),
        log_x = ["C_T", "lambda_bg"],
        difference = ["r", "rt_state.intervention_effect"]
    );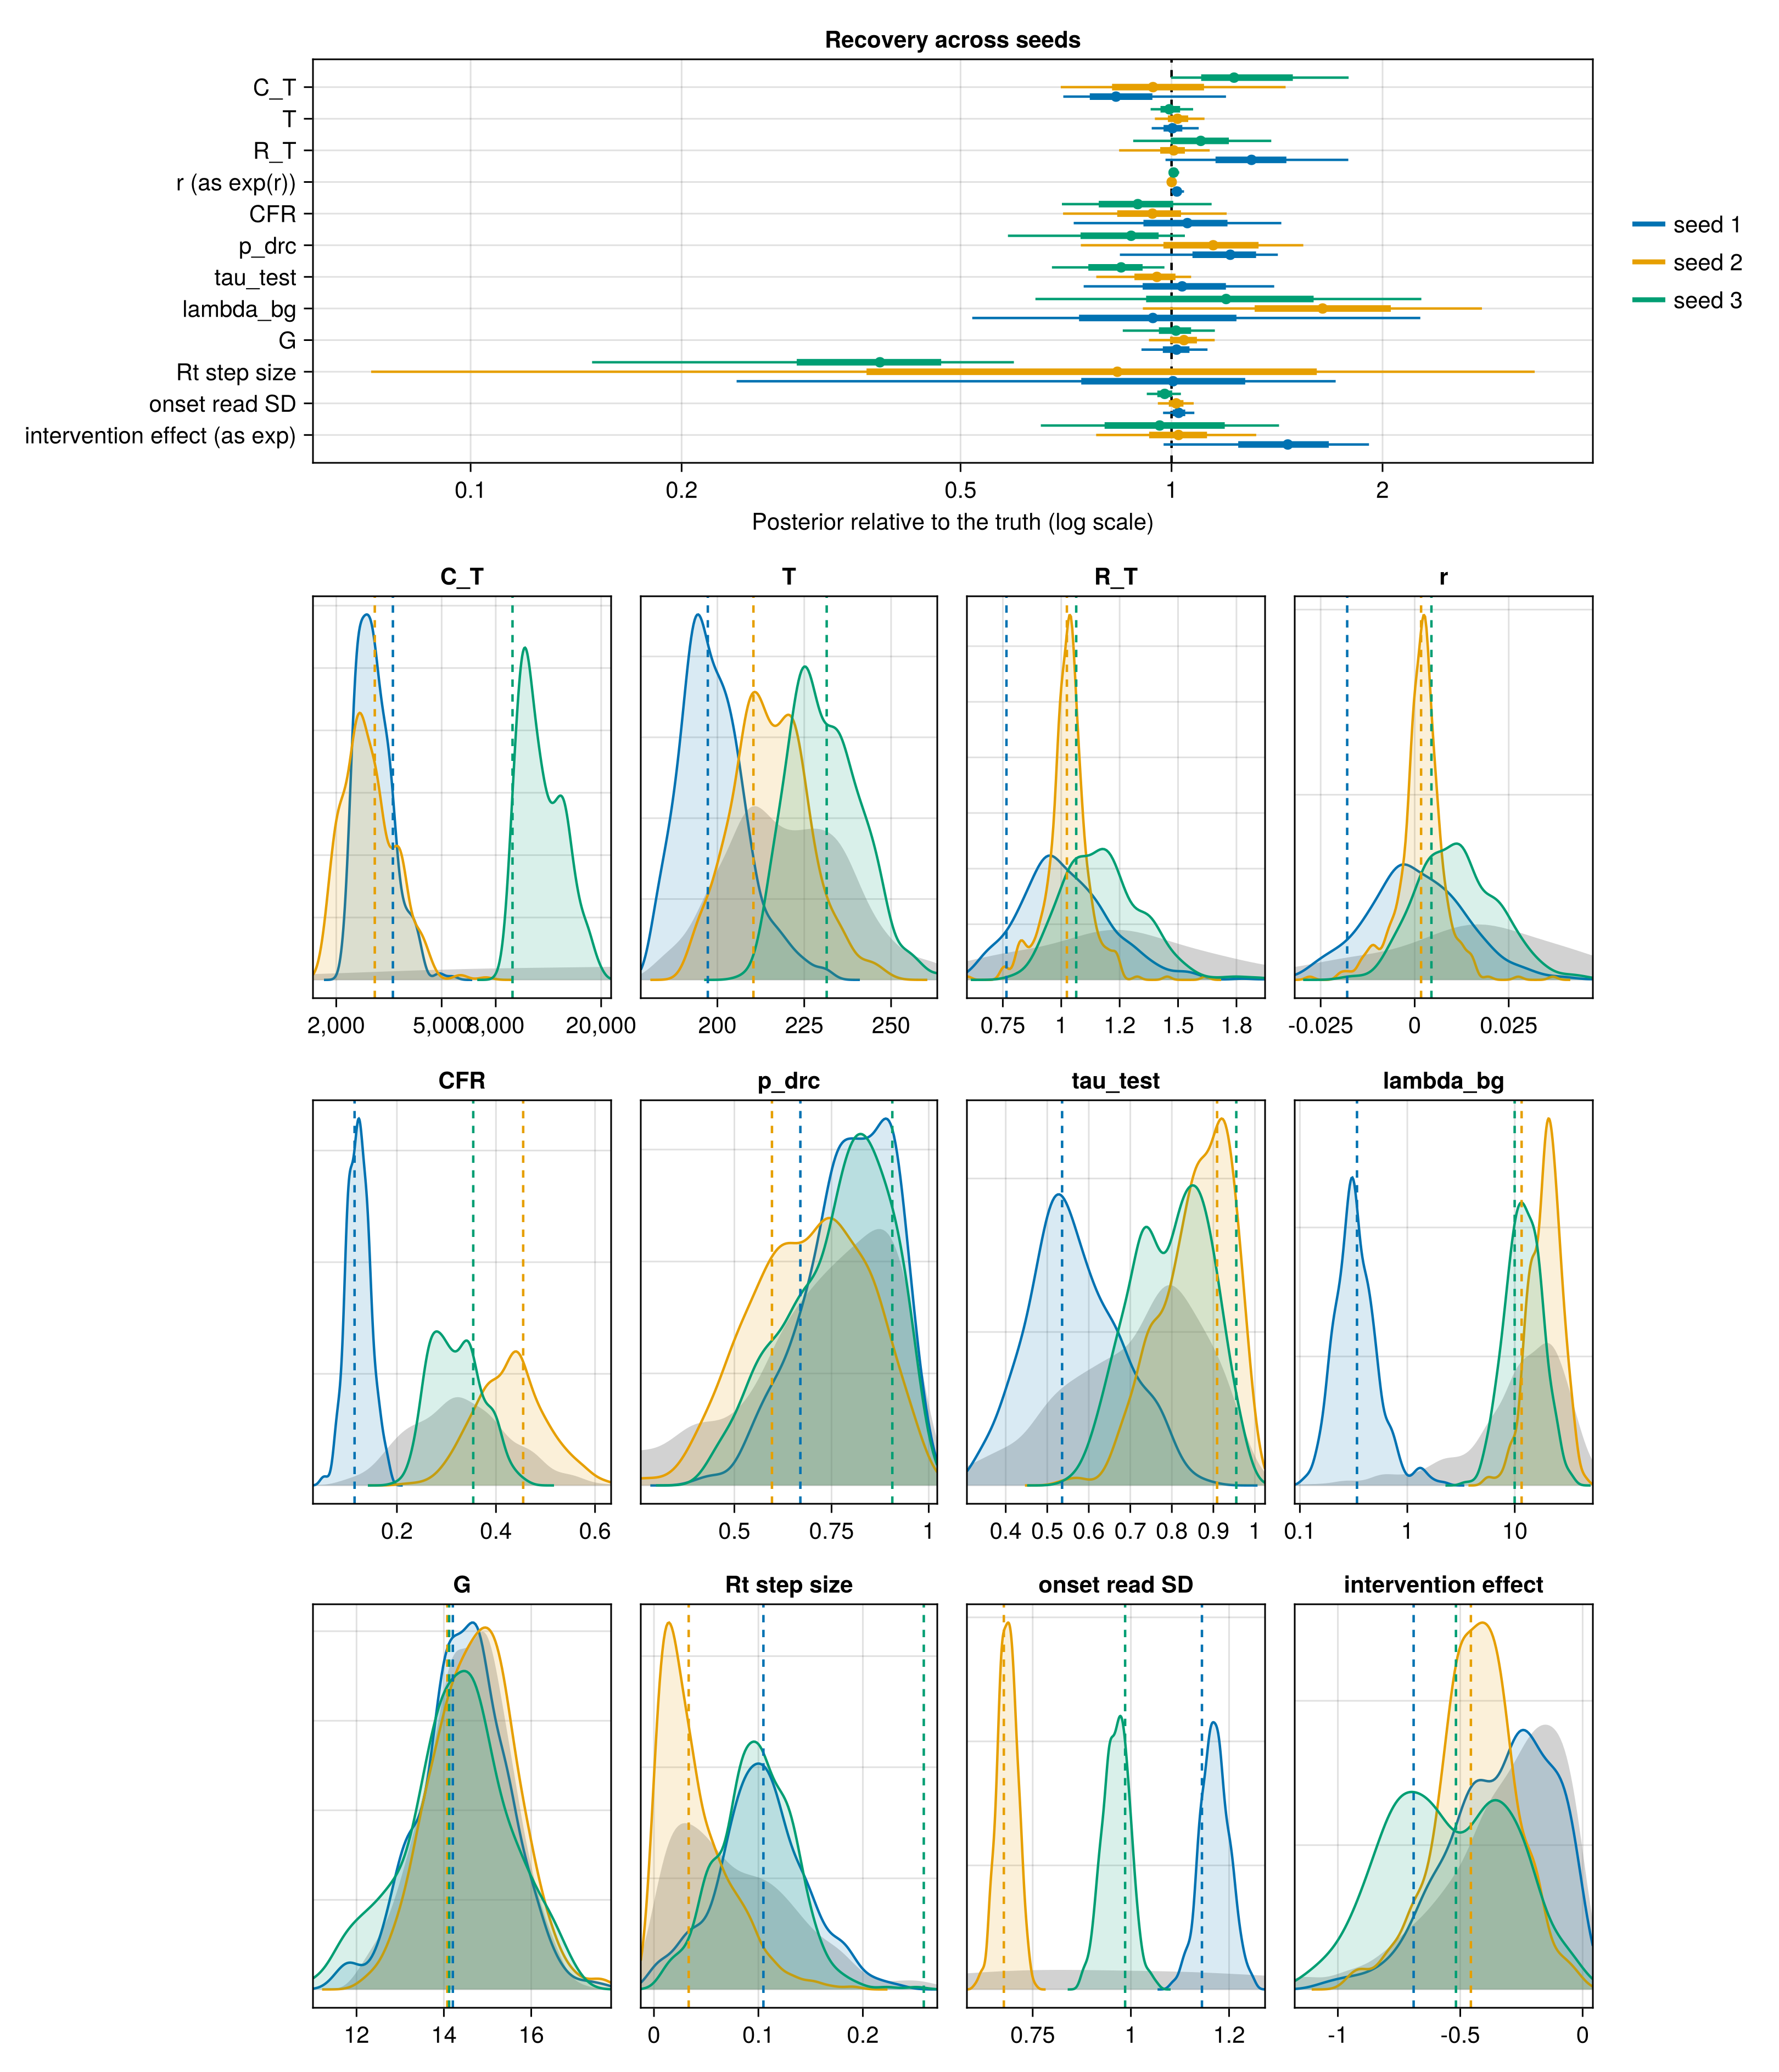
The error of each seed's posterior median relative to the truth, and the z-score of the truth, summarised across seeds.
Summary table across seeds
recovery_summary_national = isempty(recovery.params) ? DataFrame() :
    recovery_summary_table(recovery.params; province = false);

recovery_summary_national_display = isempty(recovery_summary_national) ?
    Markdown.parse("No parameter-recovery run is available for this build.") :
MarkdownTable(recovery_summary_national);| Quantity | Truth, lowest | Truth, highest | Relative error, median | Relative error, range | z, median | Truth in 90% | Outside 99% |
|---|---|---|---|---|---|---|---|
| CFR | 0.115 | 0.455 | -0.06 | -0.1 to 0.05 | -0.41 | 3/3 | 0 |
| C_T | 2800 | 9260 | -0.06 | -0.17 to 0.23 | -0.04 | 3/3 | 0 |
| R_T | 0.766 | 1.06 | 0.1 | 0.01 to 0.3 | 0.67 | 3/3 | 0 |
| T | 197 | 231 | 0 | -0.01 to 0.02 | 0.17 | 3/3 | 0 |
| growth_state.G | 14.1 | 14.2 | 0.02 | 0.01 to 0.04 | 0.24 | 3/3 | 0 |
| lambda_bg | 0.34 | 11.6 | 0.2 | -0.06 to 0.64 | 0.58 | 3/3 | 0 |
| onset_report_state.τ | 0.677 | 1.18 | 0.02 | -0.02 to 0.02 | 0.43 | 3/3 | 0 |
| p_drc | 0.597 | 0.906 | 0.15 | -0.12 to 0.21 | 0.6 | 3/3 | 0 |
| r | -0.0179 | 0.00445 | 0.98 | 0.27 to 1.53 | 0.66 | 3/3 | 0 |
| rt_state.intervention_effect | -0.69 | -0.457 | 0.05 | -0.08 to 0.55 | 0.12 | 3/3 | 0 |
| rt_state.sigma_rw | 0.0333 | 0.258 | -0.16 | -0.62 to 0.01 | 0.01 | 2/3 | 1 |
| tau_test | 0.536 | 0.955 | -0.05 | -0.15 to 0.04 | -0.64 | 2/3 | 0 |
Each seed's fit and recovered values
recovery_seeds = isempty(recovery.params) ? DataFrame() :
    recovery_seed_verdicts(recovery.params);
recovery_national = isempty(recovery.params) ? DataFrame() :
    recovery.params[
        .!occursin.("[", recovery.params.quantity), [
            :seed, :quantity, :truth, :median, :lower_90, :upper_90, :covered_90,
        ],
    ];

recovery_seeds_display = isempty(recovery_seeds) ?
    Markdown.parse("No parameter-recovery run is available for this build.") :
    MarkdownTable(recovery_seeds);
recovery_national_display = isempty(recovery_national) ? Markdown.parse("") :
MarkdownTable(recovery_national);| seed | status | coverage_90 | outside | fit_minutes | max_rhat | min_ess_bulk | divergences |
|---|---|---|---|---|---|---|---|
| 1 | unconverged | 0.938 | 185.4 | 1.123 | 14.423 | 28 | |
| 2 | pass | 0.938 | 185.9 | 1.013 | 378.191 | 48 | |
| 3 | unconverged | 0.875 | rt_state.sigma_rw | 197.5 | 1.801 | 5.719 | 87 |
| seed | quantity | truth | median | lower_90 | upper_90 | covered_90 |
|---|---|---|---|---|---|---|
| 1 | CFR | 0.115 | 0.121 | 0.083 | 0.164 | true |
| 1 | C_T | 3272.552 | 2726.691 | 2293.29 | 3913.552 | true |
| 1 | R_T | 0.766 | 0.996 | 0.751 | 1.368 | true |
| 1 | T | 197.243 | 197.861 | 184.798 | 215.65 | true |
| 1 | growth_state.G | 14.205 | 14.442 | 12.869 | 15.986 | true |
| 1 | lambda_bg | 0.34 | 0.32 | 0.177 | 0.77 | true |
| 1 | onset_report_state.τ | 1.181 | 1.209 | 1.148 | 1.273 | true |
| 1 | p_drc | 0.67 | 0.812 | 0.565 | 0.95 | true |
| 1 | r | -0.0179 | -0.000311 | -0.0187 | 0.0231 | true |
| 1 | rt_state.intervention_effect | -0.69 | -0.309 | -0.717 | -0.0418 | true |
| 1 | rt_state.sigma_rw | 0.105 | 0.105 | 0.0251 | 0.18 | true |
| 1 | tau_test | 0.536 | 0.555 | 0.401 | 0.751 | true |
| 2 | CFR | 0.455 | 0.427 | 0.319 | 0.545 | true |
| 2 | C_T | 2795.76 | 2630.688 | 1942.849 | 4066.351 | true |
| 2 | R_T | 1.024 | 1.032 | 0.862 | 1.161 | true |
| 2 | T | 210.375 | 214.542 | 199.188 | 234.433 | true |
| 2 | growth_state.G | 14.079 | 14.665 | 13.073 | 16.224 | true |
| 2 | lambda_bg | 11.585 | 19.03 | 10.543 | 32.117 | true |
| 2 | onset_report_state.τ | 0.677 | 0.687 | 0.647 | 0.728 | true |
| 2 | p_drc | 0.597 | 0.684 | 0.443 | 0.92 | true |
| 2 | r | 0.0017 | 0.00216 | -0.00984 | 0.0103 | true |
| 2 | rt_state.intervention_effect | -0.457 | -0.434 | -0.704 | -0.178 | true |
| 2 | rt_state.sigma_rw | 0.0333 | 0.0278 | 0.0024 | 0.11 | true |
| 2 | tau_test | 0.909 | 0.866 | 0.71 | 0.969 | true |
| 3 | CFR | 0.354 | 0.317 | 0.247 | 0.404 | true |
| 3 | C_T | 9256.133 | 11365.974 | 9243.153 | 16560.101 | true |
| 3 | R_T | 1.064 | 1.171 | 0.938 | 1.477 | true |
| 3 | T | 231.463 | 229.776 | 216.094 | 248.456 | true |
| 3 | growth_state.G | 14.121 | 14.329 | 12.03 | 16.28 | true |
| 3 | lambda_bg | 9.978 | 11.938 | 6.381 | 22.67 | true |
| 3 | onset_report_state.τ | 0.985 | 0.963 | 0.908 | 1.016 | true |
| 3 | p_drc | 0.906 | 0.794 | 0.53 | 0.947 | true |
| 3 | r | 0.00445 | 0.0112 | -0.0049 | 0.0297 | true |
| 3 | rt_state.intervention_effect | -0.518 | -0.557 | -0.947 | -0.164 | true |
| 3 | rt_state.sigma_rw | 0.258 | 0.0991 | 0.0385 | 0.154 | false |
| 3 | tau_test | 0.955 | 0.809 | 0.645 | 0.933 | false |
Forecast scores from the recovery fits
recovery_forecasts = isempty(recovery.forecasts) ? DataFrame() :
    recovery.forecasts[
        :, [
            :seed, :horizon, :quantity, :truth, :baseline, :crps, :baseline_crps,
            :relative_crps, :covered_90,
        ],
    ];

recovery_forecasts_display = isempty(recovery_forecasts) ?
    Markdown.parse("No recovery forecast is available for this build.") :
MarkdownTable(recovery_forecasts);| seed | horizon | quantity | truth | baseline | crps | baseline_crps | relative_crps | covered_90 |
|---|---|---|---|---|---|---|---|---|
| 1 | 7 | confirmed_deaths_new | 3 | 1 | 1.155 | 2 | 0.578 | true |
| 1 | 7 | confirmed_new | 32 | 2810 | 17.668 | 2778 | 0.00636 | false |
| 1 | 14 | confirmed_deaths_new | 4 | 8 | 4.278 | 4 | 1.069 | false |
| 1 | 14 | confirmed_new | 44 | 5366 | 59.182 | 5322 | 0.0111 | false |
| 2 | 7 | confirmed_deaths_new | 64 | 46 | 6.434 | 18 | 0.357 | true |
| 2 | 7 | confirmed_new | 73 | 1685 | 18.929 | 1612 | 0.0117 | true |
| 2 | 14 | confirmed_deaths_new | 144 | 110 | 19.373 | 34 | 0.57 | true |
| 2 | 14 | confirmed_new | 299 | 3336 | 56.585 | 3037 | 0.0186 | true |
| 3 | 7 | confirmed_deaths_new | 120 | 179 | 41.043 | 59 | 0.696 | true |
| 3 | 7 | confirmed_new | 344 | 2373 | 83.951 | 2029 | 0.0414 | true |
| 3 | 14 | confirmed_deaths_new | 432 | 258 | 34.307 | 174 | 0.197 | true |
| 3 | 14 | confirmed_new | 829 | 4552 | 106.066 | 3723 | 0.0285 | true |
Saving in-sample outputs
Write the summary bullets
dashboard_dir = joinpath(
    pkgdir(BVDOutbreakSize), "docs", "src", "summary_assets"
)
mkpath(dashboard_dir)

# The bullets under the summary heading at the top of the page. They read
# tables built further down, so they are written here and read back when
# the site is assembled.
evaluation_insample_national_summary = let
    fmt(x) = ismissing(x) || !isfinite(x) ? "n/a" :
        string(round(x; digits = 2))
    cal = filter(r -> isfinite(r["90% coverage"]), stream_calibration_table)
    n_cov = count(>=(0.8), cal[!, "90% coverage"])
    calibrated(r) = string(
        r["Stream"], " (bias ", fmt(r["Bias"]), ", 90% coverage ",
        fmt(r["90% coverage"]), ")"
    )
    worst = first(
        sort(cal, "Bias"; by = abs, rev = true), min(3, size(cal, 1))
    )
    pred(x, observed) = string(
        "observed ", observed, " against a predictive median of ",
        round(Int, quantile(x, 0.5)), " (90% interval ",
        round(Int, quantile(x, 0.05)), "–",
        round(Int, quantile(x, 0.95)), ")"
    )
    overall = [
        string(
            "- **Streams:** ", n_cov, " of ", size(cal, 1),
            " fitted streams have 90% coverage of at least 0.8."
        ),
        string(
            "- **Least well reproduced:** ",
            join(calibrated.(eachrow(worst)), "; "), "."
        ),
        string(
            "- **Exports:** Uganda exports ",
            pred(pp_exports, obs.exported_cases), ", and export deaths ",
            pred(pp_exports_deaths, obs.exports_deaths), "."
        ),
    ]
    # Per stream, split the same way as the posterior predictive checks.
    reporting = Set(p.title for p in reporting_panels)
    function block(lead, keep)
        rows = filter(r -> keep(r["Stream"] in reporting), cal)
        size(rows, 1) == 0 && return nothing
        return join(
            vcat(
                [string("**", lead, "**"), ""],
                [
                    string(
                        "- ", r["Stream"], ": bias ", fmt(r["Bias"]),
                        ", 90% coverage ", fmt(r["90% coverage"]), " over ",
                        r["Vintages"], " vintages."
                    )
                        for r in eachrow(rows)
                ]
            ), "\n"
        )
    end
    blocks = filter(
        !isnothing,
        [
            block("Streams still reporting", identity),
            block("Streams no longer reporting", !),
        ]
    )
    join(vcat([join(overall, "\n")], blocks), "\n\n")
end
write(
    joinpath(dashboard_dir, "evaluation_insample_national.md"),
    evaluation_insample_national_summary
);