Sensitivity and comparison analyses
It renders from the same fitted chains as the main analysis, loaded through the shared setup, so no model is re-fit here beyond the frozen re-fits and the optional sensitivity re-fits below.
Load packages, data and fitted chains
# Shared setup: packages, observations and the fit registry. See
# docs/pages/_setup.jl.
using BVDOutbreakSize
include(joinpath(pkgdir(BVDOutbreakSize), "docs", "pages", "_setup.jl"))
validation_forecast_from (generic function with 1 method)# The fits this page reads, loaded from the cache here.
# The headline joint is the patch (meta-population) model over the
# provinces. `sens_no_patches` is the same model with `n_patches = 1`,
# fitted as the check on the spatial structure.
chn_joint = load_fit("joint")
chn_no_patches = load_fit("sens_no_patches")
chn_exports = load_fit("exports")
chn_deaths = load_fit("deaths")
chn_cases = load_fit("cases")
chn_confirmed = load_fit("confirmed")
chn_confirmed_deaths = load_fit("confirmed_deaths")
chn_treatment = load_fit("treatment")
chn_onsets = load_fit("onsets")
frozen_lastweek = load_fit("frozen_validation")
frozen_by_cutoff = frozen_fits_by_cutoff()
frozen_C(c) = vec(Array(frozen_by_cutoff[c].chn[:C_T]))
# Every frozen fit is a full joint fit, so it carries the same walk base
# chn_joint does.
frozen_R0(c) = r0_walk_draws(frozen_by_cutoff[c].chn)
if RUN_SENSITIVITY
chn_joint_community_delay = load_fit("sens_community_delay")
chn_joint_exp_growth_clock = load_fit("sens_exp_growth_clock")
end
posterior_C_joint = vec(Array(chn_joint[:C_T]))
posterior_C_no_patches = vec(Array(chn_no_patches[:C_T]))
posterior_C_exports = vec(Array(chn_exports[:C_T]))
posterior_C_deaths = vec(Array(chn_deaths[:C_T]))
posterior_C_cases = vec(Array(chn_cases[:C_T]))
posterior_C_confirmed = vec(Array(chn_confirmed[:C_T]))
posterior_C_treatment = vec(Array(chn_treatment[:C_T]))
posterior_C_onsets = vec(Array(chn_onsets[:C_T]));The one-week-ahead forecasts, their validation against what arrived and their scoring against a persistence baseline are on the forecasts page.
National
Outbreak size estimated by each data stream
The table below puts the posteriors over the infection count side by side, the single-stream fits and the joint, to show what each stream implies alone and what the joint adds.
Per-stream infection-count table
streams_C_table = streams_table(
    "exports" => posterior_C_exports,
    "deaths (DRC)" => posterior_C_deaths,
    "cases (DRC)" => posterior_C_cases,
    "confirmed (DRC)" => posterior_C_confirmed,
    "isolation (DRC)" => posterior_C_treatment,
    "onsets (DRC)" => posterior_C_onsets,
    "joint" => posterior_C_joint
);| Stream | Lower 90% | Lower 60% | Lower 30% | Upper 30% | Upper 60% | Upper 90% |
|---|---|---|---|---|---|---|
| exports | 4248 | 24506 | 80892 | 719726 | 3109798 | 22354739 |
| deaths (DRC) | 31932 | 63948 | 95607 | 201081 | 313782 | 892193 |
| cases (DRC) | 42925 | 47013 | 51084 | 64917 | 79021 | 141745 |
| confirmed (DRC) | 58101 | 69297 | 79712 | 107751 | 135436 | 209030 |
| isolation (DRC) | 12635 | 14365 | 15789 | 19783 | 24063 | 40367 |
| onsets (DRC) | 19926 | 36615 | 49960 | 84735 | 120837 | 253627 |
| joint | 12343 | 14887 | 16593 | 20232 | 22555 | 27006 |
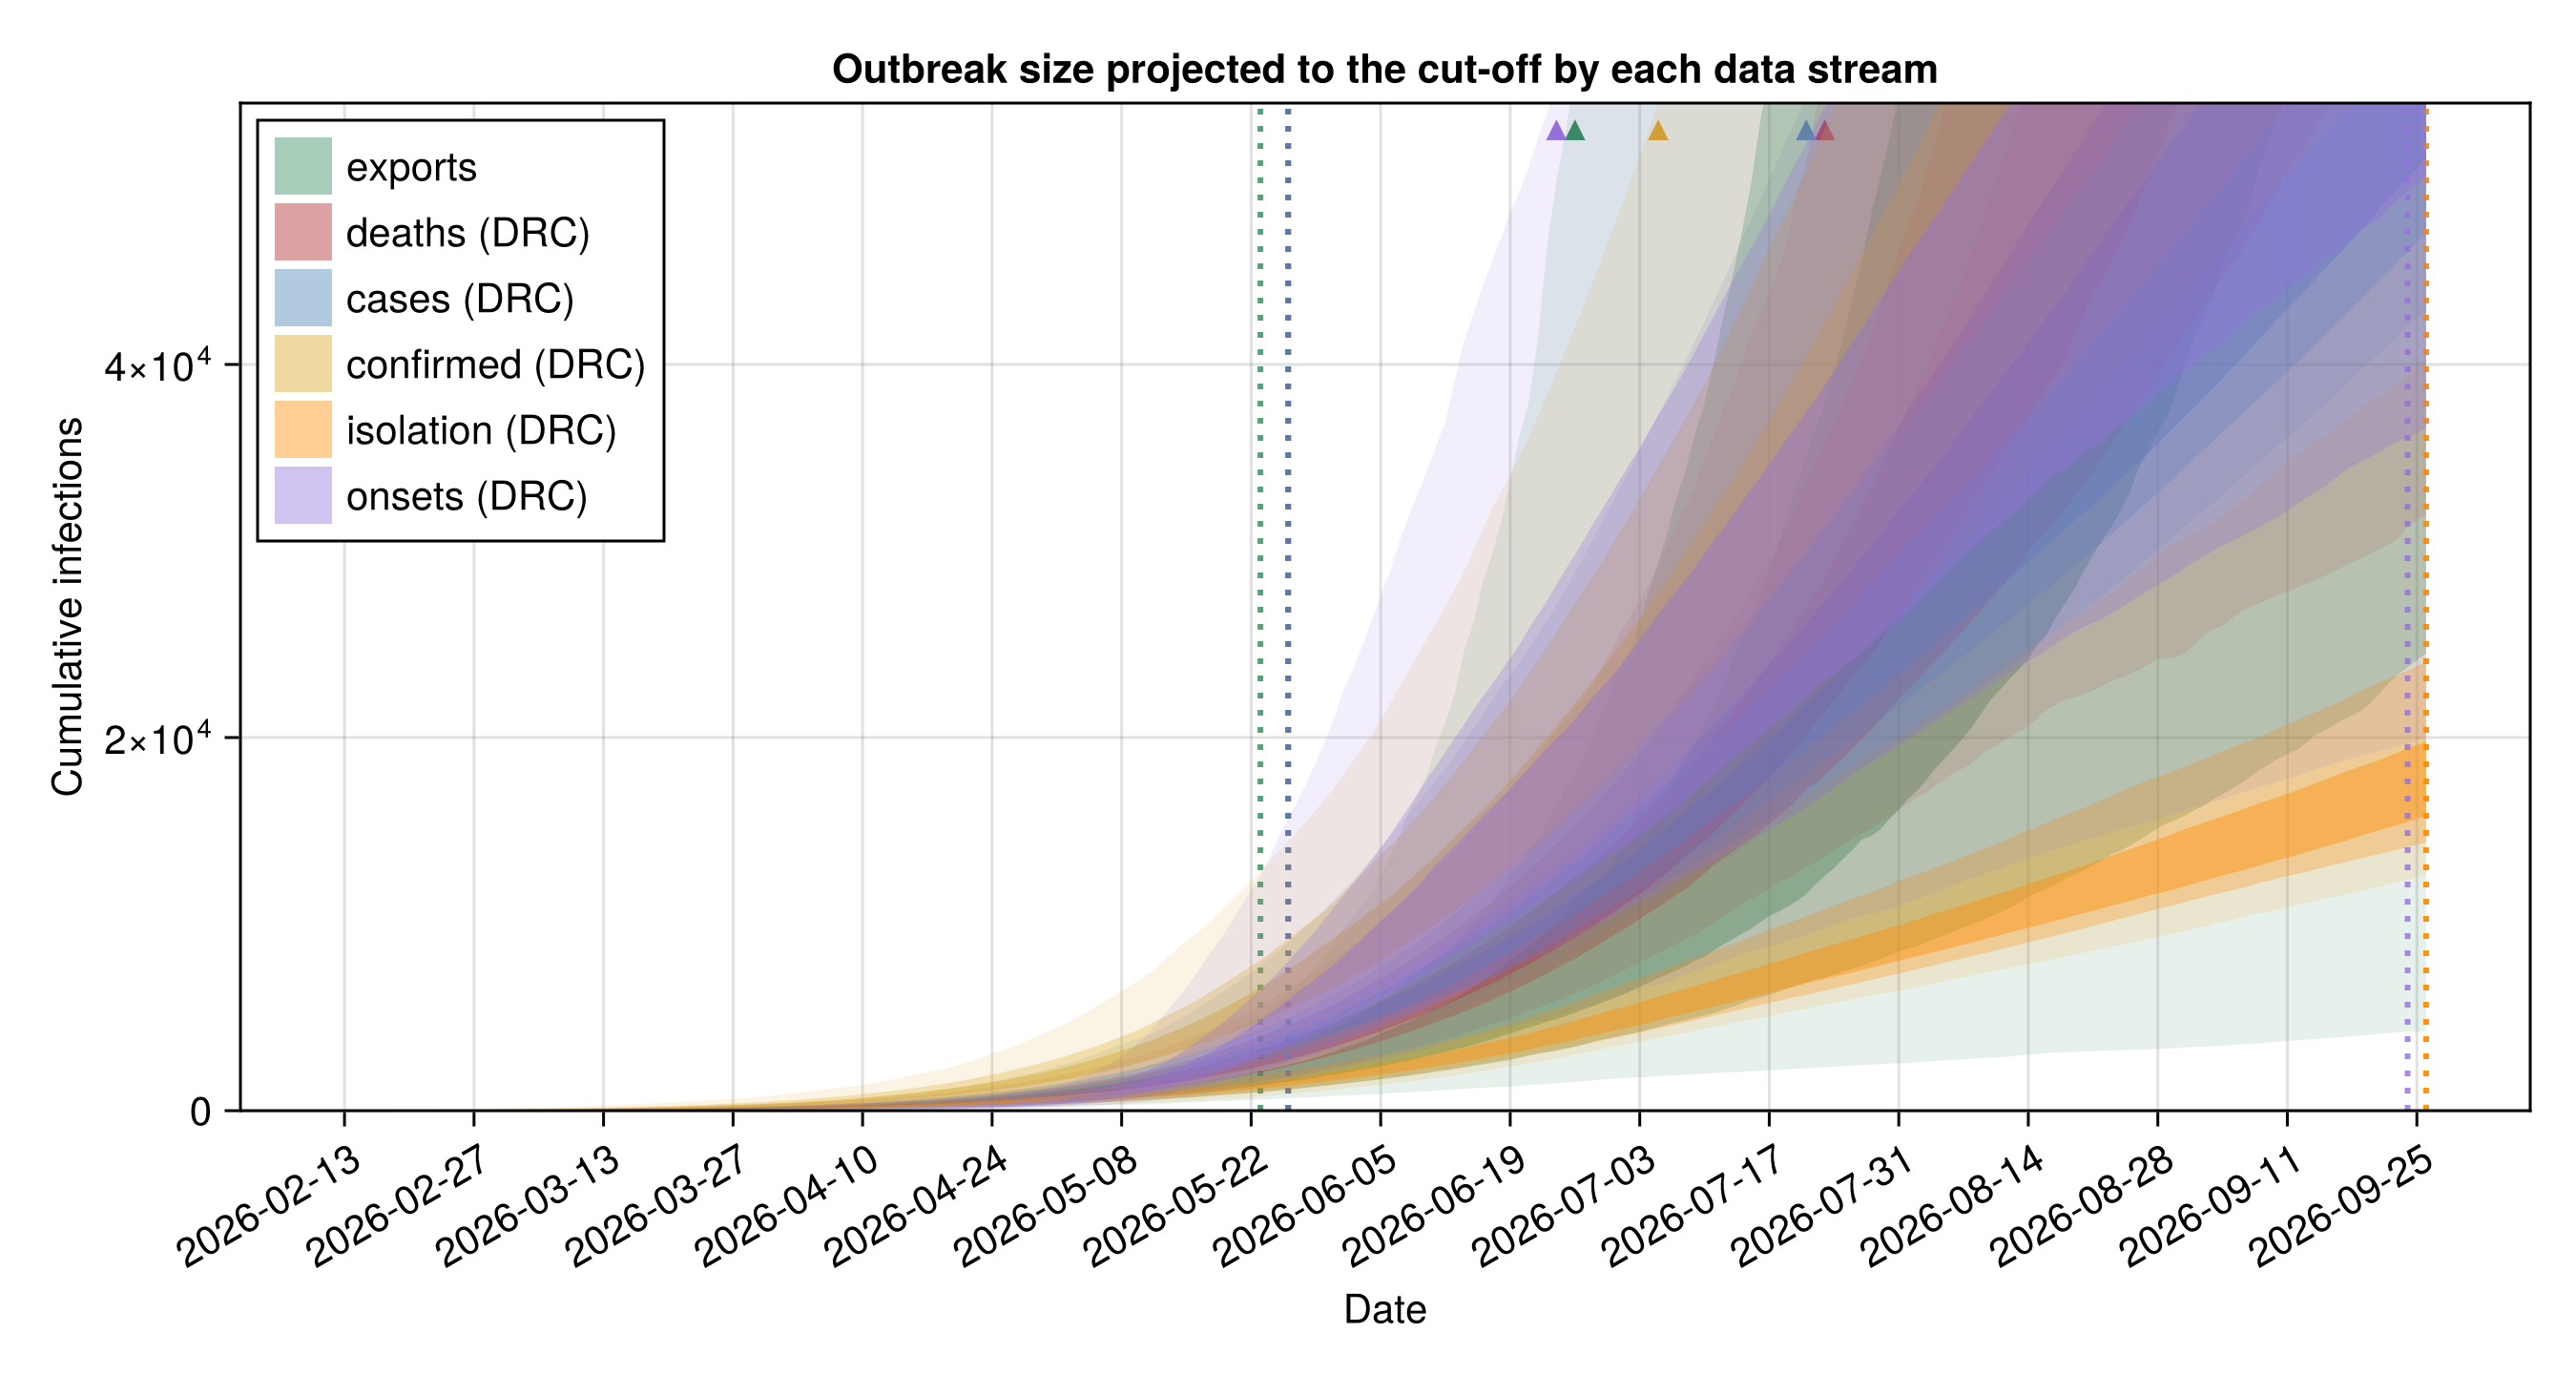
The first figure shows each single-stream fit's cumulative-infection trajectory projected to the cut-off, with a dotted rule in each stream's colour marking where its data stops and the ribbon beyond it becomes a forward projection. The count axis is cropped to twice the joint fit's 90% upper bound, as the density figure below is, and a stream whose band runs past the crop is marked with an open triangle where it leaves the axis.
Per-stream projected-trajectory plot
# Per-draw cumulative-infection trajectory carried by each single-stream
# fit out to the cut-off on day `n`, so streams whose data ends earlier are
# still projected to today.
function _cuminf(chn)
    mat = chn[:cumulative_infections]
    return [collect(v) for v in vec(collect(mat))]
end
# Grid day a stream's data last reports, used for the dotted rule. The
# suspected case and death histories freeze at 26 May; exports and confirmed
# run to the cut-off.
_last_day(days) = isempty(days) ? nothing : maximum(days)

stream_traj_fig = plot_stream_trajectories(
    [
        (;
            label = "exports", trajs = _cuminf(chn_exports),
            last_day = _last_day(
                vcat(
                    obs.export_case_days,
                    obs.export_death_days
                )
            ), colour = :seagreen,
        ),
        (;
            label = "deaths (DRC)", trajs = _cuminf(chn_deaths),
            last_day = _last_day(obs.deaths_history.days),
            colour = :firebrick,
        ),
        (;
            label = "cases (DRC)", trajs = _cuminf(chn_cases),
            last_day = _last_day(obs.reported_history.days),
            colour = :steelblue,
        ),
        (;
            label = "confirmed (DRC)", trajs = _cuminf(chn_confirmed),
            last_day = _last_day(obs.confirmed_history.days),
            colour = :goldenrod,
        ),
        (;
            label = "isolation (DRC)", trajs = _cuminf(chn_treatment),
            last_day = _last_day(obs.isolation_history.days),
            colour = :darkorange,
        ),
        (;
            label = "onsets (DRC)", trajs = _cuminf(chn_onsets),
            last_day = _last_day(obs.onset_curve_history.report_days),
            colour = :mediumpurple,
        ),
    ];
    n = obs.n, seeding = obs.seeding,
    # Twice the joint fit's 90% upper, the crop the cut-off density figure
    # below already uses. The exports-only fit bounds the infection count
    # so weakly that its 90% upper reaches the source population, which on
    # a free axis puts every other stream on the baseline.
    ymax = 2.0 * quantile(posterior_C_joint, 0.95)
);
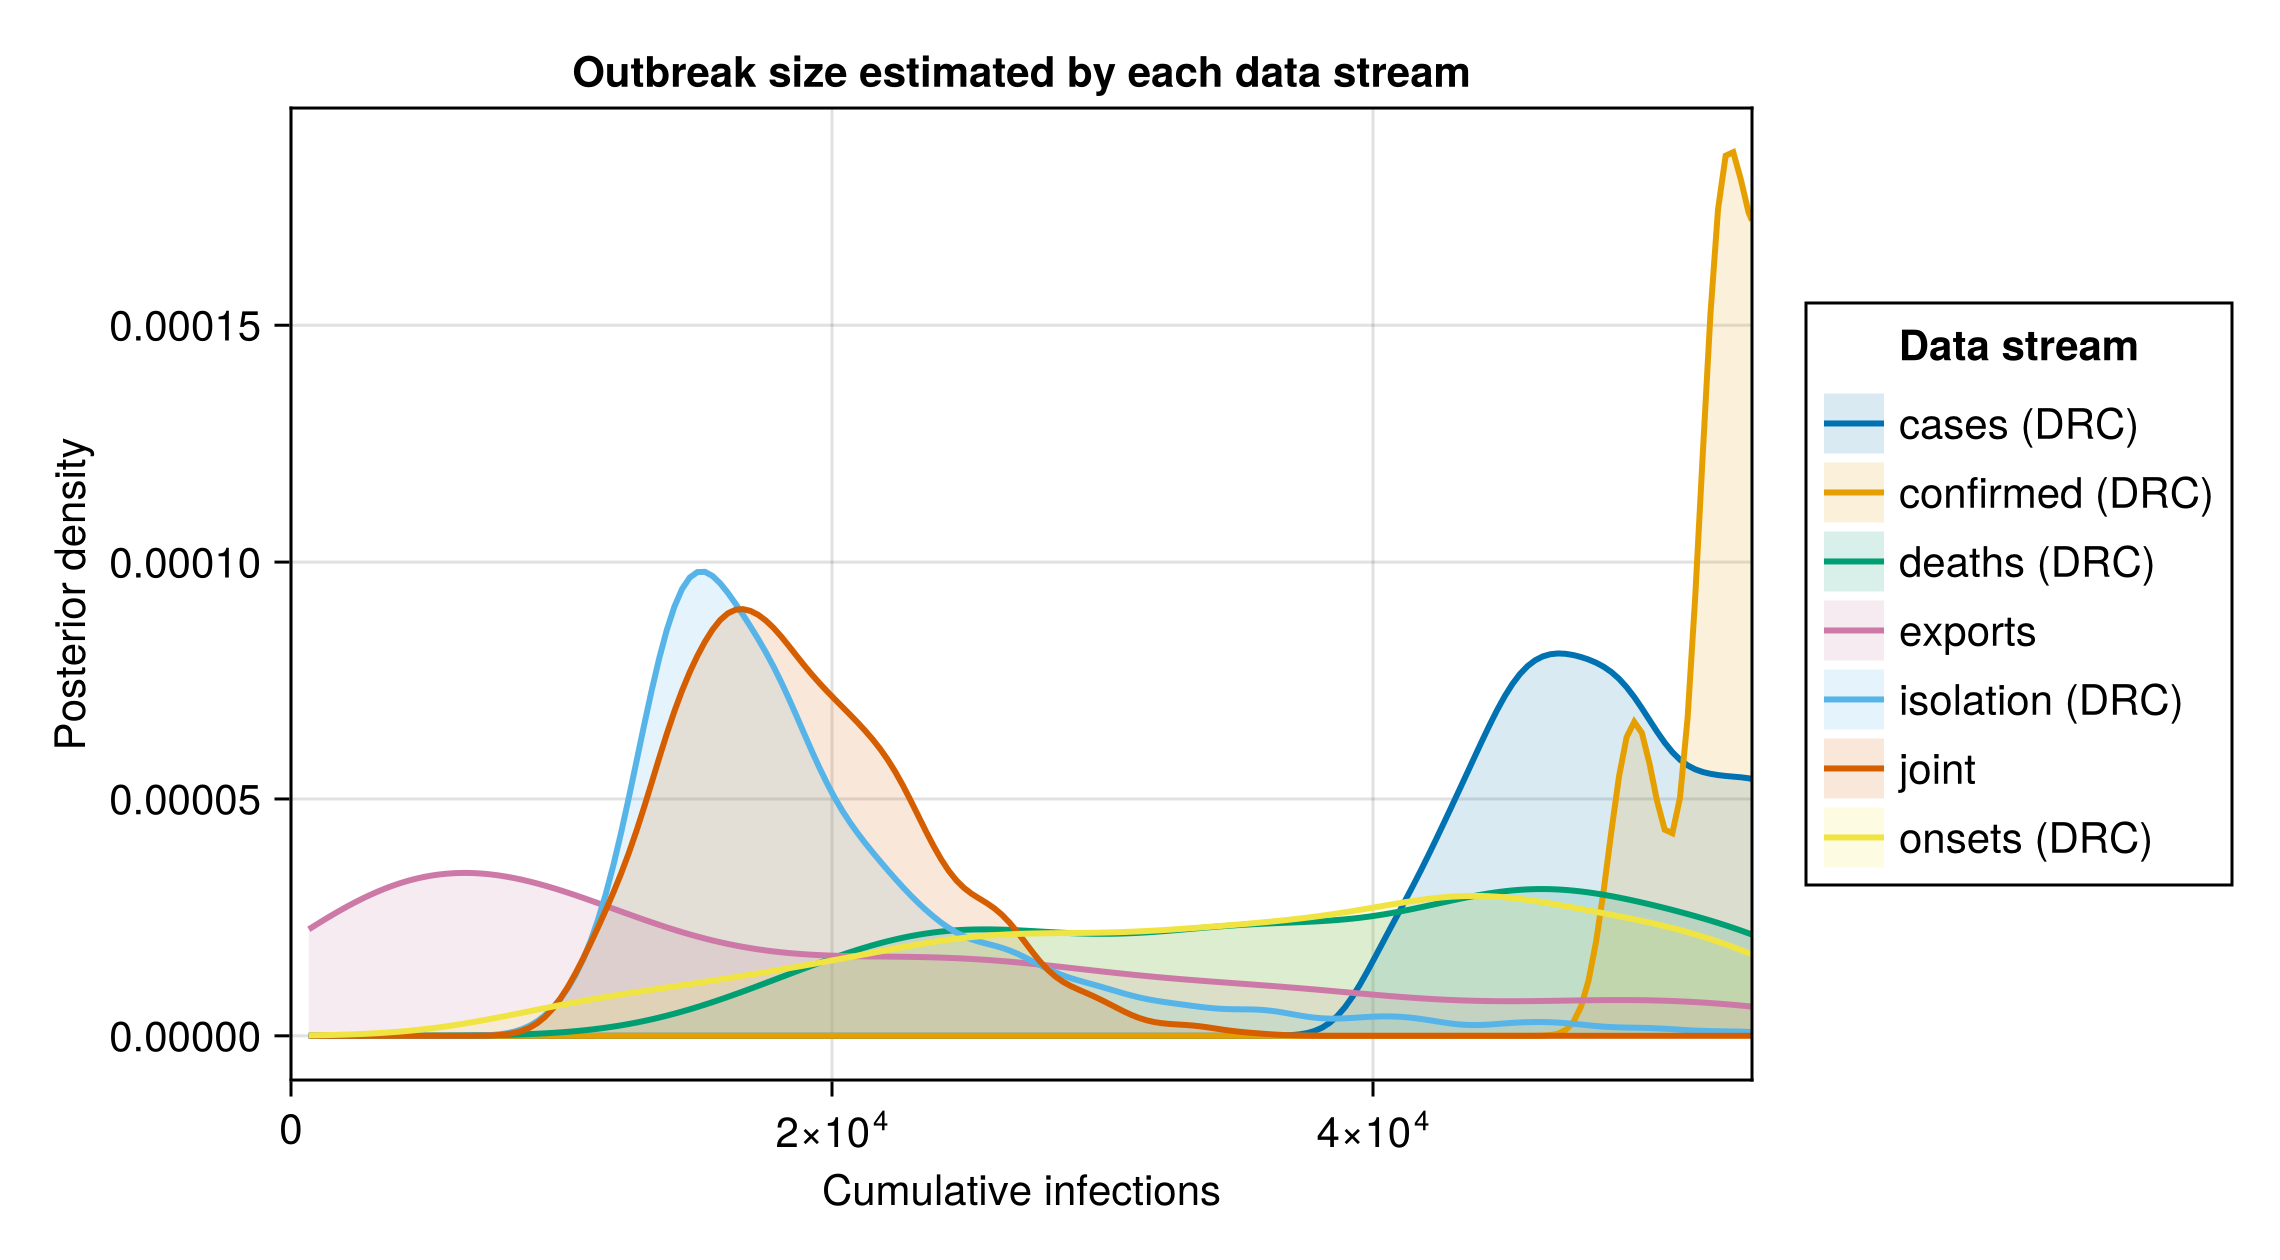
The second figure is the posterior density of each fit's cumulative infection count at the cut-off. The x-axis is scaled to a multiple of the joint-fit 90% upper bound so the bulk of the streams stays visible rather than being flattened by the wide, ill-defined confirmed-only tail.
Cut-off infection-count density plot
# Scale the x-axis to twice the joint-fit 90% upper bound, so the joint and
# the streams that track it read clearly while the confirmed-only tail runs
# off the axis rather than dominating it.
density_xmax = 2.0 * quantile(posterior_C_joint, 0.95)

cumulative_density_fig = plot_cumulative_cases(
    "exports" => posterior_C_exports,
    "deaths (DRC)" => posterior_C_deaths,
    "cases (DRC)" => posterior_C_cases,
    "confirmed (DRC)" => posterior_C_confirmed,
    "isolation (DRC)" => posterior_C_treatment,
    "onsets (DRC)" => posterior_C_onsets,
    "joint" => posterior_C_joint;
    scenarios = [], xmax = density_xmax
);
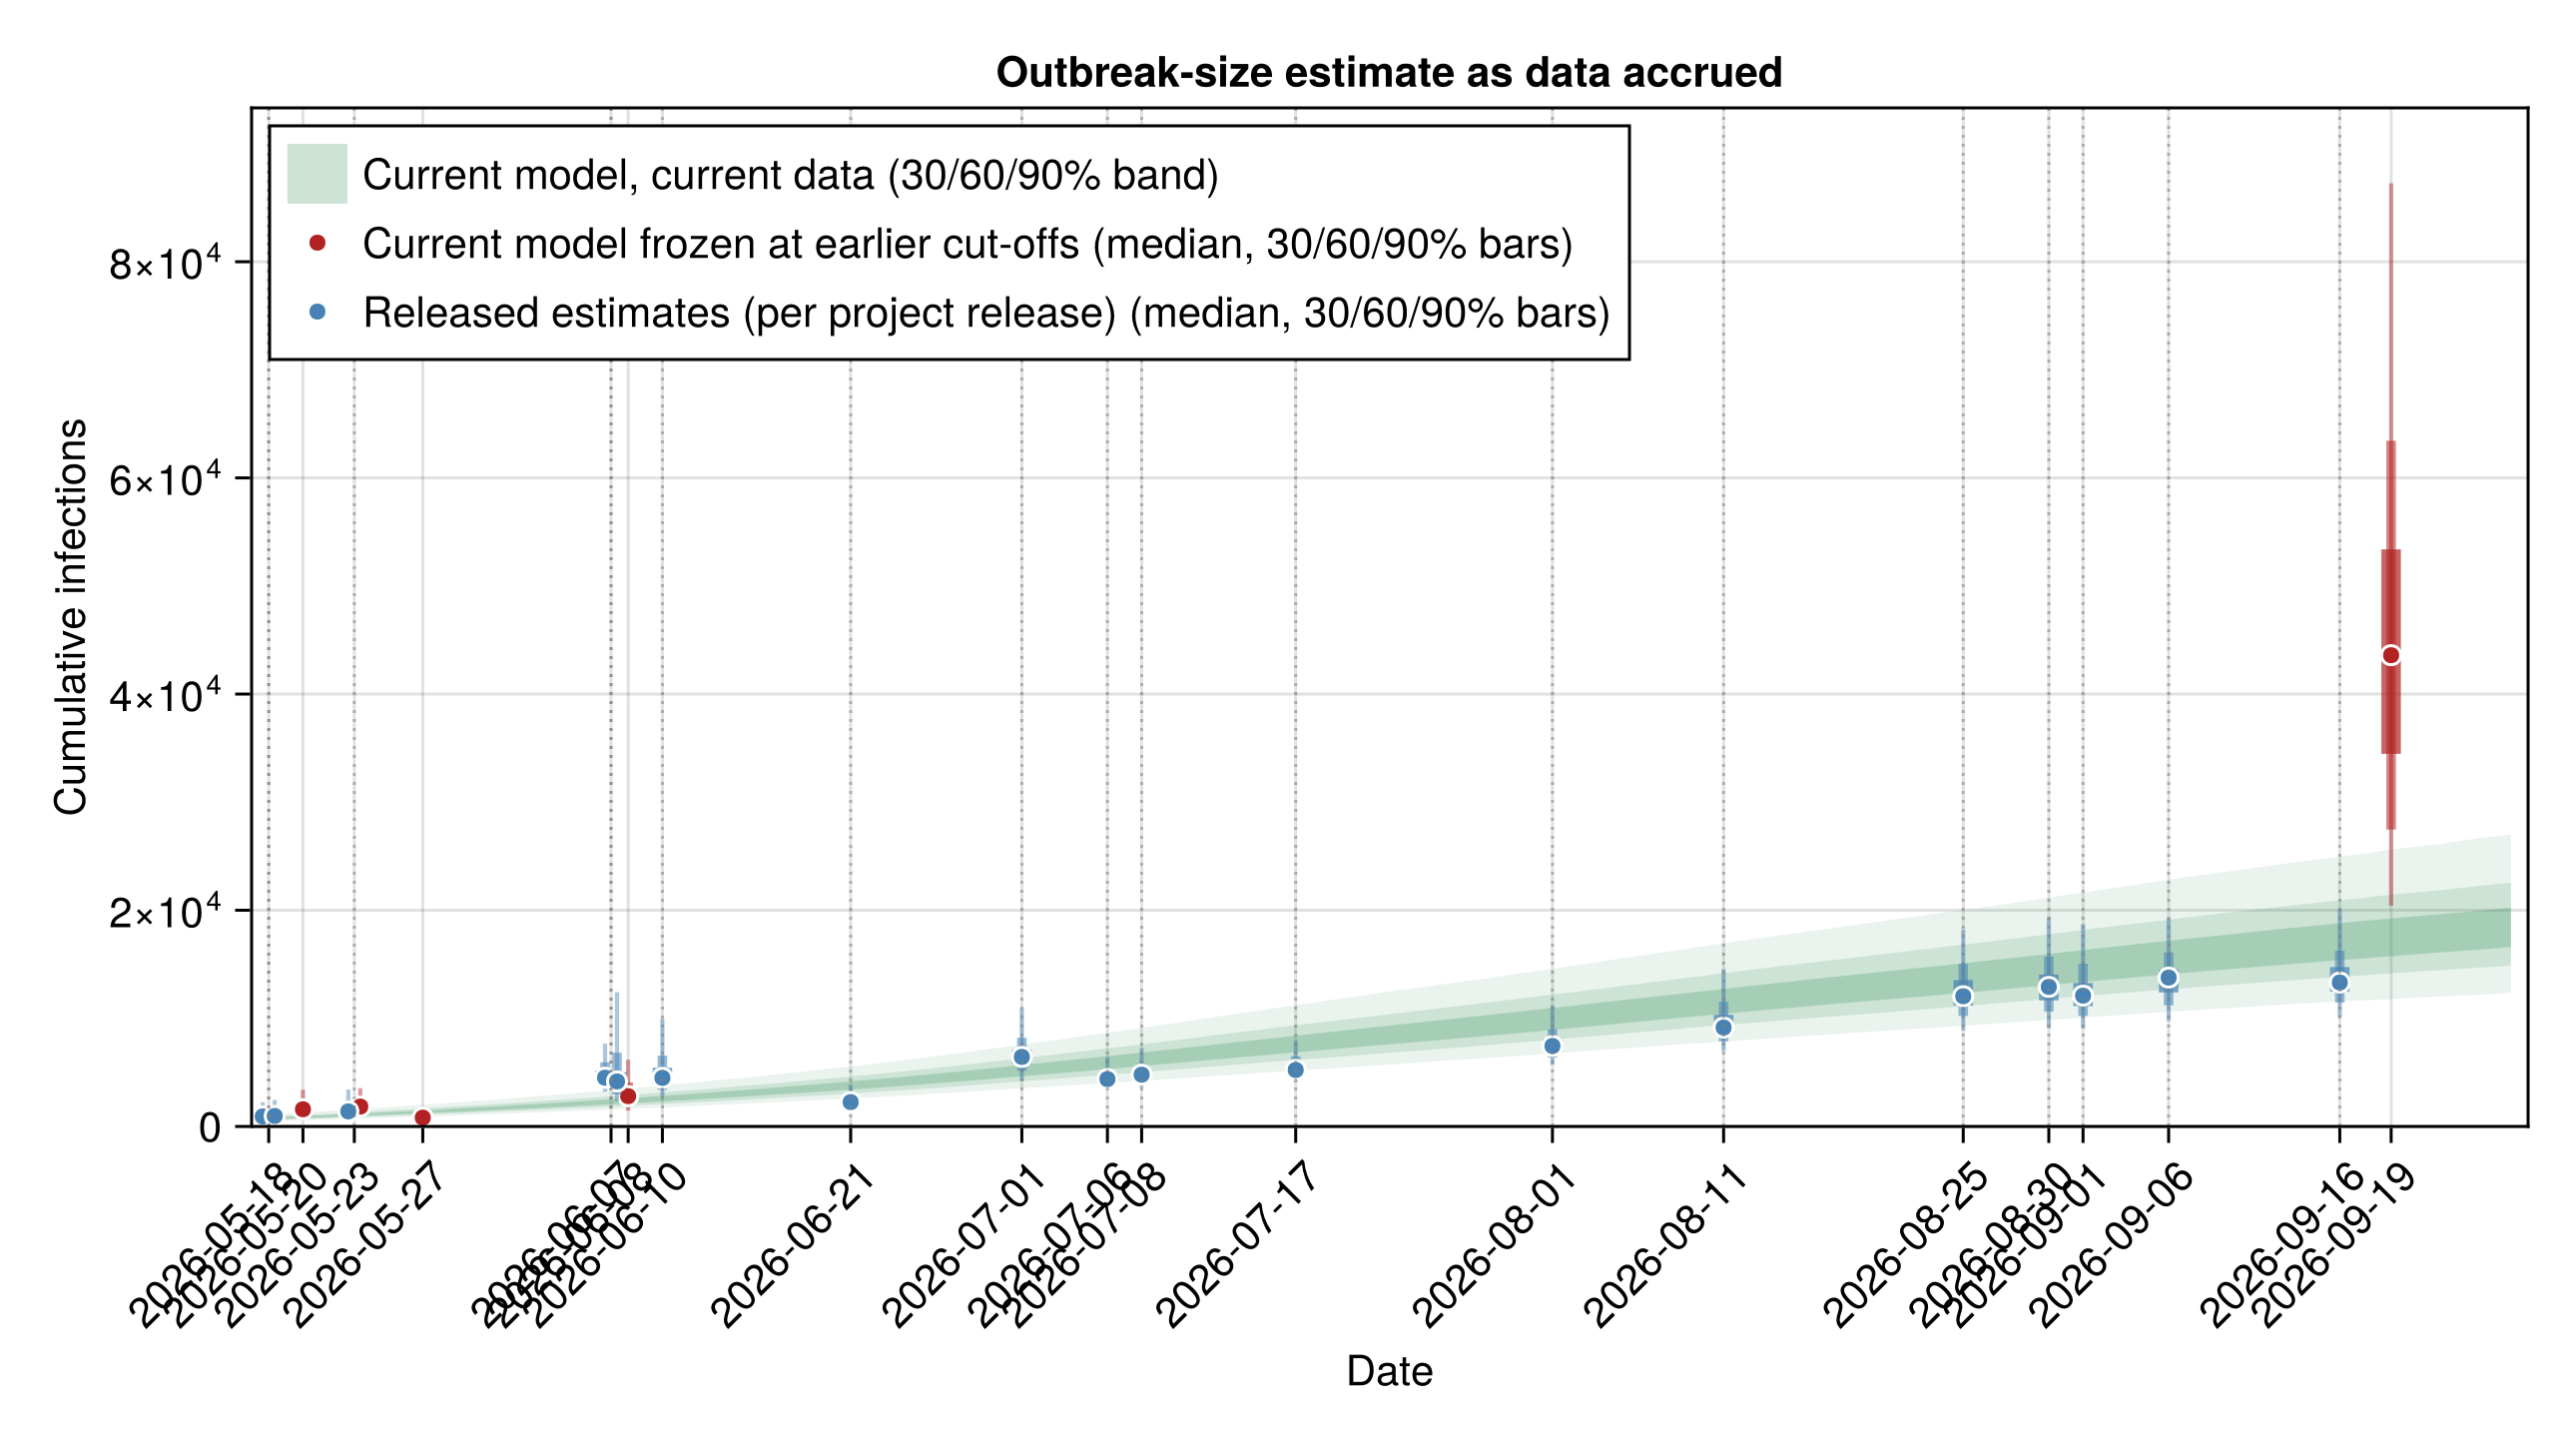
Estimate evolution across releases
How the outbreak-size estimate has moved as situation reports accrued, three series on one calendar axis. The estimate published at each release is in blue, drawn as a median with nested 30/60/90% interval bars because each release is its own fit rather than one continuous model. The current model frozen at earlier cut-offs is in red, reusing fits already made for the McCabe and Chamla comparisons and the forecast validation. The current model on current data is the green band, drawn day by day so the latest estimate reads against the earlier points. Dotted vertical rules mark the release dates. The published series switches from a closed-form integral model to a renewal model on 7 June, so a step there can reflect the change of method rather than of data.
Released estimates and the current-model frozen re-fits
# Released median and 30/60/90% intervals per release, from
# `data/released_estimates.csv`. Each tuple is
# `(date, median, lo30, hi30, lo60, hi60, lo90, hi90)`.
release_evolution = [
    (
        string(r.date), r.median, r.lo30, r.hi30, r.lo60, r.hi60,
        r.lo90, r.hi90,
    ) for r in eachrow(released_df)
]

# The current model frozen at earlier cut-offs, each its own discrete
# estimate: the matched-McCabe cut-offs (20, 23, 27 May) already computed
# for the matched-in-time comparison below, the 8 June Chamla
# confirmed-case anchor computed for the Chamla comparison, and the
# one-week-back validation fit (`frozen_lastweek`, at `validation_cutoff`)
# already computed for the forecast validation above. All are reused here so
# the current-model estimate at those earlier cut-offs reads against the
# released overlay, including a recent point one week before the cut-off.
# No extra fits are run. Each tuple carries the median and 30/60/90%
# credible bounds from the frozen draws; `round_fn` rounds to a whole count
# for outbreak size, and is passed through unrounded for a continuous
# quantity such as R0.
function _ci369(xs; round_fn = x -> round(Int, x))
    q(p) = round_fn(quantile(xs, p))
    return (q(0.5), q(0.35), q(0.65), q(0.2), q(0.8), q(0.05), q(0.95))
end
frozen_by_cutoff[validation_cutoff] = frozen_lastweek
# The cut-offs every frozen fit above was made at, shared by the
# outbreak-size and R0 by-release overlays below.
_frozen_matched_cutoffs = sort(
    union(
        frozen_cutoffs,
        [validation_cutoff, default_chamla_cutoff()]
    )
)
frozen_matched = [(c, _ci369(frozen_C(c))...) for c in _frozen_matched_cutoffs]

# The current-data, current-model estimate as the cumulative-infection
# trajectory over the day grid (one calendar date per grid day, day 1 is
# the seeding date), summarised by per-day 30/60/90% credible bounds. This
# is the same latent quantity the cumulative-trajectory figure shows, so
# the current estimate rises over time on the release-date axis instead of
# sitting flat. Drawn against calendar dates, it lines up with the
# release and frozen points.
infection_trajectory = let
    mat = chn_joint[:cumulative_infections]
    trajs = [collect(v) for v in vec(collect(mat))]
    # Only over the comparison window — from the earliest release date to the
    # cut-off — not back to the seeding date.
    start_day = obs.n - value(obs.cutoff - Date(release_evolution[1][1]))
    days = max(start_day, 1):obs.n
    dates = [obs.seeding + Day(d - 1) for d in days]
    q(d, p) = quantile(Float64[t[d] for t in trajs], p)
    (
        dates,
        [q(d, 0.35) for d in days], [q(d, 0.65) for d in days],
        [q(d, 0.2) for d in days], [q(d, 0.8) for d in days],
        [q(d, 0.05) for d in days], [q(d, 0.95) for d in days],
    )
end

evolution_fig = plot_estimate_evolution(
    release_evolution;
    renewal = frozen_matched,
    renewal_label = "Current model frozen at earlier cut-offs",
    trajectory = infection_trajectory,
    title = "Outbreak-size estimate as data accrued"
);
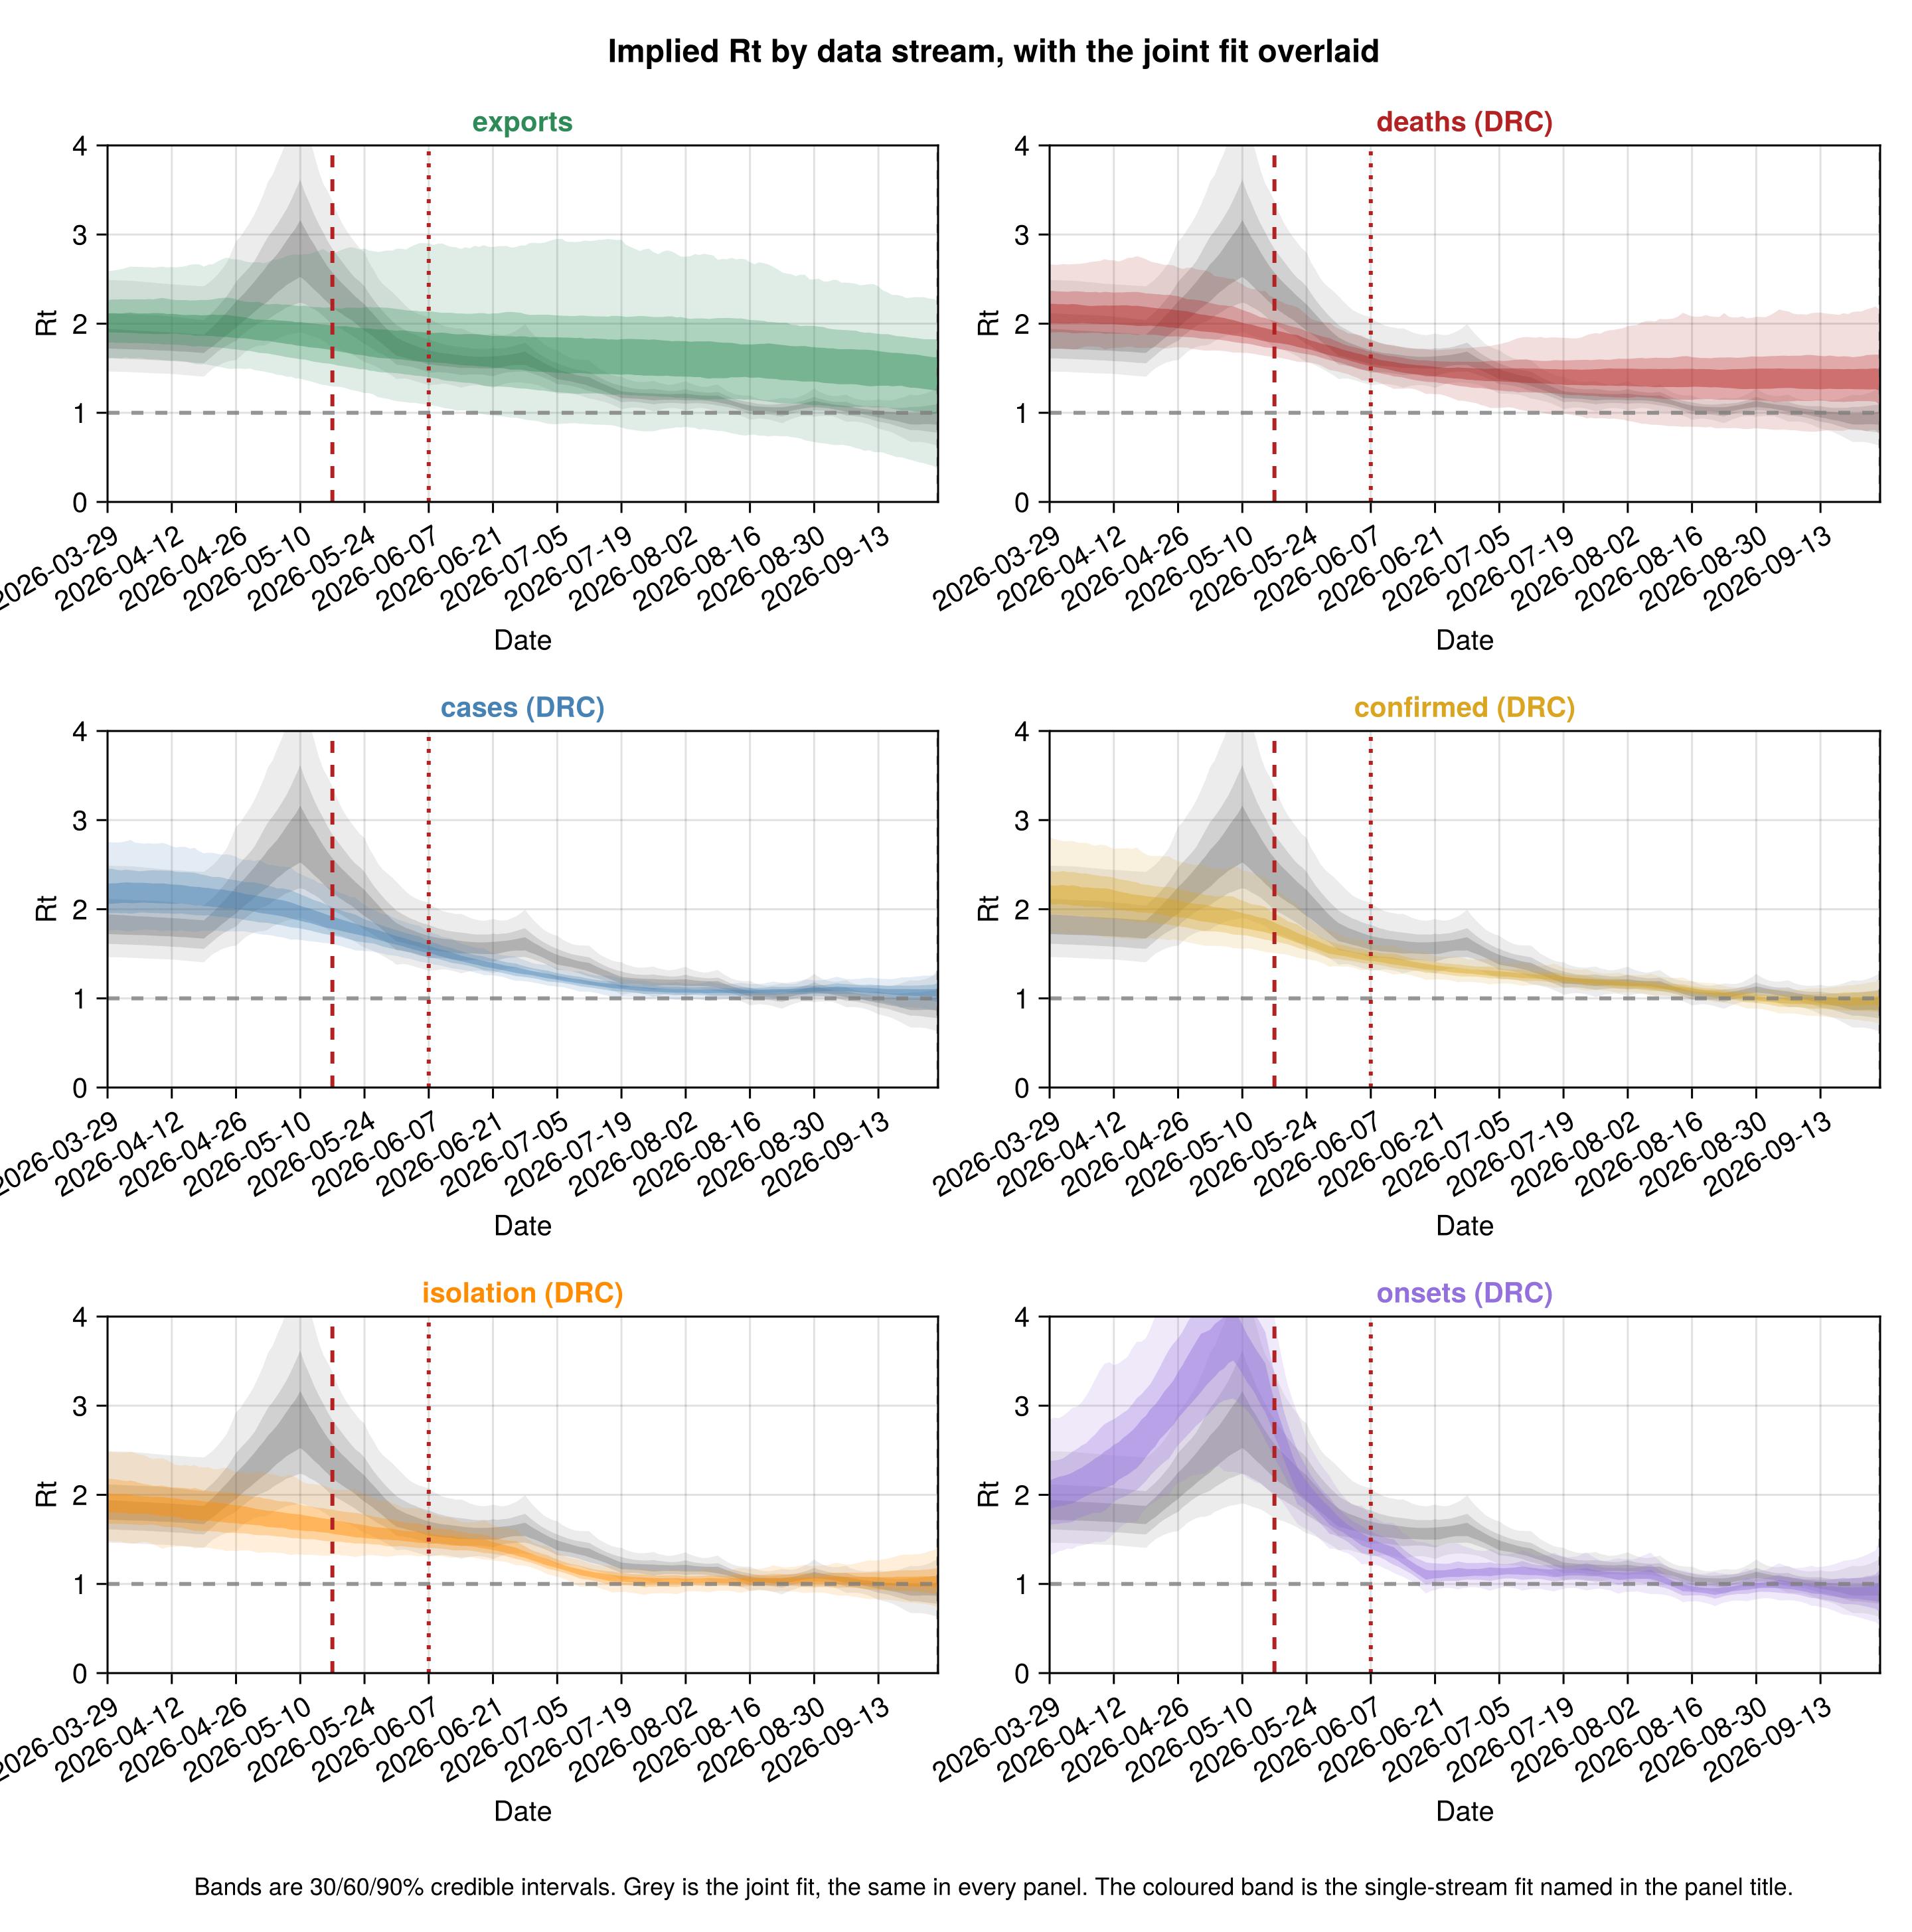
Reproduction number estimated by each data stream
The reproduction number each stream implies on its own, one panel per stream with the joint fit overlaid in grey as the reference.
Per-stream implied-Rt plot
# The per-stream fits walk Rt from day 1 (the default `rt_start`), while the
# joint walks from `RT_WALK_LEAD` days before the first situation report; the
# shared `display_start` is the joint renewal start so every stream reads over
# the same established window. `ramp` matches the joint Rt figure.
_rt_walk_start_joint = clamp(_BREAKPOINT - RT_WALK_LEAD, _rt_start_plot, obs.n);
stream_rt_fig = plot_rt_streams(
    [
        (;
            label = "exports", chn = chn_exports, rt_start = 1,
            rt_walk_start = 1, colour = :seagreen,
        ),
        (;
            label = "deaths (DRC)", chn = chn_deaths, rt_start = 1,
            rt_walk_start = 1, colour = :firebrick,
        ),
        (;
            label = "cases (DRC)", chn = chn_cases, rt_start = 1,
            rt_walk_start = 1, colour = :steelblue,
        ),
        (;
            label = "confirmed (DRC)", chn = chn_confirmed, rt_start = 1,
            rt_walk_start = 1, colour = :goldenrod,
        ),
        (;
            label = "isolation (DRC)", chn = chn_treatment, rt_start = 1,
            rt_walk_start = 1, colour = :darkorange,
        ),
        (;
            label = "onsets (DRC)", chn = chn_onsets, rt_start = 1,
            rt_walk_start = 1, colour = :mediumpurple,
        ),
    ];
    joint = (;
        label = "joint", chn = chn_joint, rt_start = _rt_start_plot,
        rt_walk_start = _rt_walk_start_joint,
    ),
    n = obs.n, breakpoint = _BREAKPOINT,
    as_of_date = string(obs.cutoff), seeding = obs.seeding,
    display_start = _rt_start_plot, ramp = RT_INTERVENTION_RAMP
);
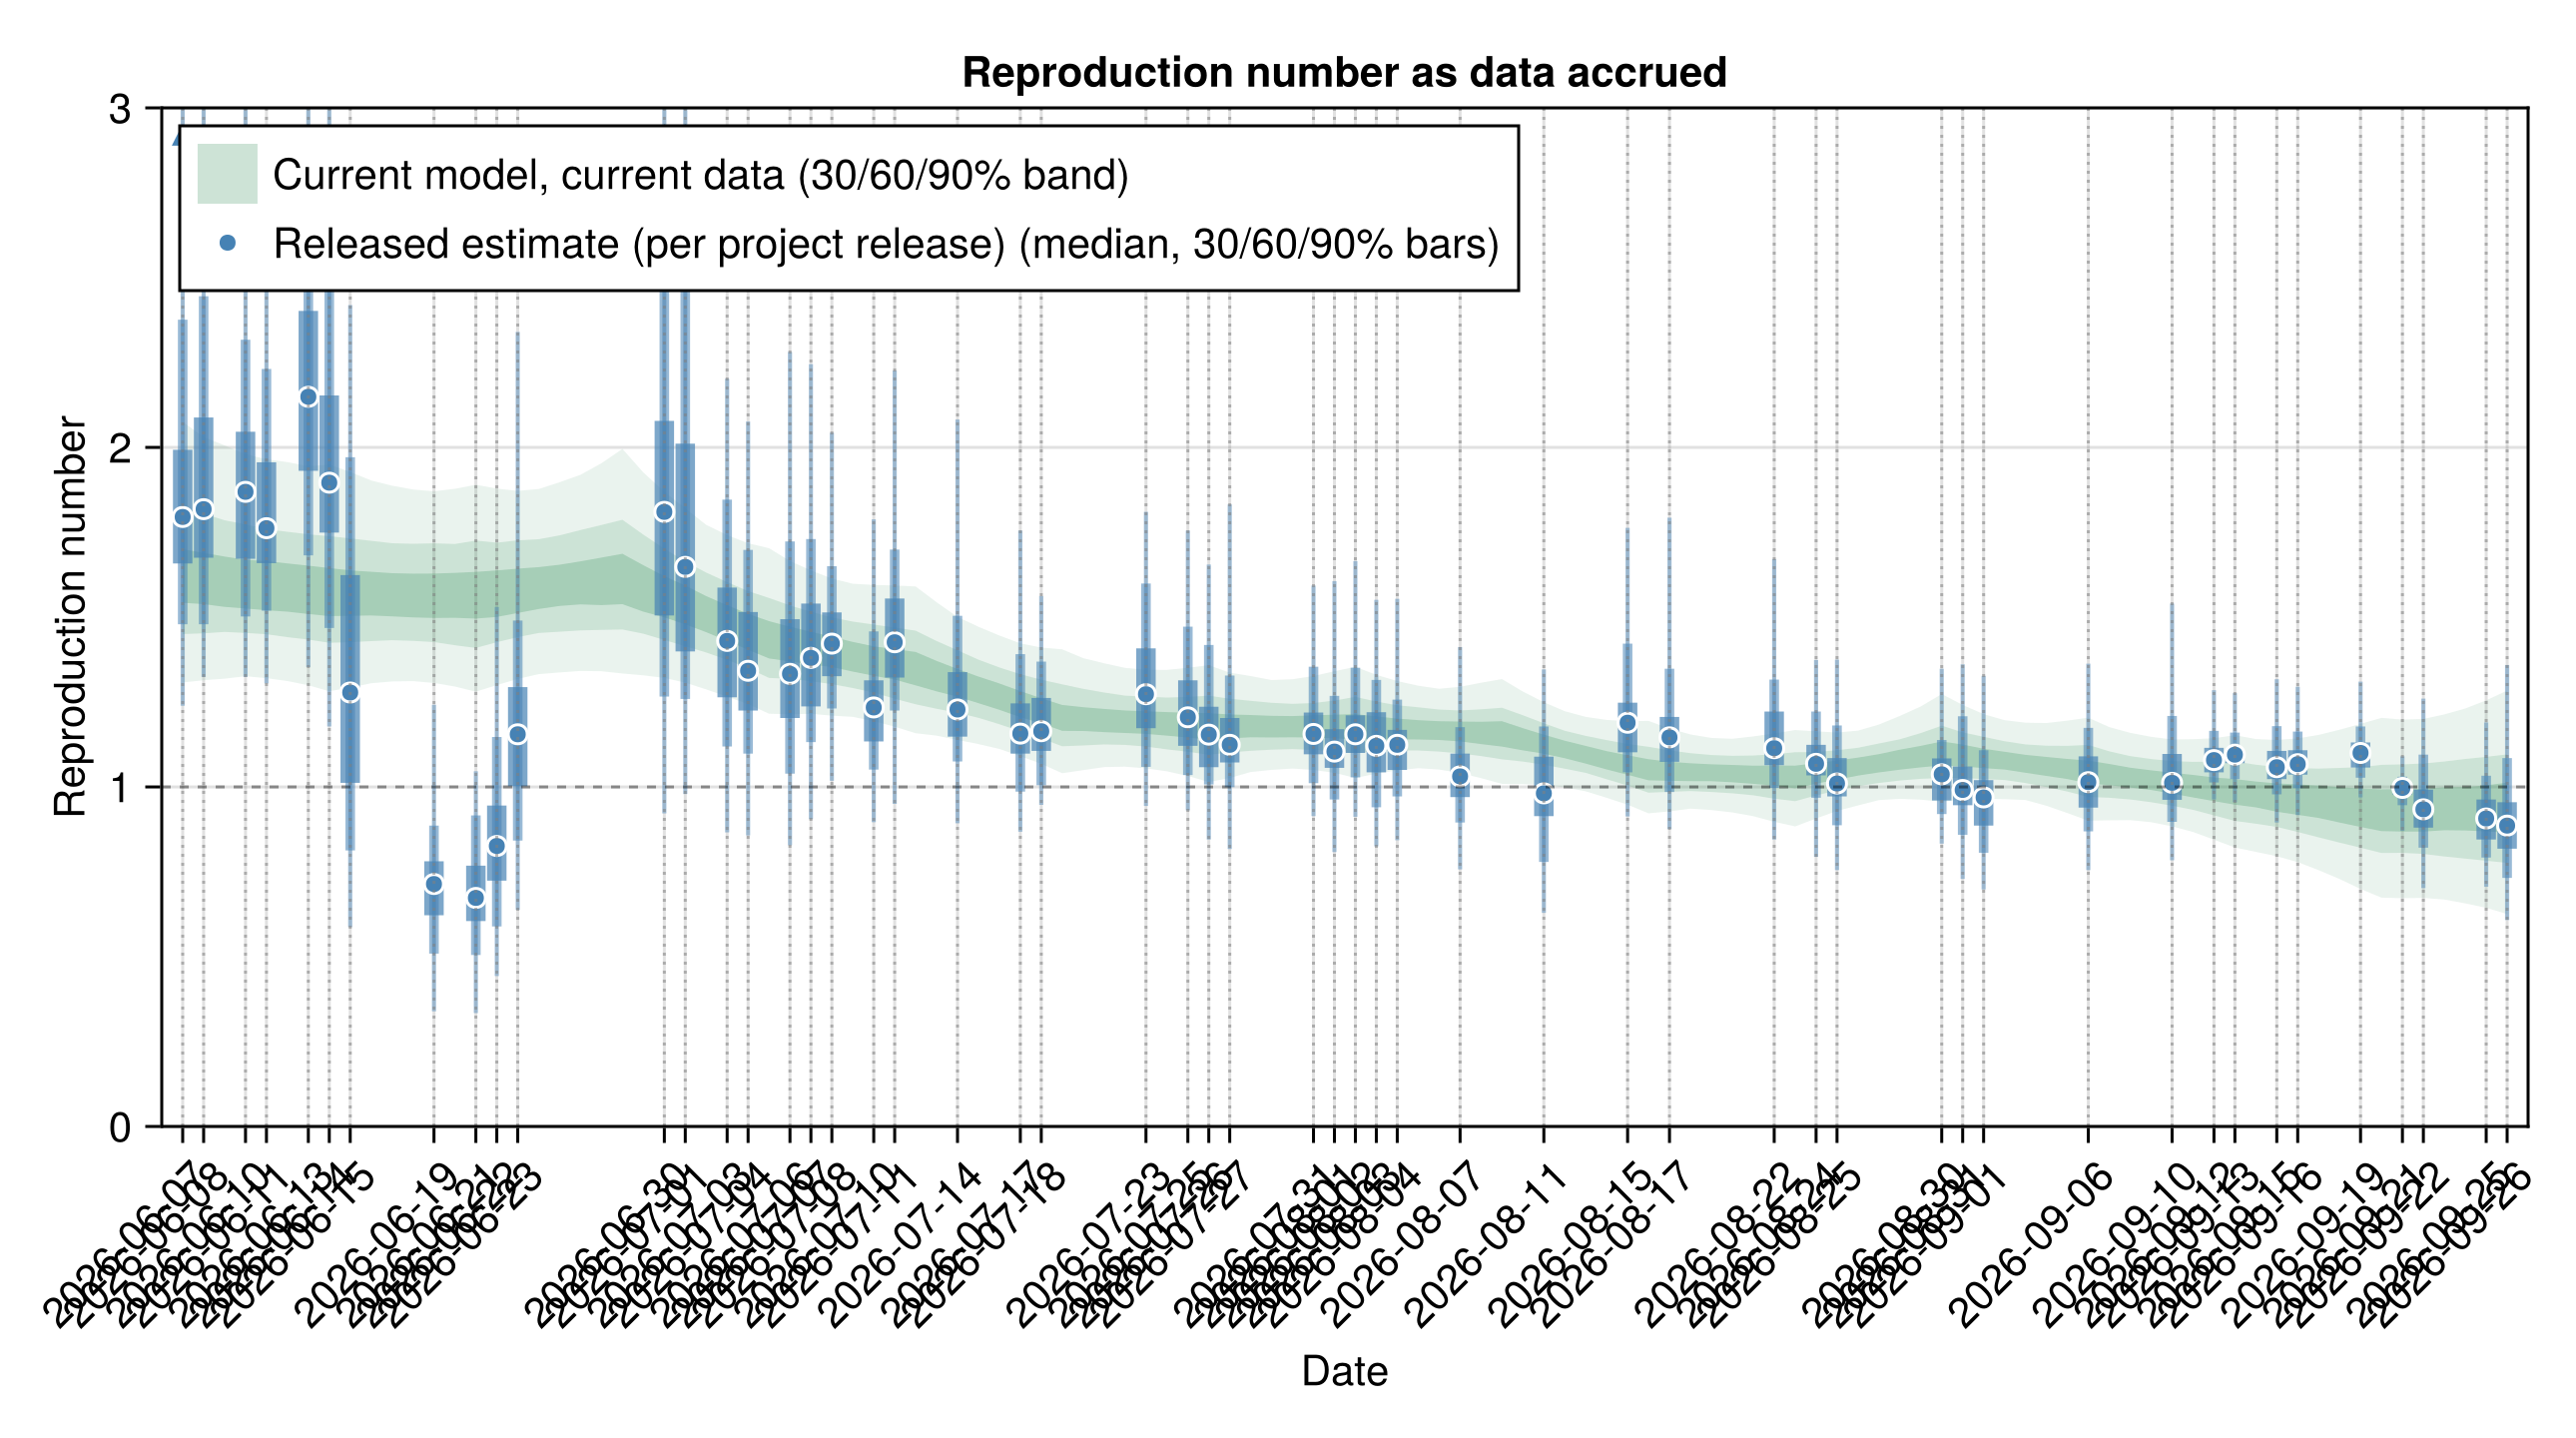
Reproduction number by release
The reproduction number estimated at each release, the same kind of release-by-release picture as the outbreak-size evolution above. Each release's cut-off reproduction number
Reproduction number per release with the current-fit band
rt_release_df = CSV.read(
    joinpath(pkgdir(BVDOutbreakSize), "data", "rt_by_release.csv"), DataFrame
)
rt_release = [
    (
        string(r.date), r.median, r.lo30, r.hi30, r.lo60, r.hi60,
        r.lo90, r.hi90,
    ) for r in eachrow(rt_release_df)
]

# The current fit's daily Rt over its established window, summarised per day
# into a 30/60/90% band, reusing the same walk reconstruction the Rt figure
# uses so the band lines up with the per-release points on the calendar axis.
# The band is drawn only from the first release date onward, so it spans the
# same window as the per-release estimates rather than extending back to the
# renewal start. The first release day is the earliest date in
# `rt_by_release.csv` as a grid day; the walk is still reconstructed from the
# renewal start `_rt_start_plot` (the model knot grid) and the window is
# clamped into the reconstructed range so the quantiles never hit masked days.
rt_release_trajectory = let
    rt_walk_start = clamp(_BREAKPOINT - RT_WALK_LEAD, _rt_start_plot, obs.n)
    mat = reconstruct_rt(
        chn_joint; n = obs.n, breakpoint = _BREAKPOINT,
        rt_start = _rt_start_plot, rt_walk_start = rt_walk_start,
        ramp = RT_INTERVENTION_RAMP
    )
    first_release_day = clamp(
        value(minimum(rt_release_df.date) - obs.seeding) + 1,
        _rt_start_plot, obs.n
    )
    days = first_release_day:obs.n
    dates = [obs.seeding + Day(d - 1) for d in days]
    q(d, p) = quantile(collect(skipmissing(@view mat[:, d])), p)
    (
        dates,
        [q(d, 0.35) for d in days], [q(d, 0.65) for d in days],
        [q(d, 0.2) for d in days], [q(d, 0.8) for d in days],
        [q(d, 0.05) for d in days], [q(d, 0.95) for d in days],
    )
end

# One fixed reproduction-number axis across both figures below. The
# estimates sit around one and the widest stream's 90% upper pulls a free
# axis past four, which flattens every panel onto the lower quarter of its
# range. An interval past the crop is clamped and marked, so nothing is
# silently cut. The basic reproduction number keeps its own axis: it sits
# around two with tails near four, and the same crop would clip the
# estimates themselves.
const _RT_AXIS_MAX = 3.0

rt_evolution_fig = plot_estimate_evolution(
    rt_release;
    trajectory = rt_release_trajectory,
    ylabel = "Reproduction number",
    title = "Reproduction number as data accrued",
    released_label = "Released estimate (per project release)",
    trajectory_label = "Current model, current data",
    refline = 1.0,
    ymax = _RT_AXIS_MAX
);
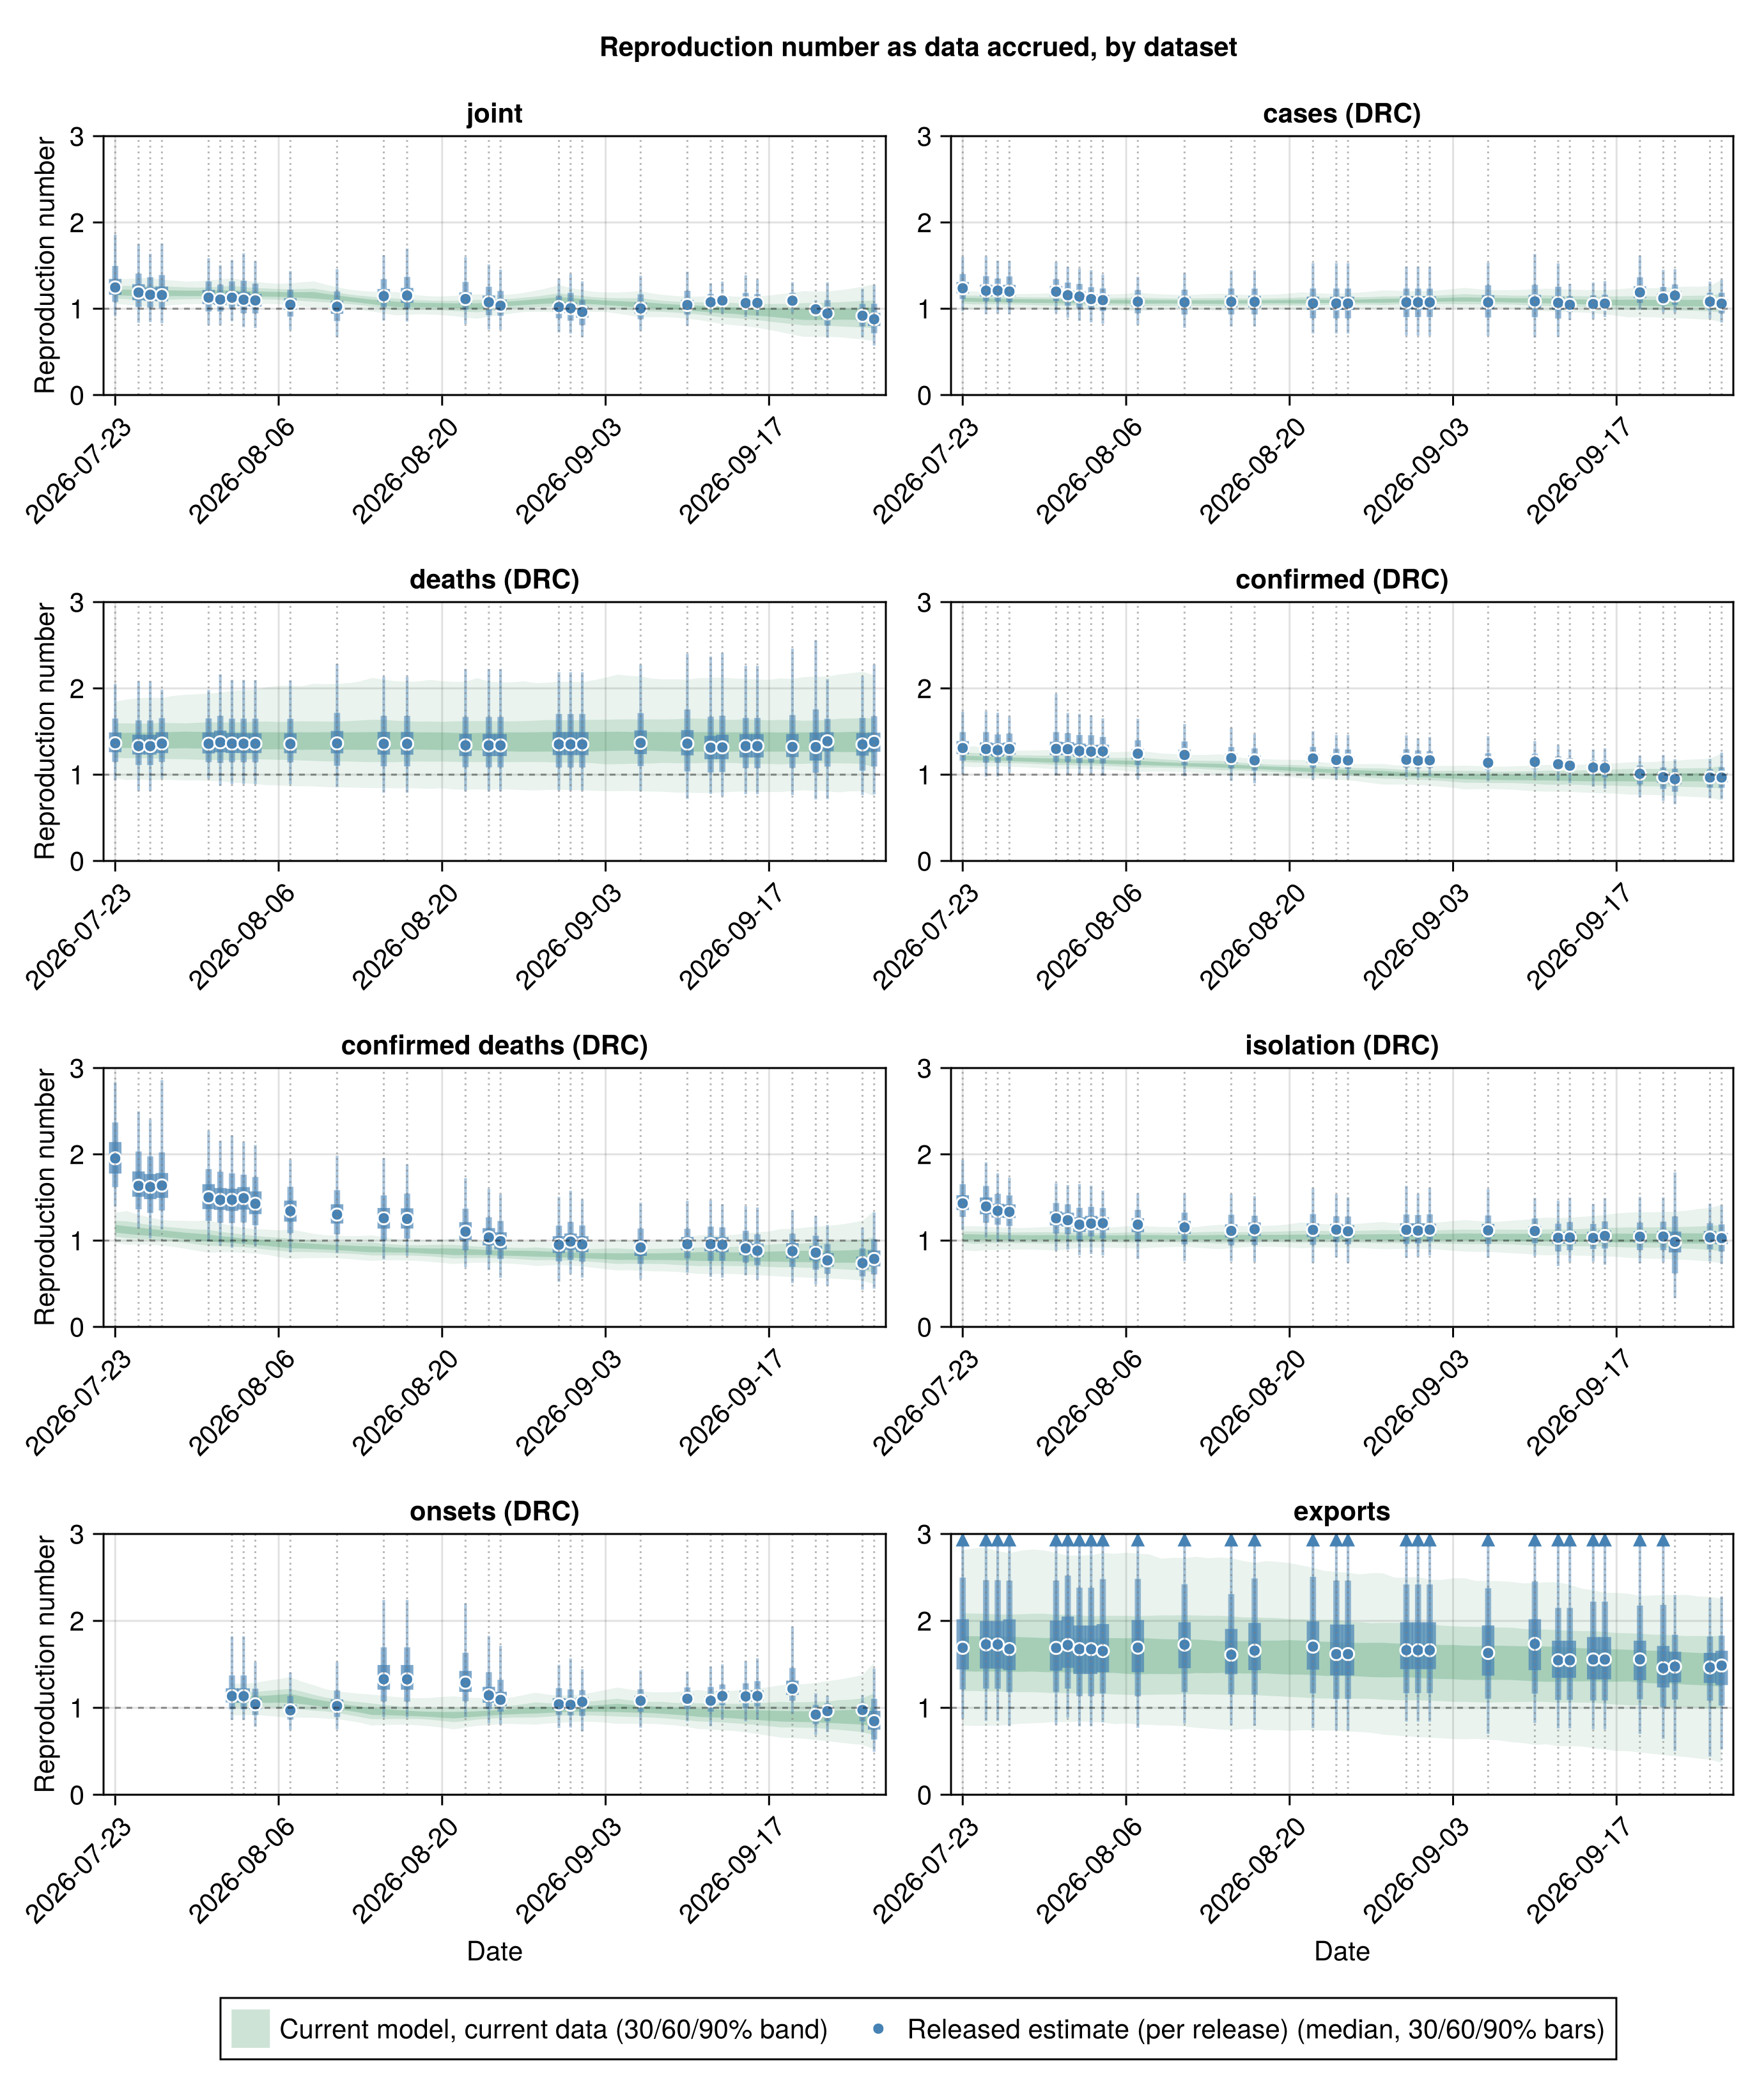
Reproduction number by release and dataset
The same release-by-release reproduction number split into one panel per dataset, so each dataset's history reads against the others and against the joint. Panels share a calendar axis and the fixed reproduction-number range, and
Reproduction number per release by fit
# Schema of the per-release, per-fit estimate tables written by
# scripts/score_releases.jl from each release's stream_estimates.csv.
_by_stream_schema = (;
    release = String, date = Date, fit = String,
    median = Float64, lo30 = Float64, hi30 = Float64, lo60 = Float64,
    hi60 = Float64, lo90 = Float64, hi90 = Float64,
)

# Fits in a fixed order, the joint first, so the panels do not reshuffle
# between builds. Labels match the per-stream table above (in "Outbreak
# size estimated by each data stream"). Recovered is absent because it
# has no individual fit.
_fit_order = [
    "joint", "cases", "deaths", "confirmed", "confirmed_deaths",
    "treatment", "onsets", "exports",
]
_fit_labels = Dict(
    "joint" => "joint", "cases" => "cases (DRC)",
    "deaths" => "deaths (DRC)", "confirmed" => "confirmed (DRC)",
    "confirmed_deaths" => "confirmed deaths (DRC)",
    "treatment" => "isolation (DRC)", "onsets" => "onsets (DRC)",
    "exports" => "exports"
)

# Group a per-fit estimate table into the label => tuples pairs the faceted
# plot takes, keyed on the date so the mixed release tag shapes
# (`results-v1.9.0` and `results-1243`) never reach the axis.
function _fit_groups(df)
    return [
        get(_fit_labels, f, f) =>
            [
            (
                string(r.date), r.median, r.lo30, r.hi30, r.lo60, r.hi60,
                r.lo90, r.hi90,
            ) for r in eachrow(df) if r.fit == f
        ]
            for f in _fit_order
    ]
end

# Per-fit reproduction-number trajectory, reconstructing the walk exactly as
# `plot_rt_streams` does per stream.
function _stream_rt_trajectory(chn, dates; rt_start, rt_walk_start)
    mat = reconstruct_rt(
        chn; n = obs.n, breakpoint = _BREAKPOINT,
        rt_start = rt_start, rt_walk_start = rt_walk_start,
        ramp = RT_INTERVENTION_RAMP
    )
    first_date = isempty(dates) ? obs.seeding : minimum(dates)
    first_day = clamp(value(first_date - obs.seeding) + 1, rt_start, obs.n)
    days = first_day:obs.n
    ds = [obs.seeding + Day(d - 1) for d in days]
    q(d, p) = quantile(collect(skipmissing(@view mat[:, d])), p)
    return (
        ds,
        [q(d, 0.35) for d in days], [q(d, 0.65) for d in days],
        [q(d, 0.2) for d in days], [q(d, 0.8) for d in days],
        [q(d, 0.05) for d in days], [q(d, 0.95) for d in days],
    )
end

# The single-stream chains and their renewal-walk starts, keyed on the fit
# id the per-release tables use. Both the joint walk start and the day-1
# per-stream starts are the ones the per-stream implied-Rt figure above
# uses, so the bands here match it. Confirmed deaths has no trajectory
# here: its panel still draws its release points alone.
_stream_chains = (
    "joint" => (;
        chn = chn_joint, rt_start = _rt_start_plot,
        rt_walk_start = _rt_walk_start_joint,
    ),
    "cases" => (; chn = chn_cases, rt_start = 1, rt_walk_start = 1),
    "deaths" => (; chn = chn_deaths, rt_start = 1, rt_walk_start = 1),
    "confirmed" => (; chn = chn_confirmed, rt_start = 1, rt_walk_start = 1),
    "confirmed_deaths" => (;
        chn = chn_confirmed_deaths, rt_start = 1,
        rt_walk_start = 1,
    ),
    "treatment" => (; chn = chn_treatment, rt_start = 1, rt_walk_start = 1),
    "onsets" => (; chn = chn_onsets, rt_start = 1, rt_walk_start = 1),
    "exports" => (; chn = chn_exports, rt_start = 1, rt_walk_start = 1),
)

# Build a fit label => trajectory dictionary from a per-release table,
# restricted to the fits `_stream_chains` names. A fit with no row in `df`
# gets no trajectory, so its panel still draws its release points alone.
function _rt_trajectories(df)
    trajs = Dict{String, Any}()
    for (fid, cfg) in _stream_chains
        fdates = df.date[df.fit .== fid]
        isempty(fdates) && continue
        trajs[get(_fit_labels, fid, fid)] = _stream_rt_trajectory(
            cfg.chn, fdates; rt_start = cfg.rt_start,
            rt_walk_start = cfg.rt_walk_start
        )
    end
    return trajs
end

rt_stream_df = _release_data(
    "rt_by_release_by_stream.csv",
    _by_stream_schema
)
rt_stream_fig = plot_evolution_by_group(
    _fit_groups(rt_stream_df);
    trajectories = _rt_trajectories(rt_stream_df),
    ylabel = "Reproduction number",
    title = "Reproduction number as data accrued, by dataset",
    released_label = "Released estimate (per release)",
    refline = 1.0,
    ymax = _RT_AXIS_MAX,
    empty_note = "No per-dataset reproduction numbers saved yet."
);
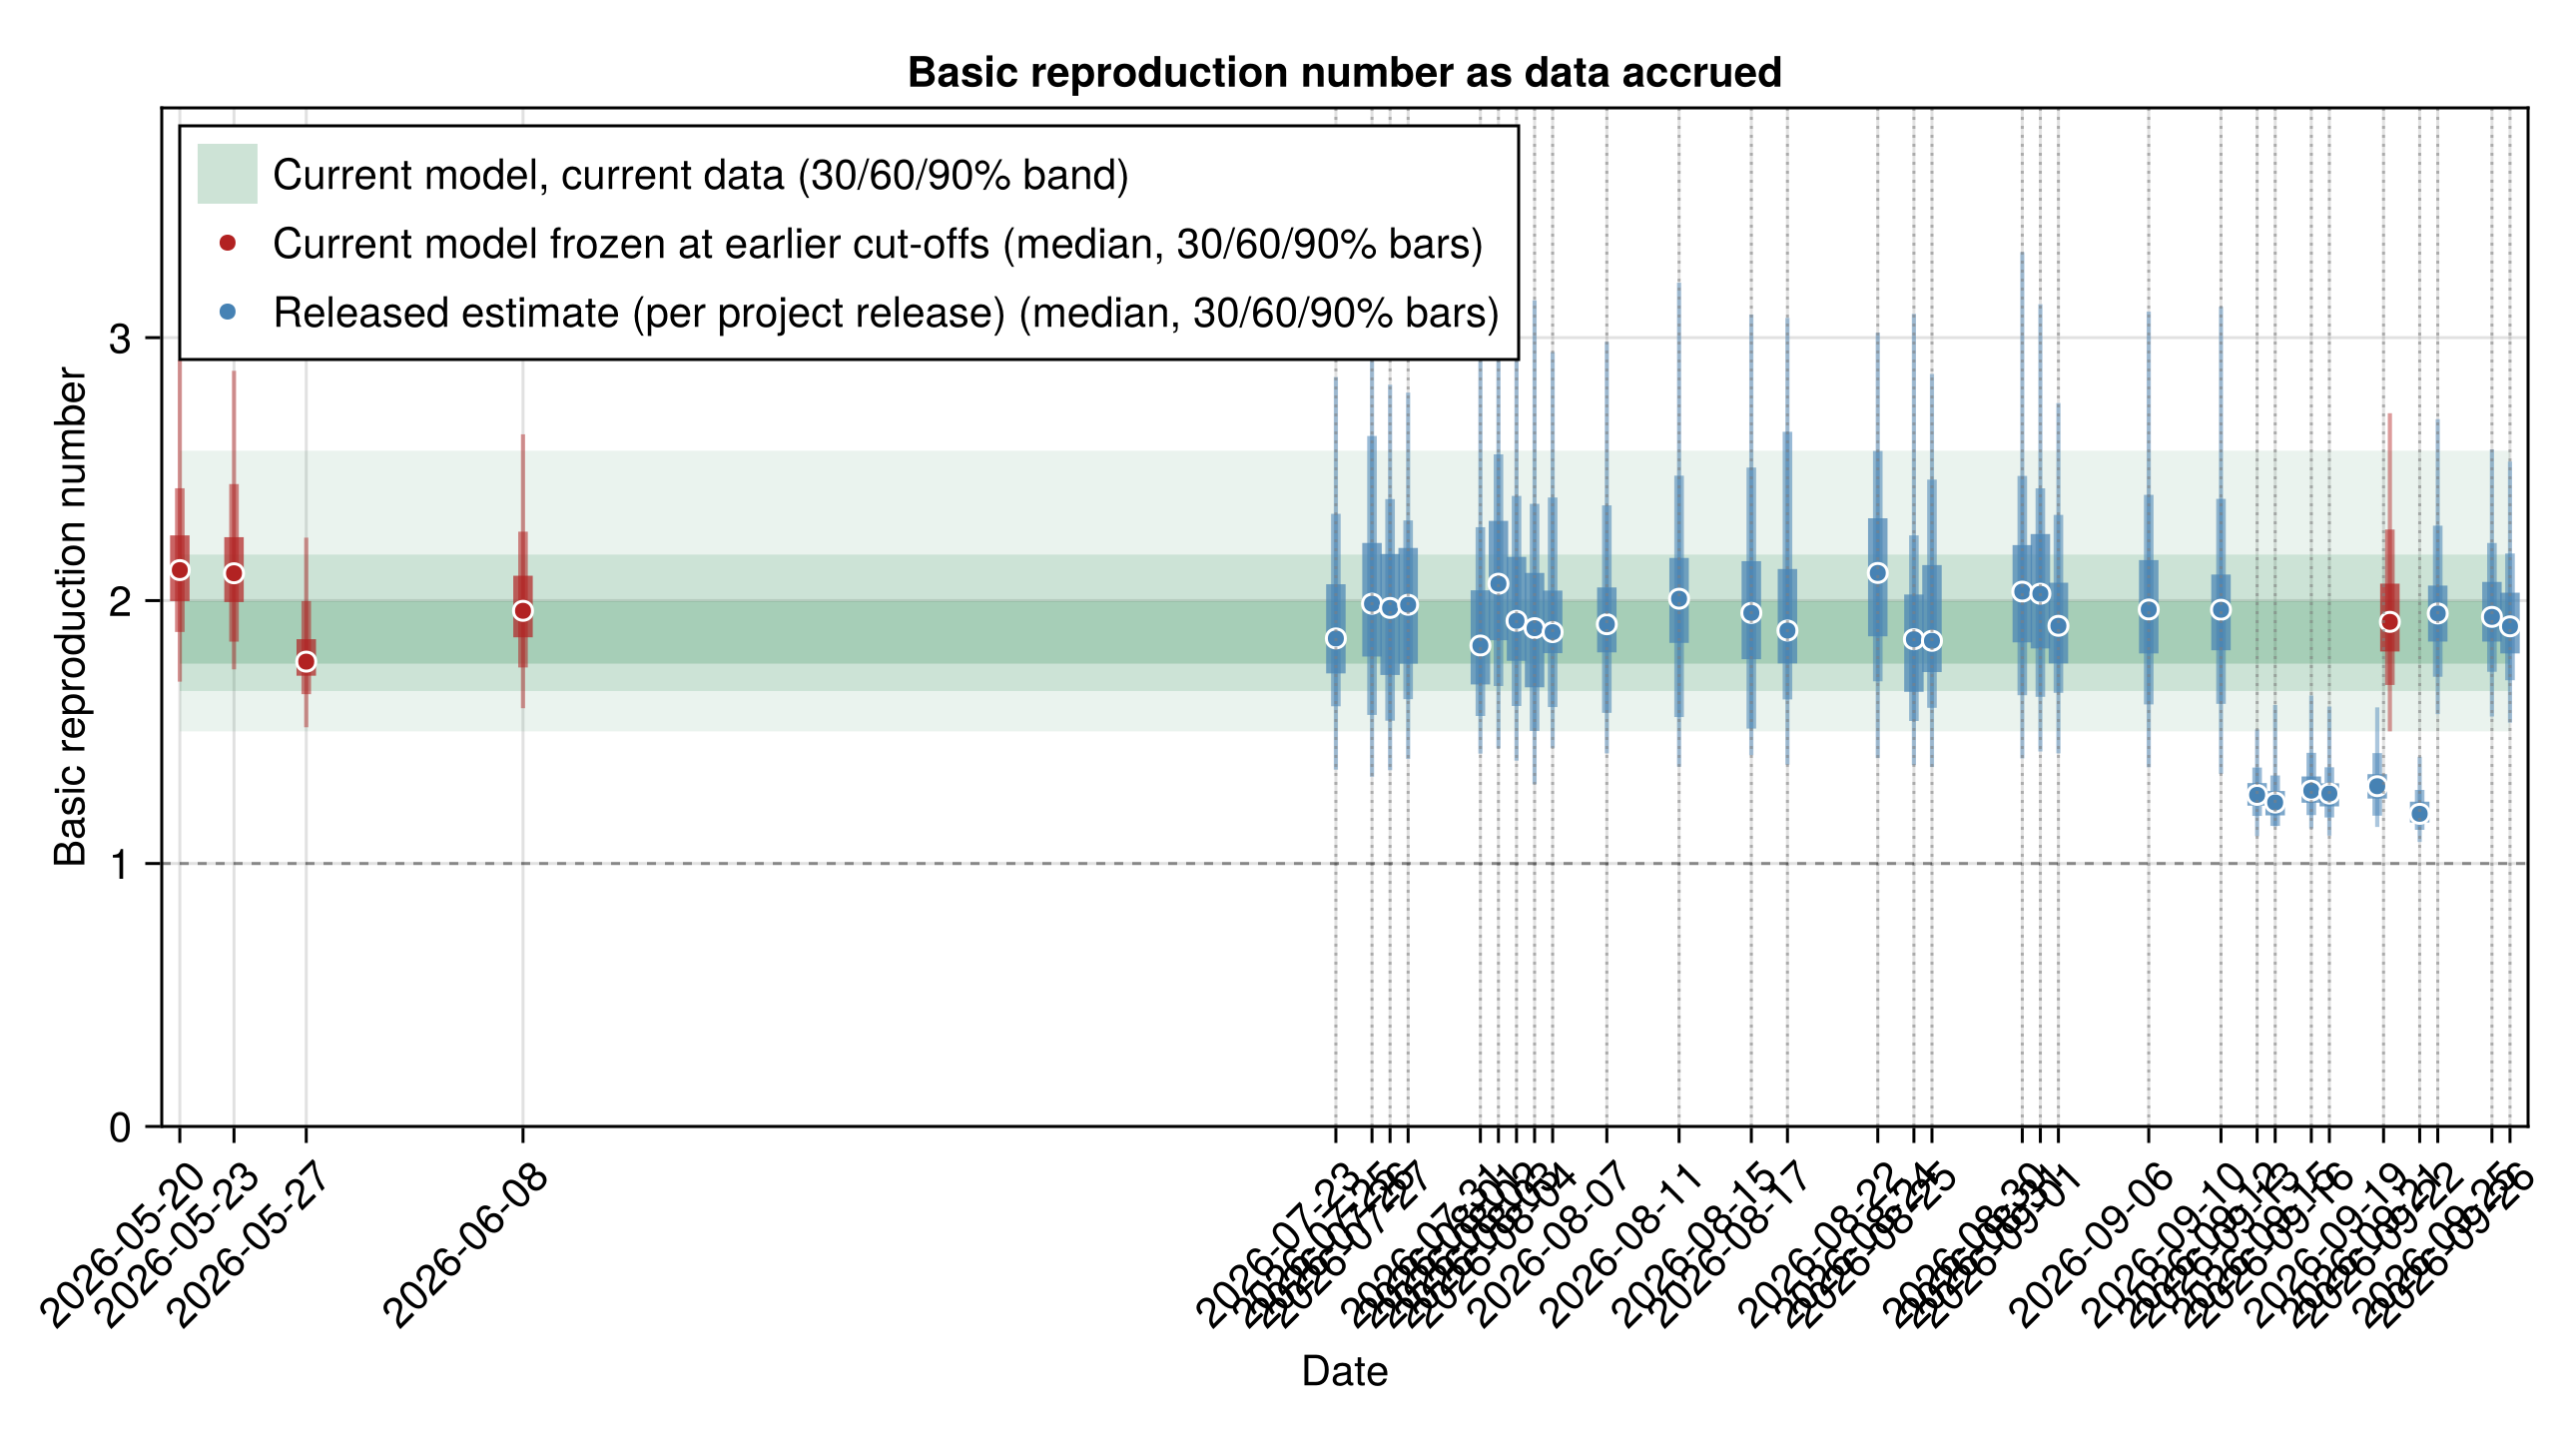
Basic reproduction number by release
The basic reproduction number
Basic reproduction number per release with frozen re-fits and the current-fit band
# Per-release R0 points from r0_by_release.csv, read through the typed
# fallback so a missing or header-only file (until a release carries
# `rt_state.log_R0` in its posterior draws) does not break the build. The
# schema mirrors rt_by_release.csv.
_r0_schema = (;
    release = String, date = Date, median = Float64,
    lo30 = Float64, hi30 = Float64, lo60 = Float64, hi60 = Float64,
    lo90 = Float64, hi90 = Float64,
)
r0_release_df = _release_data("r0_by_release.csv", _r0_schema)
r0_release = [
    (
        string(r.date), r.median, r.lo30, r.hi30, r.lo60, r.hi60,
        r.lo90, r.hi90,
    ) for r in eachrow(r0_release_df)
]

# The current model frozen at earlier cut-offs, one discrete estimate per
# cut-off, reusing the same frozen fits `frozen_matched` above already
# computed. No extra fits are run. Each tuple carries the median and
# 30/60/90% credible bounds of that frozen fit's own R0 draws, unrounded
# since R0 is continuous.
frozen_r0_matched = [
    (c, _ci369(frozen_R0(c); round_fn = identity)...)
        for c in _frozen_matched_cutoffs
]

# The current fit's R0 posterior is a single distribution rather than a
# daily series, so it summarises into a flat 30/60/90% reference band. The
# window runs from the earliest mark on the axis, the first frozen cut-off
# or release point, to the current cut-off, so the band reads behind both
# series rather than only their recent end.
r0_reference = let
    draws = r0_walk_draws(chn_joint)
    q(p) = quantile(draws, p)
    first_date = min(
        minimum(Date.(_frozen_matched_cutoffs)),
        isempty(r0_release_df.date) ? obs.cutoff :
            minimum(r0_release_df.date)
    )
    dates = [first_date, obs.cutoff]
    (
        dates, fill(q(0.35), 2), fill(q(0.65), 2), fill(q(0.2), 2),
        fill(q(0.8), 2), fill(q(0.05), 2), fill(q(0.95), 2),
    )
end

r0_evolution_fig = plot_estimate_evolution(
    r0_release;
    renewal = frozen_r0_matched,
    renewal_label = "Current model frozen at earlier cut-offs",
    trajectory = r0_reference,
    ylabel = "Basic reproduction number",
    title = "Basic reproduction number as data accrued",
    released_label = "Released estimate (per project release)",
    trajectory_label = "Current model, current data",
    refline = 1.0
);
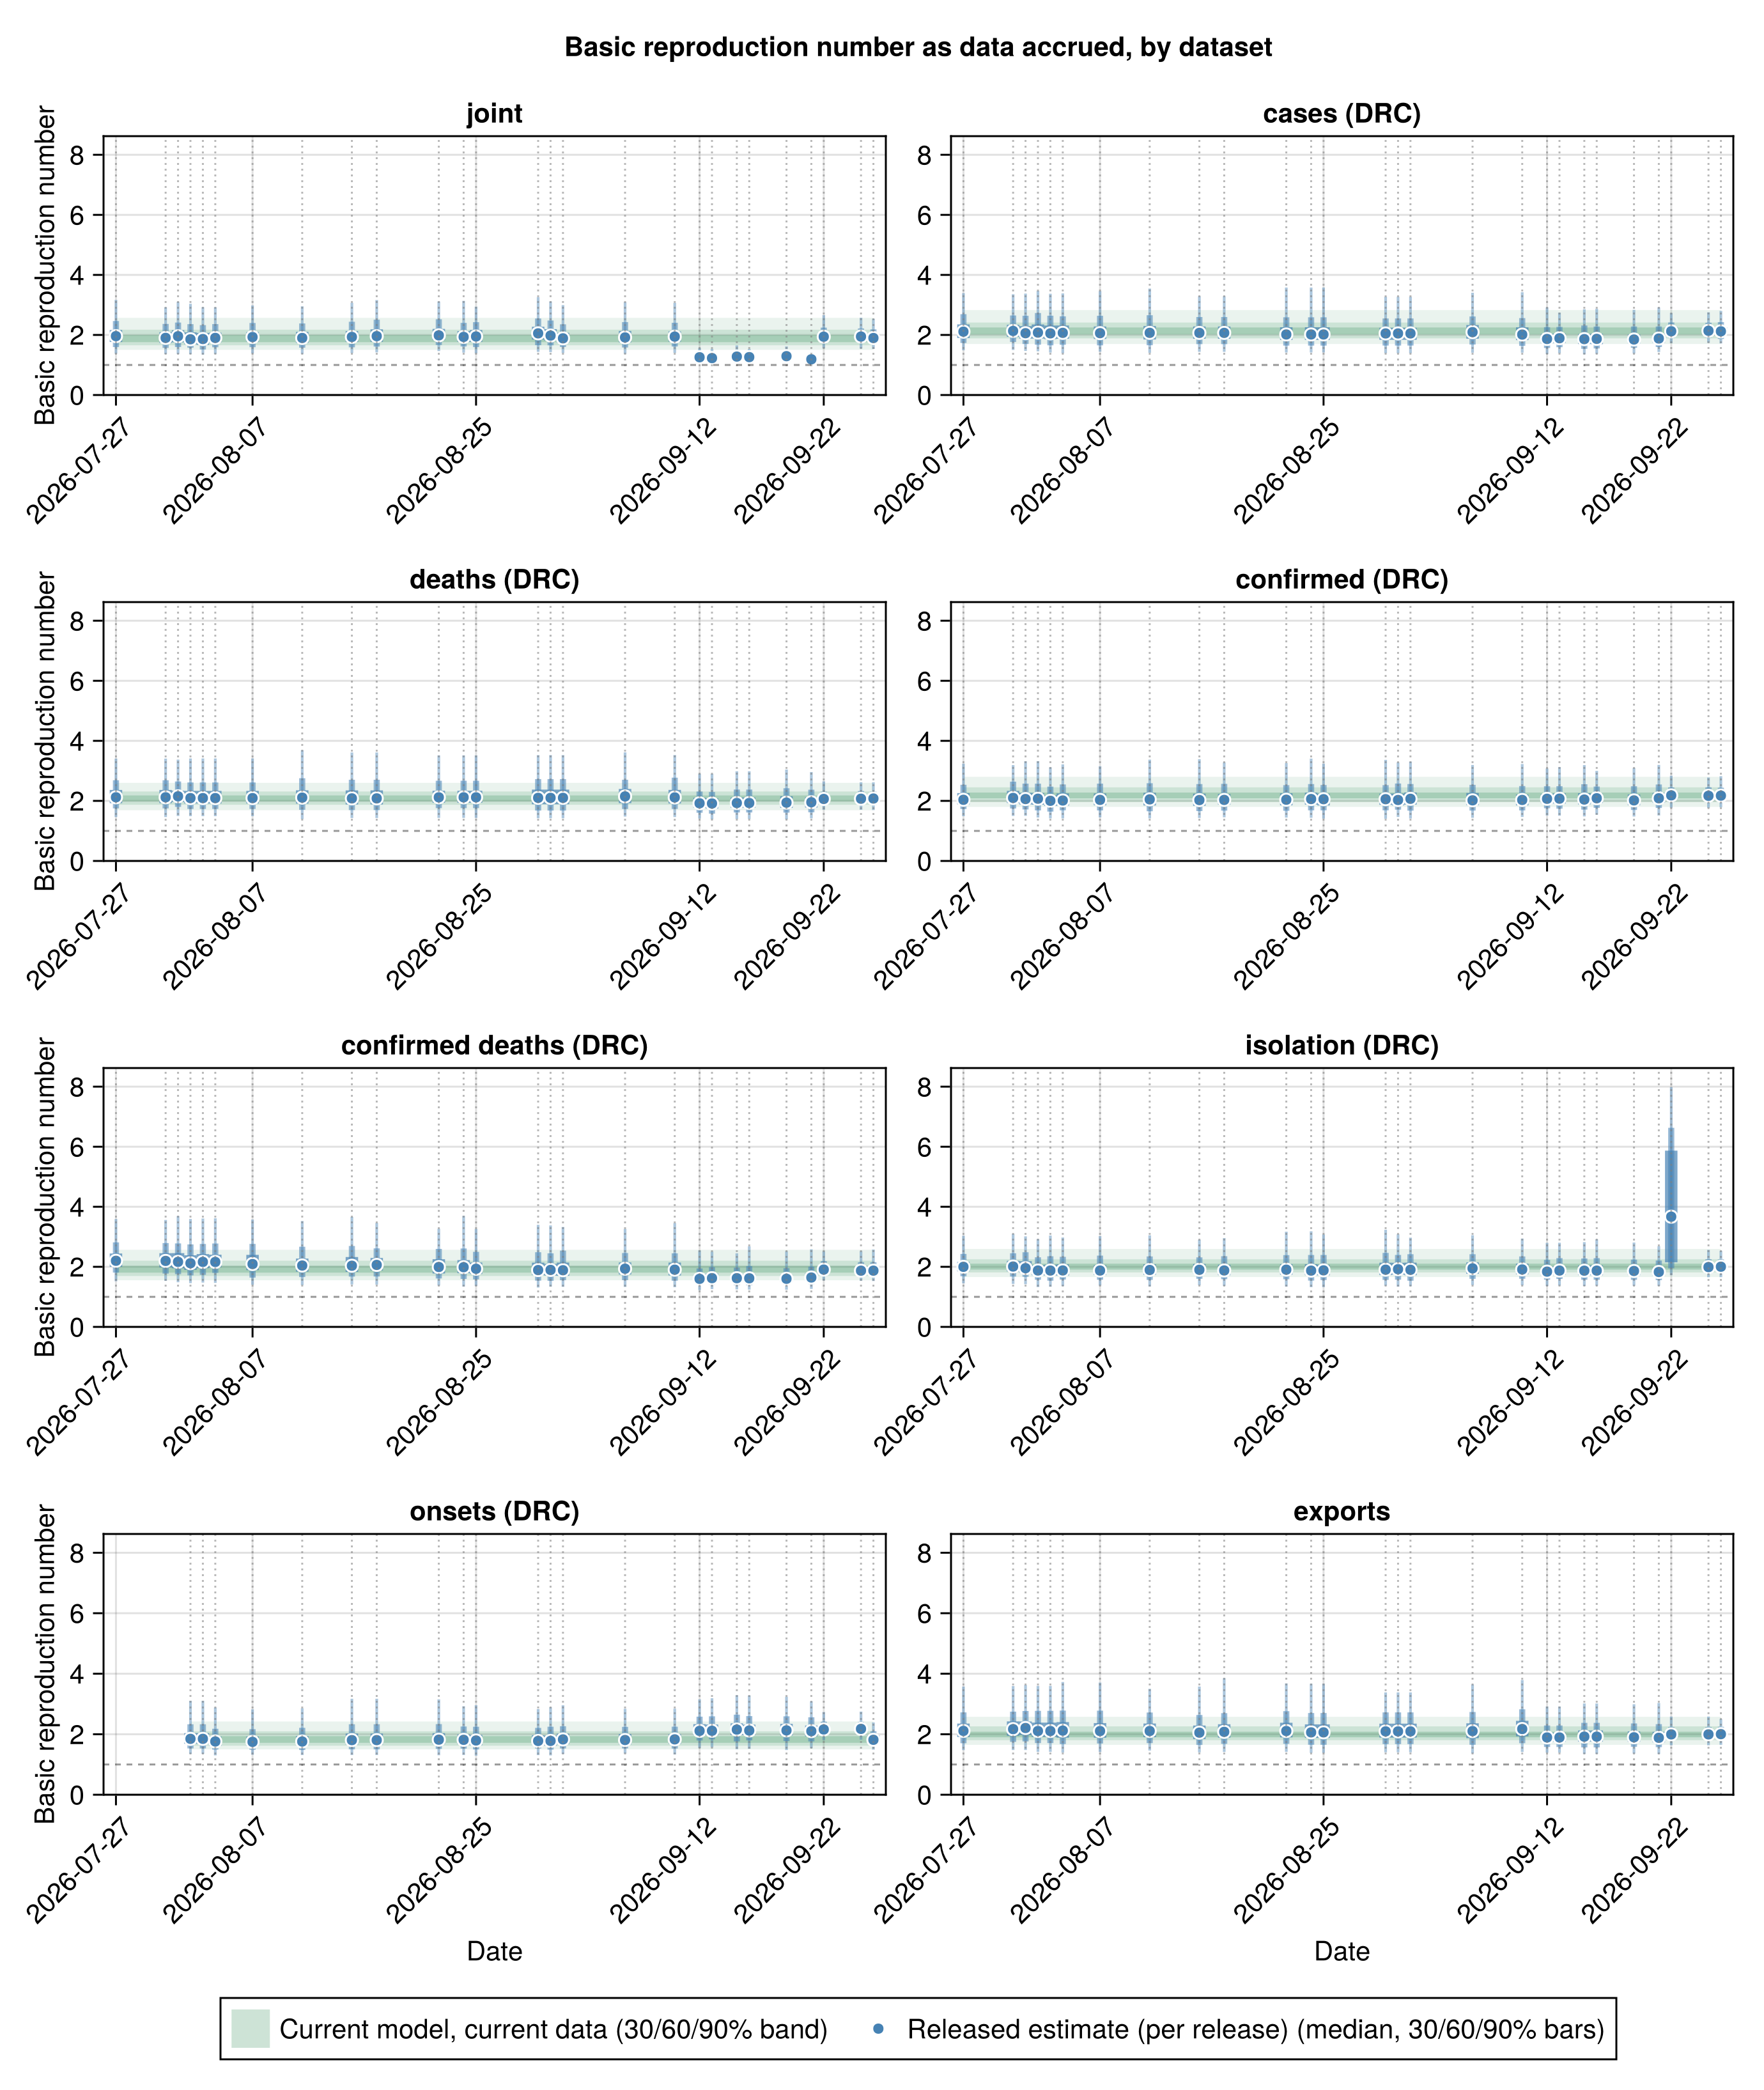
Basic reproduction number by release and dataset
The basic reproduction number estimated at each release, one panel per fit, the by-dataset counterpart of the figure above. Panels share a calendar axis and a y range, and
Basic reproduction number per release by fit
# Per-fit R0 flat reference band, the by-dataset counterpart of
# `r0_reference` above, a single distribution rather than a daily walk, so
# each fit's band is flat across its own release window. `r0_walk_draws`
# probes for the walk base, so a single-stream model built without its own
# renewal walk drops its band instead of erroring.
function _r0_stream_trajectory(chn, dates)
    draws = r0_walk_draws(chn)
    isnothing(draws) && return nothing
    q(p) = quantile(draws, p)
    first_date = isempty(dates) ? obs.seeding : minimum(dates)
    ds = [first_date, obs.cutoff]
    return (
        ds, fill(q(0.35), 2), fill(q(0.65), 2), fill(q(0.2), 2),
        fill(q(0.8), 2), fill(q(0.05), 2), fill(q(0.95), 2),
    )
end

# Build a fit label => trajectory dictionary from a per-release R0 table,
# restricted to the fits `_stream_chains` names, the same restriction the
# reproduction-number-by-dataset trajectories use. A fit with no row in
# `df`, or whose chain carries no walk base, gets no trajectory, so its
# panel still draws its release points alone.
function _r0_trajectories(df)
    trajs = Dict{String, Any}()
    for (fid, cfg) in _stream_chains
        fdates = df.date[df.fit .== fid]
        isempty(fdates) && continue
        traj = _r0_stream_trajectory(cfg.chn, fdates)
        isnothing(traj) || (trajs[get(_fit_labels, fid, fid)] = traj)
    end
    return trajs
end

r0_stream_df = _release_data(
    "r0_by_release_by_stream.csv",
    _by_stream_schema
)
r0_stream_fig = plot_evolution_by_group(
    _fit_groups(r0_stream_df);
    trajectories = _r0_trajectories(r0_stream_df),
    ylabel = "Basic reproduction number",
    title = "Basic reproduction number as data accrued, by dataset",
    released_label = "Released estimate (per release)",
    refline = 1.0,
    empty_note = "No per-dataset basic reproduction numbers saved yet."
);
Comparison with McCabe et al.
McCabe et al. published their estimates as scenarios at fixed situation-report cut-offs, each scenario carrying a 95% confidence interval. We show all three, the 18 May report, the 20 May update and the 27 May Lancet publication, as one panel each, with their intervals kept. Within a panel each method and scenario family is a single line, carrying its sweep over the nuisance assumptions: the case-fatality ratio, the geographic window and the doubling time. The geographic-spread scenarios come from exported cases and travel volume. Their back-calculation-from-deaths scenarios differ between the reports, since the 18 May report used 88 reported deaths and the 20 May update 131. The 20 May update also corrected the case-fatality ratios. McCabe's scenarios estimate cumulative cases at their report dates, though their report is not fully explicit about whether this is symptomatic cases or all infections. We take the like-for-like quantity to be our cumulative symptom onsets on the same dates, not the latent infections (which include the not-yet-symptomatic) or our current cut-off total. We read our value off the joint fit's cumulative-onset trajectory at the grid day for each report date, and show it with its credible interval.
McCabe scenarios with uncertainty against our estimates
function _ci90row(xs)
    return (
        round(Int, quantile(xs, 0.5)),
        round(Int, quantile(xs, 0.05)),
        round(Int, quantile(xs, 0.95)),
    )
end

# Our modelled cumulative symptom onsets on a McCabe report date, read off
# the joint fit's per-draw `cumulative_onsets` trajectory. The grid runs to
# the cut-off on day `n`, so the day-index for a date is `n` minus the days
# from that date back to the cut-off (`grid_day("2026-06-07") = n`,
# `"2026-05-20") = n - 18`, `"2026-05-18") = n - 20`).
_onset_trajs = let mat = chn_joint[:cumulative_onsets]
    [collect(v) for v in vec(collect(mat))]
end
# Inverse of `grid_date(day) = obs.cutoff - Day(obs.n - day)`: the day-index
# whose calendar date is `date`, using `value` (imported above) for the
# day count rather than the non-exported `Dates.date2epochdays`.
_grid_day(date) = obs.n - value(obs.cutoff - Date(date))
function _ours_on(date)
    d = _grid_day(date)
    return _ci90row(Float64[t[d] for t in _onset_trajs])
end

# Our matched cumulative-onset estimate for each report date, keyed by date so
# it lands beside that vintage's scenarios in its own panel.
mccabe_ours = Dict(
    "2026-05-18" => _ours_on("2026-05-18"),
    "2026-05-20" => _ours_on("2026-05-20"),
    "2026-05-27" => _ours_on("2026-05-27")
)

# One panel per report date; within a panel each method-and-family is one row,
# with the case-fatality / window / doubling-time sweep dodged onto that single
# line, so the ~40 scenarios keep their intervals without becoming ~40 rows.
matched_comparison_fig = plot_scenario_comparison(
    REPORT_SCENARIOS_CI;
    ours = mccabe_ours,
    date_titles = [
        "2026-05-18" => "18 May report",
        "2026-05-20" => "20 May update",
        "2026-05-27" => "27 May (Lancet)",
    ],
    xlabel = "Cumulative cases"
);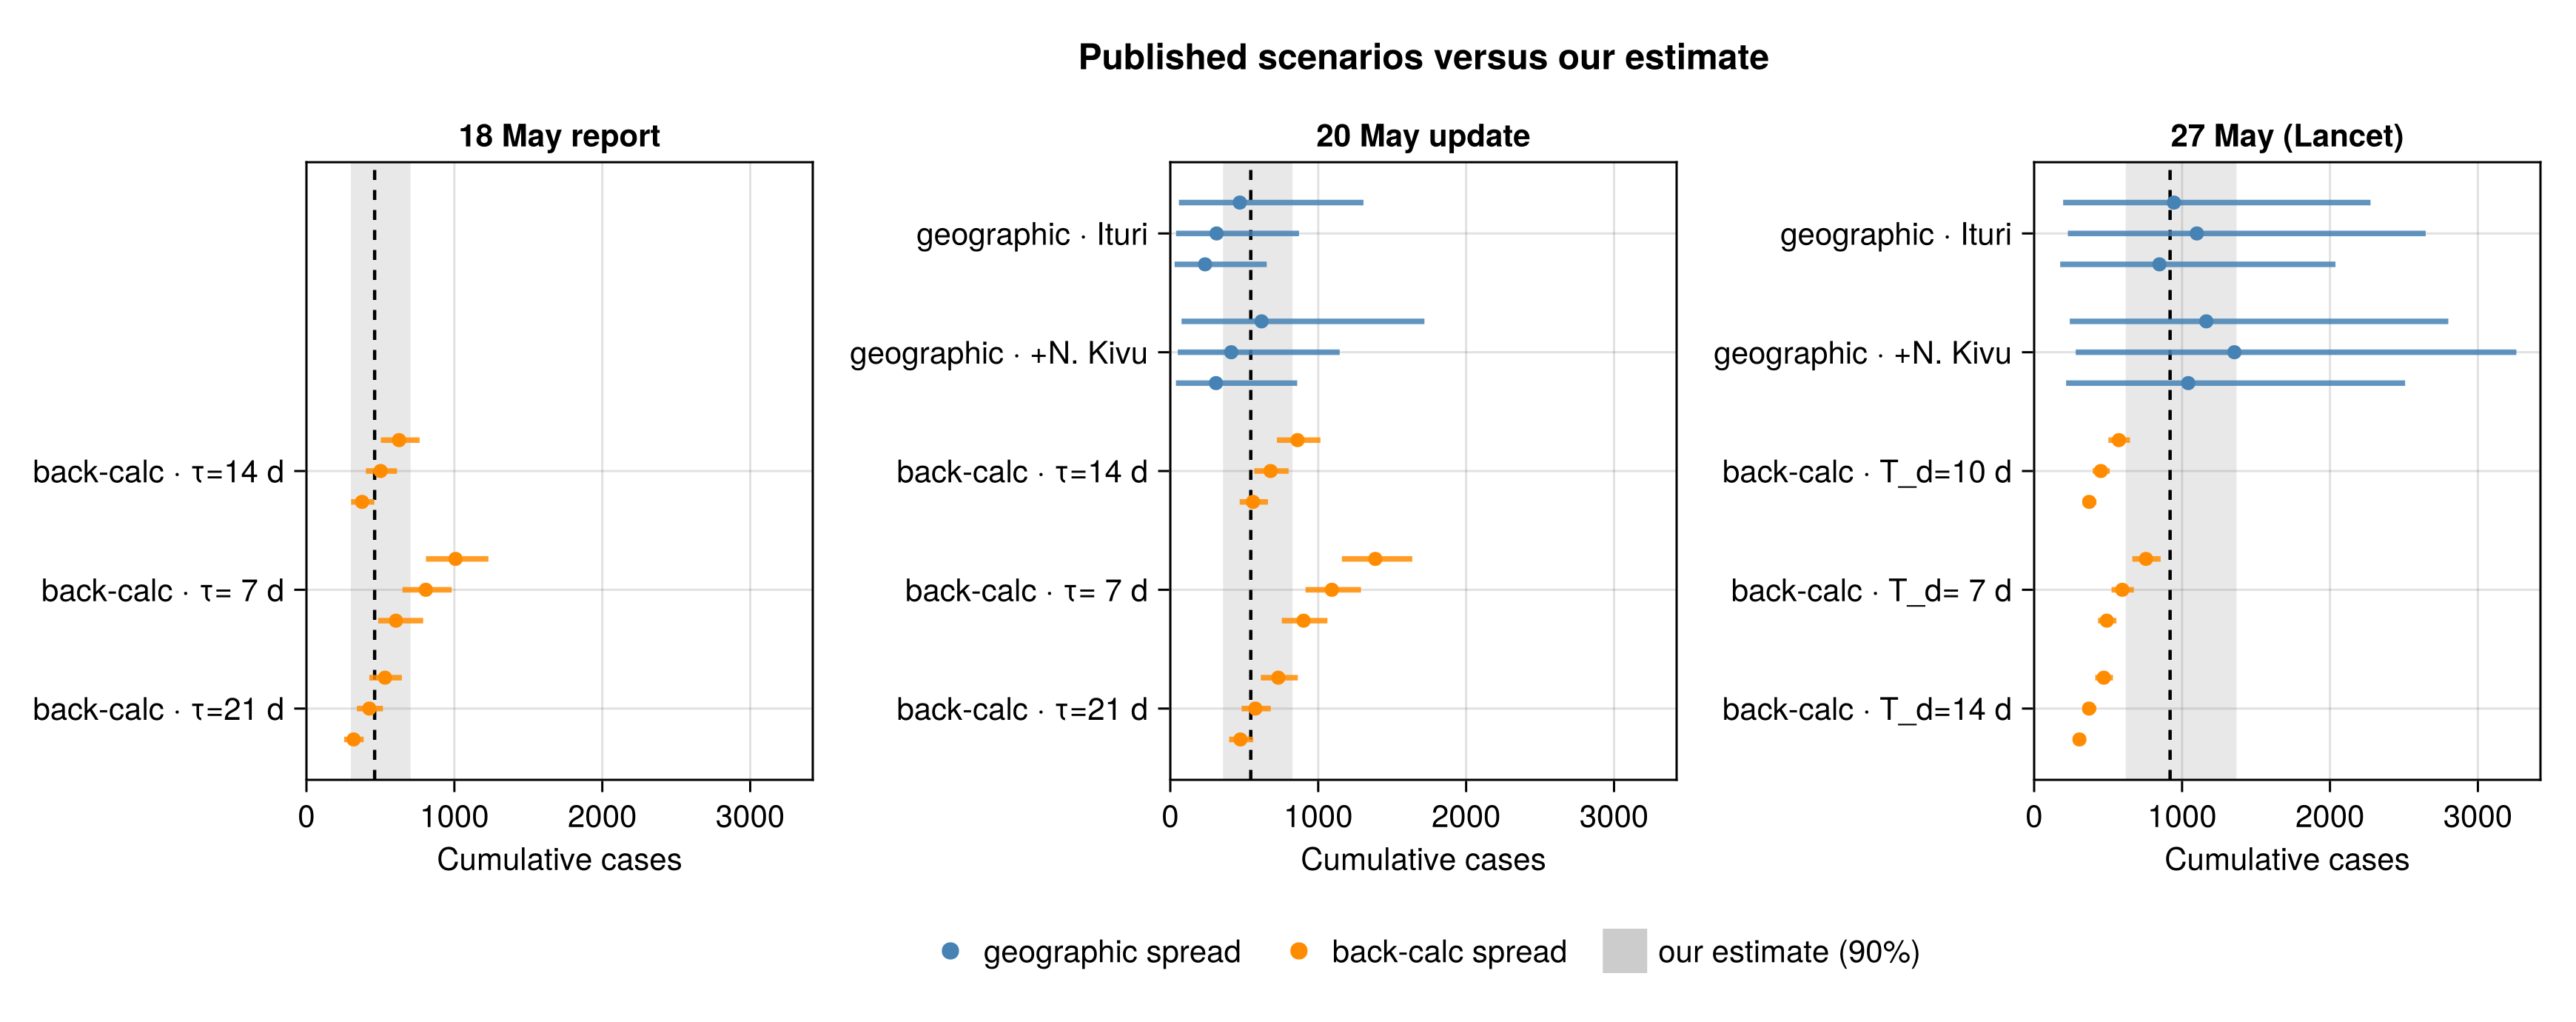
Their 95% confidence intervals come from exact negative-binomial counts for the geographic-spread method and a Poisson likelihood profile for the back-calculation from deaths.
Frozen-fit C_T intervals (kept for the CSV export, not shown)
# The estimate-evolution figure above already shows how the size estimate
# shifts as data accrues, so the side-by-side frozen-fit table is no longer
# rendered in the report; it is kept only to populate the published
# `frozen_matched_cutoffs.csv` export.
frozen_streams_table = streams_table(
    "frozen 20 May" => frozen_C("2026-05-20"),
    "frozen 23 May" => frozen_C("2026-05-23"),
    "frozen 27 May" => frozen_C("2026-05-27"),
    "frozen 8 June" => frozen_C(default_chamla_cutoff()),
    "current data" => posterior_C_joint
);
Comparison with Chamla et al.
A second group, Chamla et al. (2026) at the World Health Organization Regional Office for Africa, published a stochastic compartmental model of the same outbreak on 25 June 2026. Their model is a discrete-time susceptible-exposed-infectious-recovered-dead ensemble, recalibrated by simulation filtering to the laboratory-confirmed case series and anchored on the 598 confirmed cases reported by 8 June. It is then run forward to project the confirmed-case trajectory under a low, central and high transmissibility scenario.
Their published quantity is the cumulative confirmed-case count, with the reporting fraction held at one, so it does not adjust for the cases that are infected but never laboratory-confirmed. This is a different quantity from the cumulative cases this analysis and McCabe et al. estimate, which include the unconfirmed and unascertained. The like-for-like comparison is therefore against our own confirmed-case projection, not against our cumulative infection count.
We compare forward projections rather than refitting to their assumptions. We take our fit frozen at 8 June, the exact date of their confirmed-case calibration anchor. We roll its confirmed-case stream forward to the dates Chamla report, using the same machinery as the one-week-ahead forecast.
Project the 8 June fit forward and assemble the Chamla comparison
# The 8 June frozen joint fit matches Chamla's confirmed-case calibration
# anchor exactly and carries the confirmed-case testing history through then,
# so we forecast its confirmed-case stream to the dates Chamla report.
chamla_anchor = frozen_by_cutoff["2026-06-08"]

# Our projected cumulative confirmed cases at a horizon of `h` days past the
# 8 June cut-off, drawn from the 8 June model run past its cut-off and
# summarised as (median, 5%, 95%).
function _our_confirmed_h(h)
    fc = forecast_reported(
        fit_forecast("frozen_2026-06-08");
        horizon = h,
        obs_cases = chamla_anchor.o.reported_cases,
        obs_deaths = chamla_anchor.o.total_deaths,
        obs_confirmed = chamla_anchor.o.confirmed_cases,
        obs_confirmed_deaths = chamla_anchor.o.confirmed_deaths
    )
    return _ci90row(float.(fc.confirmed_cum))
end

# Our projection at Chamla's forward report dates (10 and 24 June, week 12):
# the anchor day is the fitted confirmed total at 8 June, each later date a
# forward forecast. Reused for the matched-date table and the week-12 figure.
chamla_fan = map(["2026-06-08", "2026-06-10", "2026-06-24"]) do d
    h = value(Date(d) - chamla_anchor.cutoff)
    row = h == 0 ?
        (
            chamla_anchor.o.confirmed_cases, chamla_anchor.o.confirmed_cases,
            chamla_anchor.o.confirmed_cases,
        ) : _our_confirmed_h(h)
    (d, row...)
end
_fan_at(date) =
let r = first(x for x in chamla_fan if x[1] == date)
    (r[2], r[3], r[4])
end
ours_10jun = _fan_at("2026-06-10")
ours_24jun = _fan_at("2026-06-24")

# Observed confirmed totals on Chamla's forward report dates, read from the
# confirmed-case history frozen at each date.
observed_10jun = freeze_observations("2026-06-10").confirmed_cases
observed_24jun = freeze_observations("2026-06-24").confirmed_cases

# Observed confirmed cases over the comparison window: the daily cumulative
# series read off the chain's grid from 18 May (Chamla's first projected point)
# to the cut-off.
chamla_obs_series = let
    ds = [grid_date(d) for d in obs.confirmed_history.days]
    cs = obs.confirmed_history.counts
    [(string(ds[i]), cs[i]) for i in eachindex(ds) if ds[i] >= Date("2026-05-18")]
end

# Chamla's central confirmed-case projection over the comparison window; their
# later, far-larger horizons are noted in the text rather than plotted so the
# window stays legible.
chamla_central_window = CHAMLA_CONFIRMED_CENTRAL[1:4]

chamla_projection_fig = plot_projection_comparison(;
    external = chamla_central_window,
    ours = chamla_fan,
    observed = chamla_obs_series,
    external_label = "Chamla et al. central (R₀=1.71)",
    ours_label = "Our projection (from 8 June)",
    observed_label = "Observed confirmed",
    title = "Confirmed-case projections versus observed, from mid-May"
);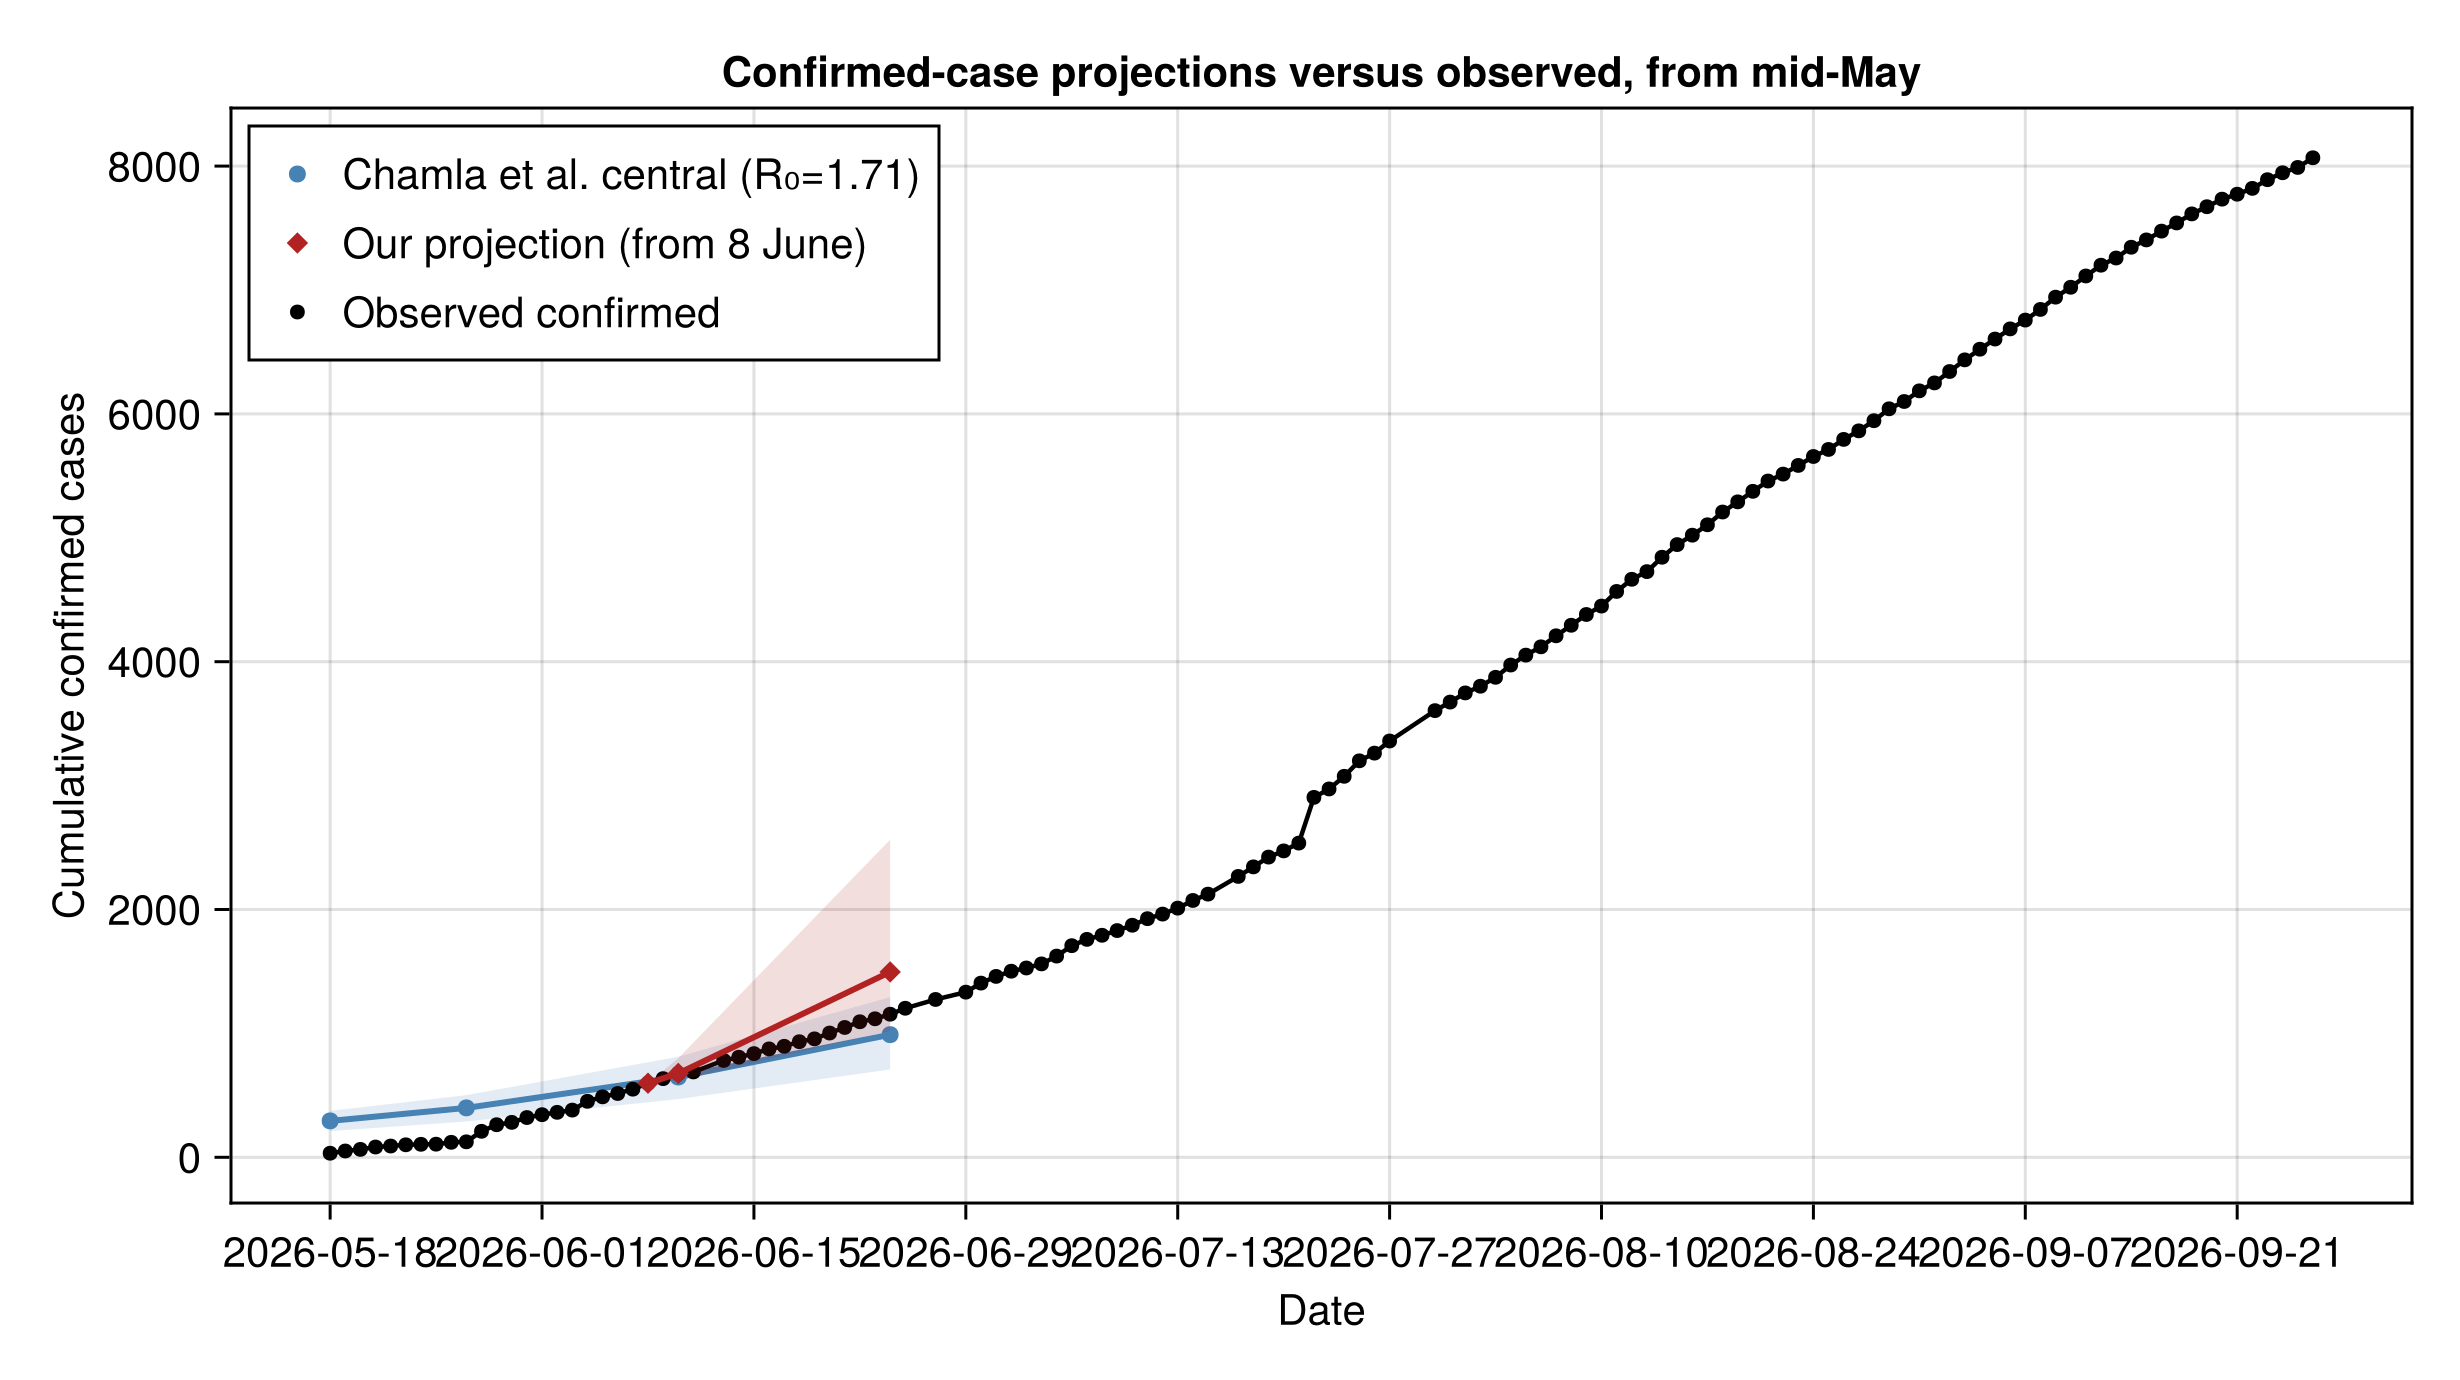
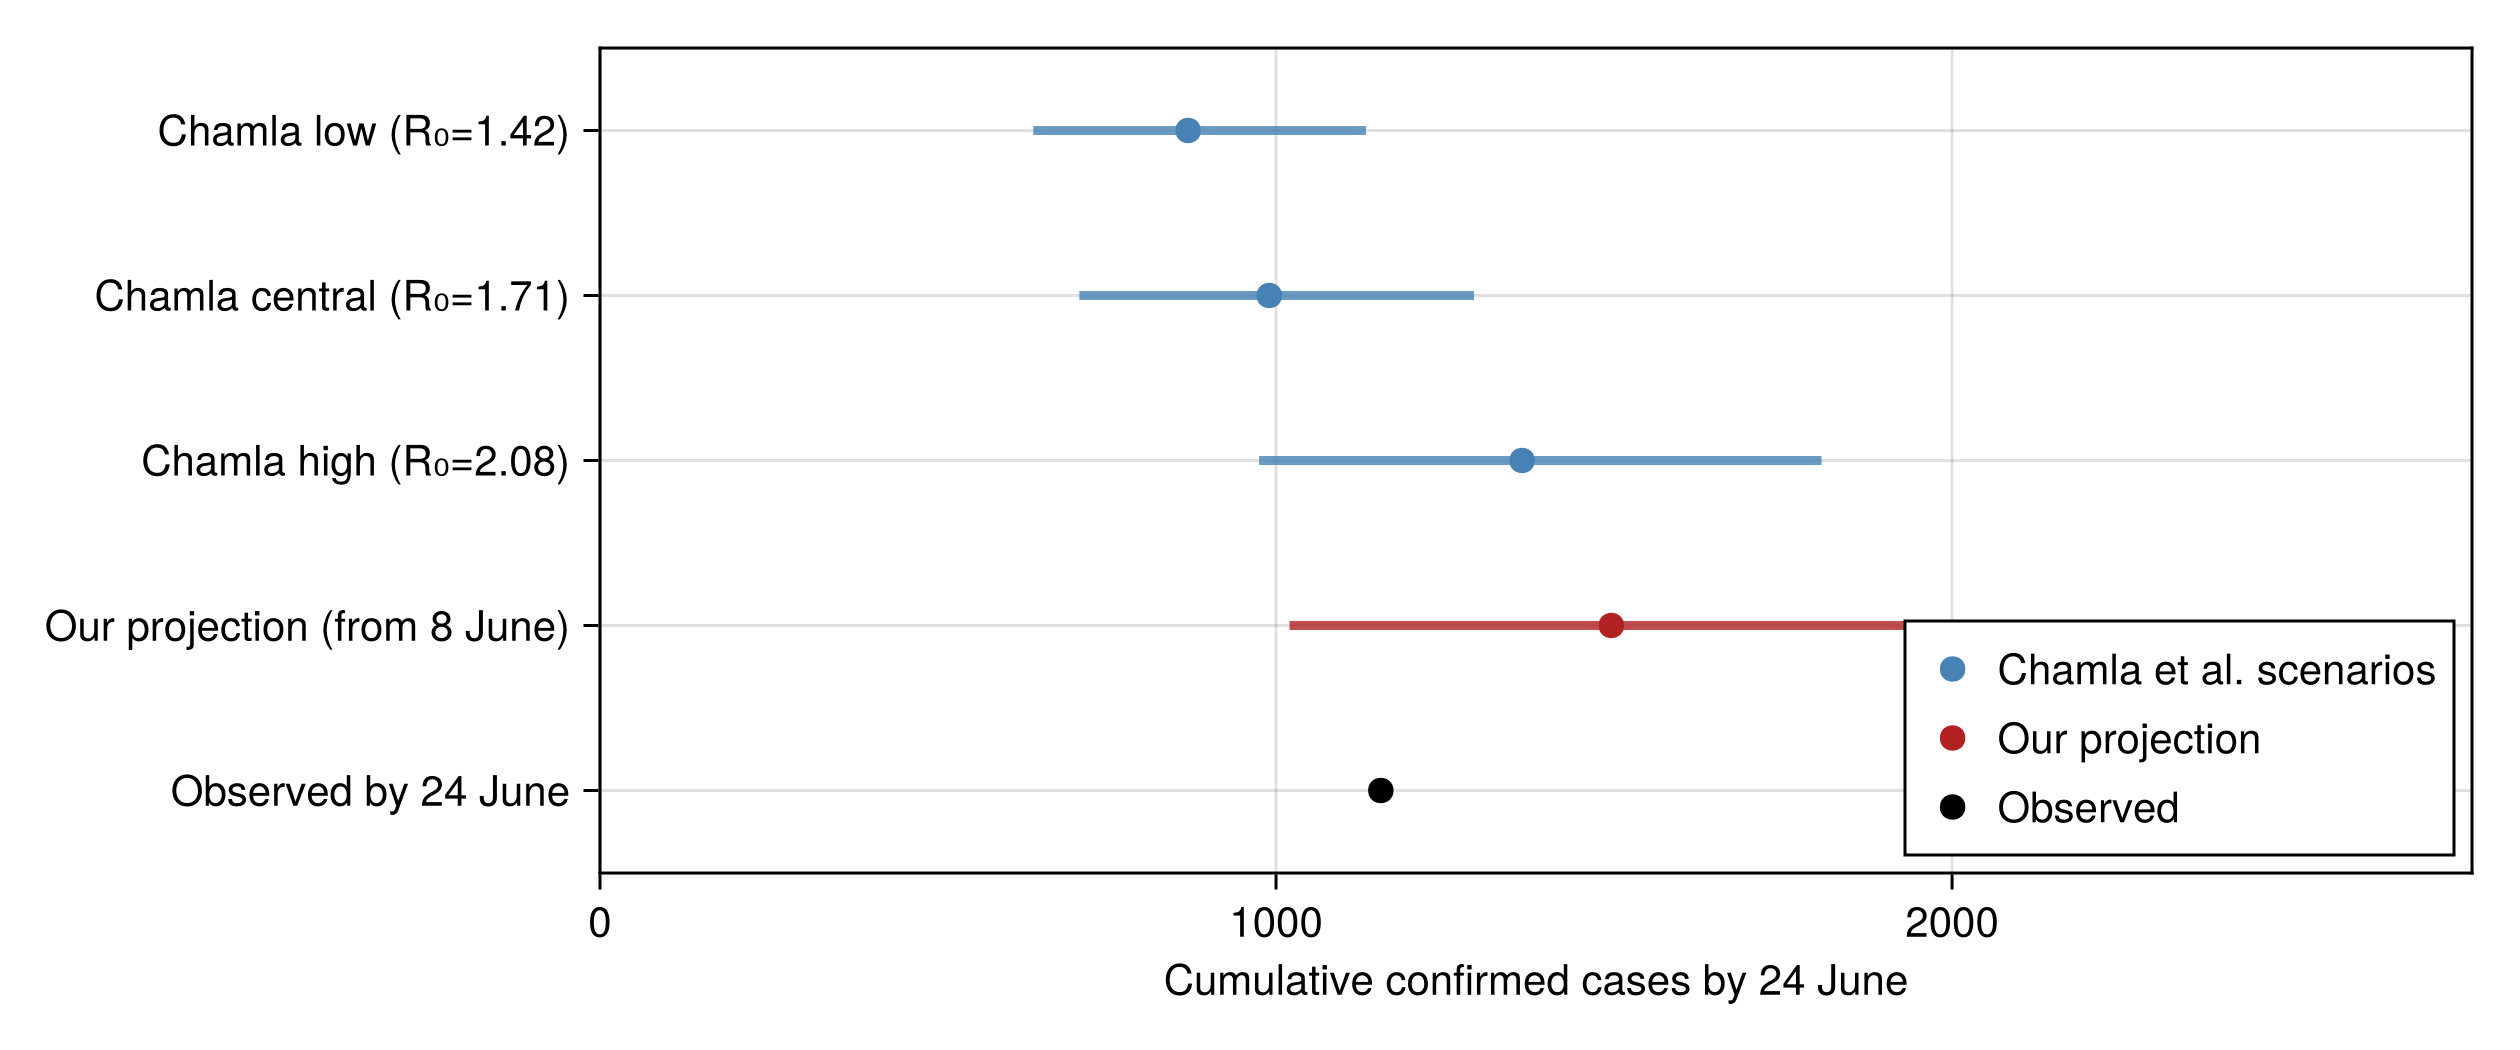
By 24 June their central scenario projected just under a thousand confirmed cases, and their low and high scenarios ranged from roughly 870 to 1360.
Week-12 (24 June) scenario spread against ours and observed
chamla_w12_rows = vcat(
    [(label, m, lo, hi) for (label, m, lo, hi) in CHAMLA_CONFIRMED_W12],
    [("Our projection (from 8 June)", ours_24jun...)],
    [
        (
            "Observed by 24 June", observed_24jun,
            observed_24jun, observed_24jun,
        ),
    ]
)
chamla_w12_groups = vcat(
    fill("Chamla et al. scenarios", 3),
    ["Our projection"], ["Observed"]
)

chamla_w12_fig = plot_estimate_comparison(
    chamla_w12_rows;
    xlabel = "Cumulative confirmed cases by 24 June",
    groups = chamla_w12_groups,
    group_colours = [
        "Chamla et al. scenarios" => :steelblue,
        "Our projection" => :firebrick,
        "Observed" => :black,
    ]
);
Matched-date projection numbers (10 and 24 June)
chamla_comparison_table = let
    fmt(t) = string(t[1], " (", t[2], "–", t[3], ")")
    central(date) =
    let r = first(
            x for x in CHAMLA_CONFIRMED_CENTRAL
                if x[1] == date
        )
        fmt((r[2], r[3], r[4]))
    end
    DataFrame(
        "Date" => ["10 June", "24 June"],
        "Chamla central (90% PI)" => [
            central("2026-06-10"),
            central("2026-06-24"),
        ],
        "Our projection (90% CrI)" => [fmt(ours_10jun), fmt(ours_24jun)],
        "Observed confirmed" => [
            string(observed_10jun),
            string(observed_24jun),
        ]
    )
end;| Date | Chamla central (90% PI) | Our projection (90% CrI) | Observed confirmed |
|---|---|---|---|
| 10 June | 648 (470–812) | 677 (620–800) | 676 |
| 24 June | 990 (709–1293) | 1496 (1020–2564) | 1155 |
Beyond the comparison window their central scenario continues to roughly 8200 confirmed cases by mid-September, with the high scenario far higher.
Reproduction number behind the projection
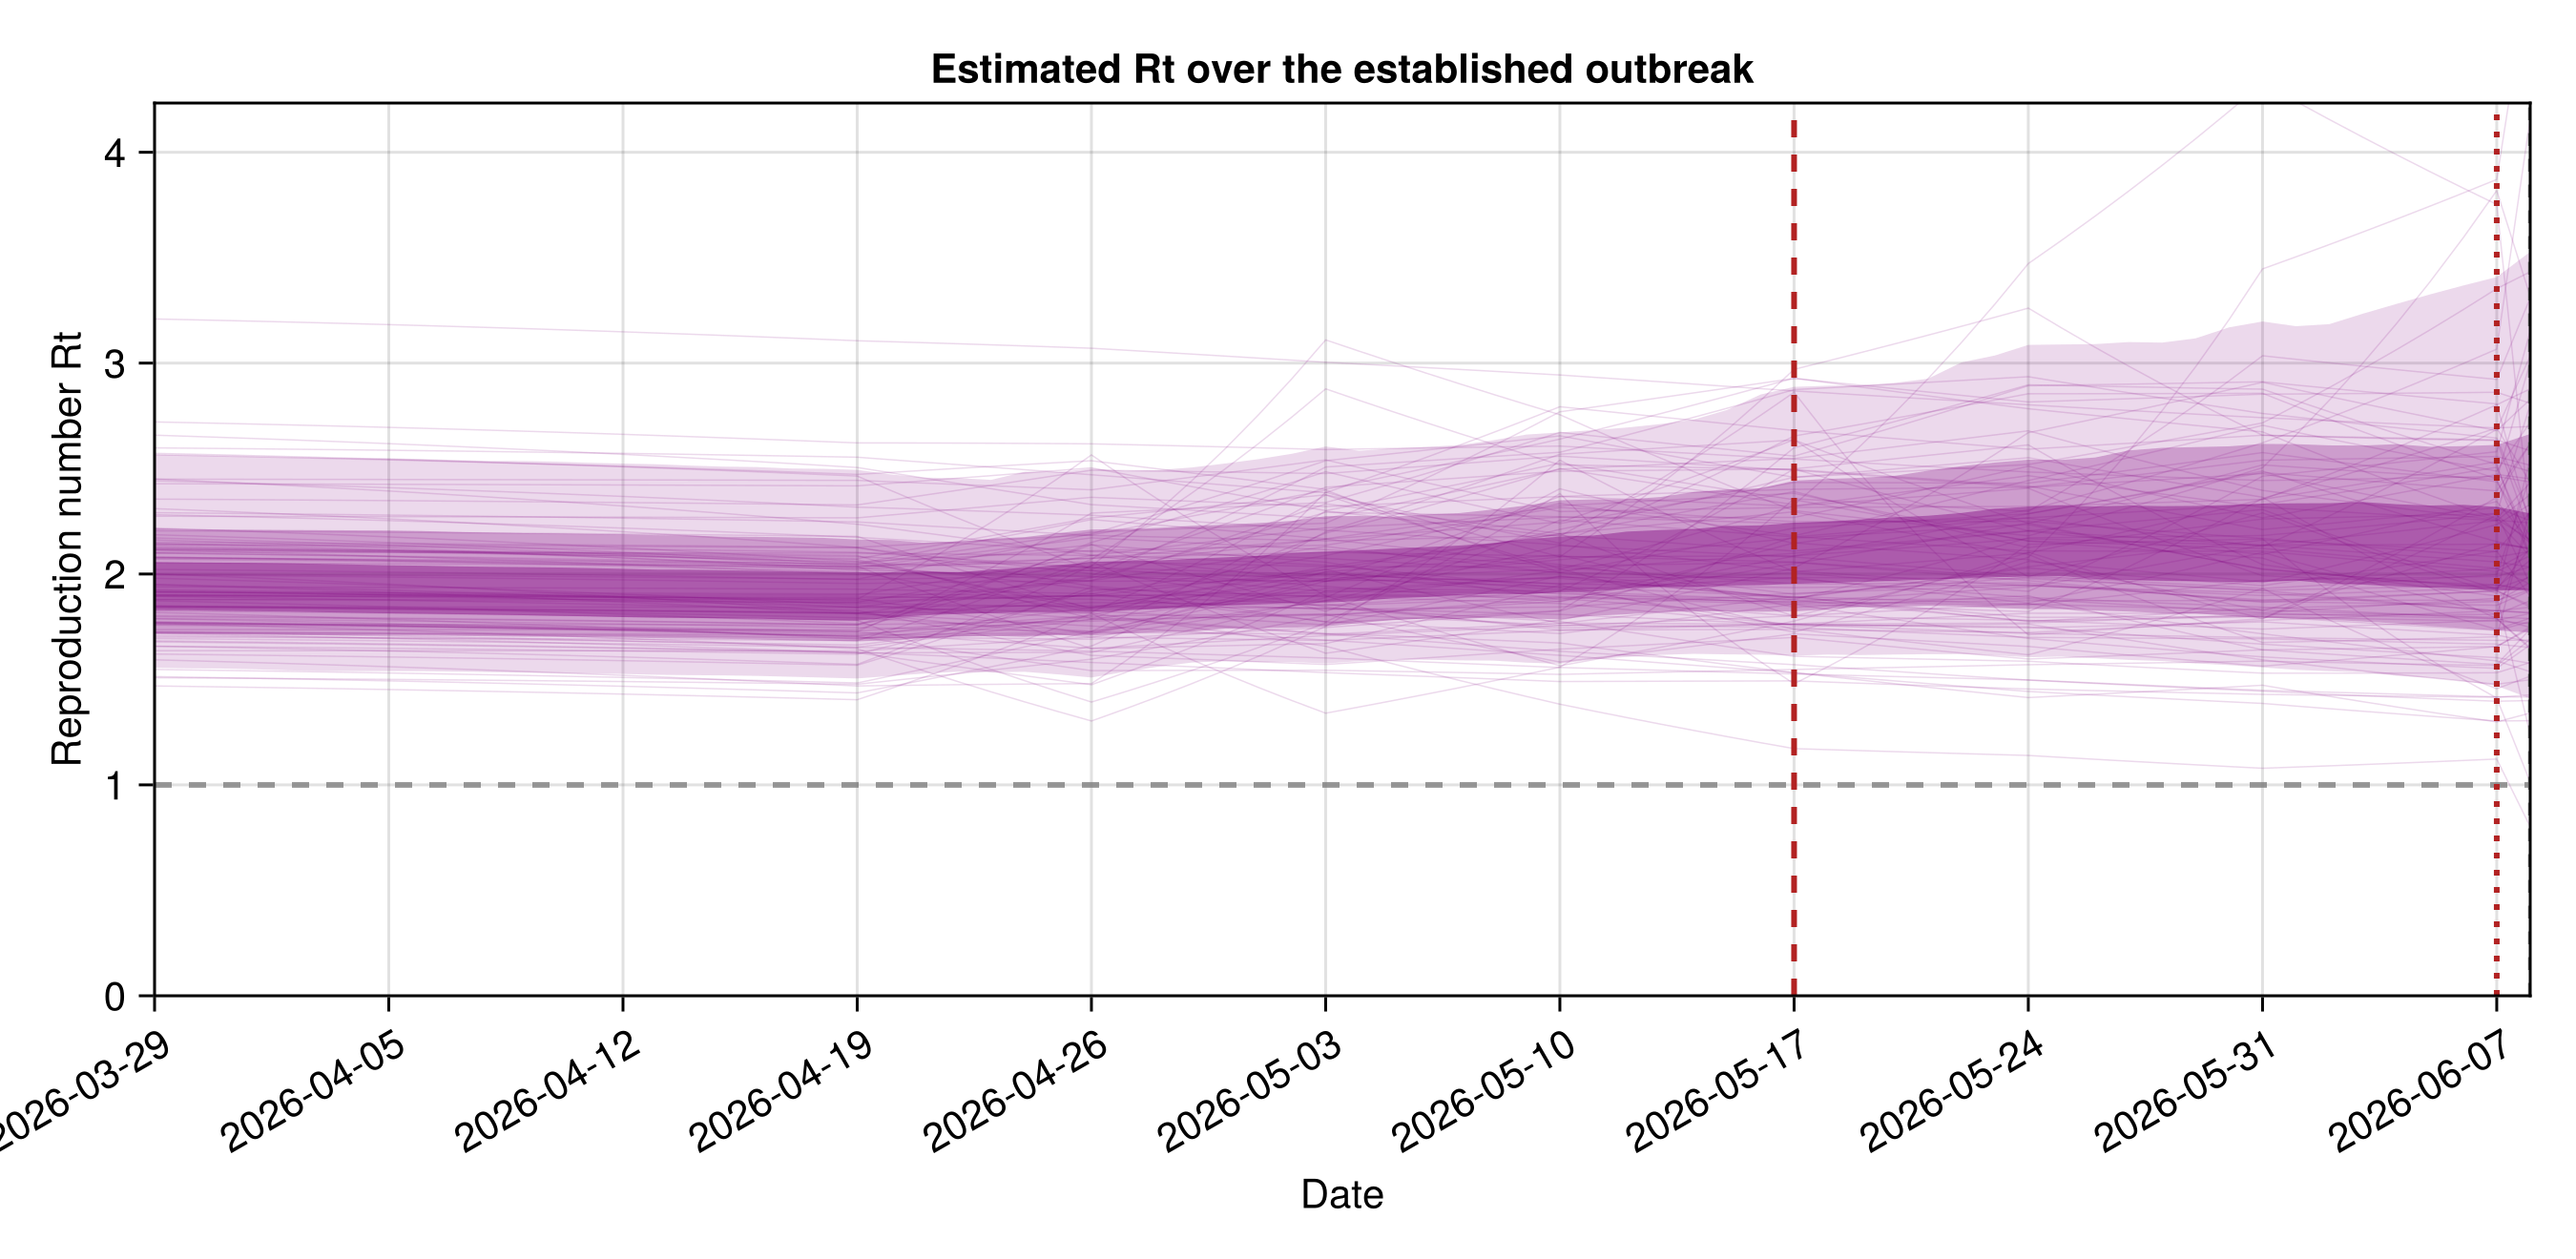
The forward projection above is carried by the reproduction-number trajectory our 8 June fit estimated, a quantity we report in its own right rather than as a comparison. It declines over the weeks leading to the cut-off, and that decline is what bends the projected trajectory away from sustained early growth.
Reproduction number as estimated by the 8 June fit
# Reconstruct the reproduction-number trajectory the 8 June fit estimated,
# mirroring the current-data R_t figure but with the frozen vintage's own grid,
# breakpoint and renewal start.
chamla_rt_obs = chamla_anchor.o
chamla_rt_breakpoint = chamla_rt_obs.n - chamla_rt_obs.who_first_sitrep_days
chamla_rt_start = clamp(
    chamla_rt_obs.n - round(Int, chamla_rt_obs.tmrca_days) + RENEWAL_START_LEAD,
    1, chamla_rt_obs.n
)
chamla_rt_fig = plot_rt(
    chamla_anchor.chn;
    n = chamla_rt_obs.n, breakpoint = chamla_rt_breakpoint,
    rt_start = chamla_rt_start,
    rt_walk_start = clamp(
        chamla_rt_breakpoint - RT_WALK_LEAD,
        chamla_rt_start, chamla_rt_obs.n
    ),
    as_of_date = string(chamla_rt_obs.cutoff),
    seeding = chamla_rt_obs.seeding, ramp = RT_INTERVENTION_RAMP
);
Delay sensitivity
The death stream dates the outbreak from how far deaths lag symptom onset, so the assumed onset-to-death delay sets the implied infection count. The baseline uses the hospital-pathway delay from the Isiro 2012 line-list reanalysis (onset to admission then admission to death, implied mean about 12 d). We re-fit the joint model under the community-pathway delay from the same reanalysis: the delay for deaths that occur in the community without a recorded admission. This delay is shorter (implied mean about 8 d). Both pathways come from the line list, so this varies the actual delay assumption rather than an arbitrary scenario. The re-fit is the headline model, with its provinces and in-care split, and changes only the delay. It uses the headline's sampler settings.
The infection count to date shifts with the assumed delay, and the table and overlaid densities below show how far.
Re-fit the joint under the community-pathway onset-to-death delay
# The sensitivity re-fits (community-delay variant) are
# defined in the fit registry (`docs/fits/registry.jl`) and loaded through the cache
# (when enabled) in the setup block above.
posterior_C_community_delay = RUN_SENSITIVITY ?
    vec(Array(chn_joint_community_delay[:C_T])) : nothing;
Delay-sensitivity infection-count table
delay_sensitivity_table = RUN_SENSITIVITY ?
    streams_table(
        "baseline (hospital pathway)" => posterior_C_joint,
        "community pathway" => posterior_C_community_delay
    ) :
    Markdown.md"_Delay sensitivity analysis not shown in this build._";
Delay sensitivity analysis not shown in this build.
Delay-sensitivity infection-count density plot
delay_sensitivity_fig = RUN_SENSITIVITY ?
    plot_cumulative_cases(
        "baseline (hospital pathway)" => posterior_C_joint,
        "community pathway" => posterior_C_community_delay; scenarios = []
    ) :
    Markdown.md"_Delay sensitivity analysis not shown in this build._";
Delay sensitivity analysis not shown in this build.
Tree-prior sensitivity
The outbreak-age estimate depends on the coalescent tree prior assumed in the BEAST X analysis. The baseline uses the more flexible Skygrid non-parametric model, which dates the common ancestor to 15 March 2026 (
Re-fit the joint under the Exponential growth tree prior
# The Exponential-growth re-fit (and its `tmrca_days` offset) is defined in the fit
# registry (`docs/fits/registry.jl`) and loaded through the cache (when enabled) in the
# setup block above.
posterior_C_exp_growth = RUN_SENSITIVITY ?
    vec(Array(chn_joint_exp_growth_clock[:C_T])) : nothing
T_skygrid = vec(Array(chn_joint[:T]))
T_exp_growth = RUN_SENSITIVITY ? vec(Array(chn_joint_exp_growth_clock[:T])) : nothing;
The infection count to date under the two tree priors, side by side. A slightly earlier common ancestor (Exponential growth) permits a marginally older outbreak, though the difference is small because the evolutionary rates are nearly identical.
Tree-prior infection-count table
clock_sensitivity_C_table = RUN_SENSITIVITY ?
    streams_table(
        "Skygrid (baseline)" => posterior_C_joint,
        "Exponential growth" => posterior_C_exp_growth
    ) :
    Markdown.md"_Tree-prior sensitivity analysis not shown in this build._";
Tree-prior sensitivity analysis not shown in this build.
Tree-prior infection-count density plot
clock_sensitivity_C_fig = RUN_SENSITIVITY ?
    plot_cumulative_cases(
        "Skygrid (baseline)" => posterior_C_joint,
        "Exponential growth" => posterior_C_exp_growth; scenarios = []
    ) :
    Markdown.md"_Tree-prior sensitivity analysis not shown in this build._";
Tree-prior sensitivity analysis not shown in this build.
The outbreak age, the number of days from seeding to the cut-off, under the two tree priors.
Tree-prior outbreak-age table
clock_sensitivity_T_table = RUN_SENSITIVITY ?
    streams_table(
        "Skygrid (baseline)" => T_skygrid,
        "Exponential growth" => T_exp_growth; digits = 0
    ) :
    Markdown.md"_Tree-prior sensitivity analysis not shown in this build._";
Tree-prior sensitivity analysis not shown in this build.
Tree-prior outbreak-age density plot
clock_sensitivity_T_fig = RUN_SENSITIVITY ?
    plot_density_overlay(
        "Skygrid (baseline)" => T_skygrid,
        "Exponential growth" => T_exp_growth;
        xlabel = "Outbreak age (days before cut-off)",
        title = "Posterior outbreak age by tree prior", lower = 0
    ) :
    Markdown.md"_Tree-prior sensitivity analysis not shown in this build._";
Tree-prior sensitivity analysis not shown in this build.
Fit diagnostics by parameter
One parameter or the whole model
Per-parameter diagnostics for every fit
# R-hat and both effective sample sizes over several thousand parameters
# are not free to compute, so each fit's per-parameter frame is built once
# here and handed to every table and figure in this section.
diagnostic_fits = [
    "joint" => chn_joint,
    "joint, no patches" => chn_no_patches,
    "exports" => chn_exports,
    "deaths (DRC)" => chn_deaths,
    "cases (DRC)" => chn_cases,
    "confirmed (DRC)" => chn_confirmed,
    "confirmed deaths (DRC)" => chn_confirmed_deaths,
    "isolation (DRC)" => chn_treatment,
    "onsets (DRC)" => chn_onsets,
    "frozen (1wk back)" => frozen_lastweek.chn,
    (
        RUN_SENSITIVITY ?
            [
                "delay sensitivity" => chn_joint_community_delay,
                "clock sensitivity (ExpGrowth)" => chn_joint_exp_growth_clock,
            ] :
            []
    )...,
]
diagnostic_frames = [
    label => parameter_diagnostics(chn)
        for (label, chn) in diagnostic_fits
]
diagnostic_frame = Dict(diagnostic_frames)
joint_diagnostics = diagnostic_frame["joint"]
diagnostic_spread = MarkdownTable(
    diagnostic_spread_table(diagnostic_frames...; labels = display_names)
);| fit | parameters | rhat_above_1.01 | rhat_above_1.1 | percent_above_1.1 | ess_bulk_below_100 | lowest_ess_parameter |
|---|---|---|---|---|---|---|
| joint | 7391 | 793 | 0 | 0 | 22 | cases_state.positivity |
| joint, no patches | 2080 | 160 | 0 | 0 | 3 | onset_report_state.σ_h0 |
| exports | 294 | 3 | 0 | 0 | 0 | asc_state.τ_logit |
| deaths (DRC) | 509 | 2 | 0 | 0 | 0 | intervention effect |
| cases (DRC) | 513 | 2 | 0 | 0 | 0 | Rt step size |
| confirmed (DRC) | 432 | 1 | 0 | 0 | 0 | growth_state.r |
| confirmed deaths (DRC) | 529 | 3 | 0 | 0 | 0 | admission-to-death scale |
| isolation (DRC) | 346 | 53 | 0 | 0 | 0 | susceptible_fraction |
| onsets (DRC) | 499 | 346 | 1 | 0.2 | 21 | onset_report_state.σ_h0 |
| frozen (1wk back) | 7104 | 5937 | 2734 | 38.5 | 4116 | background_total |
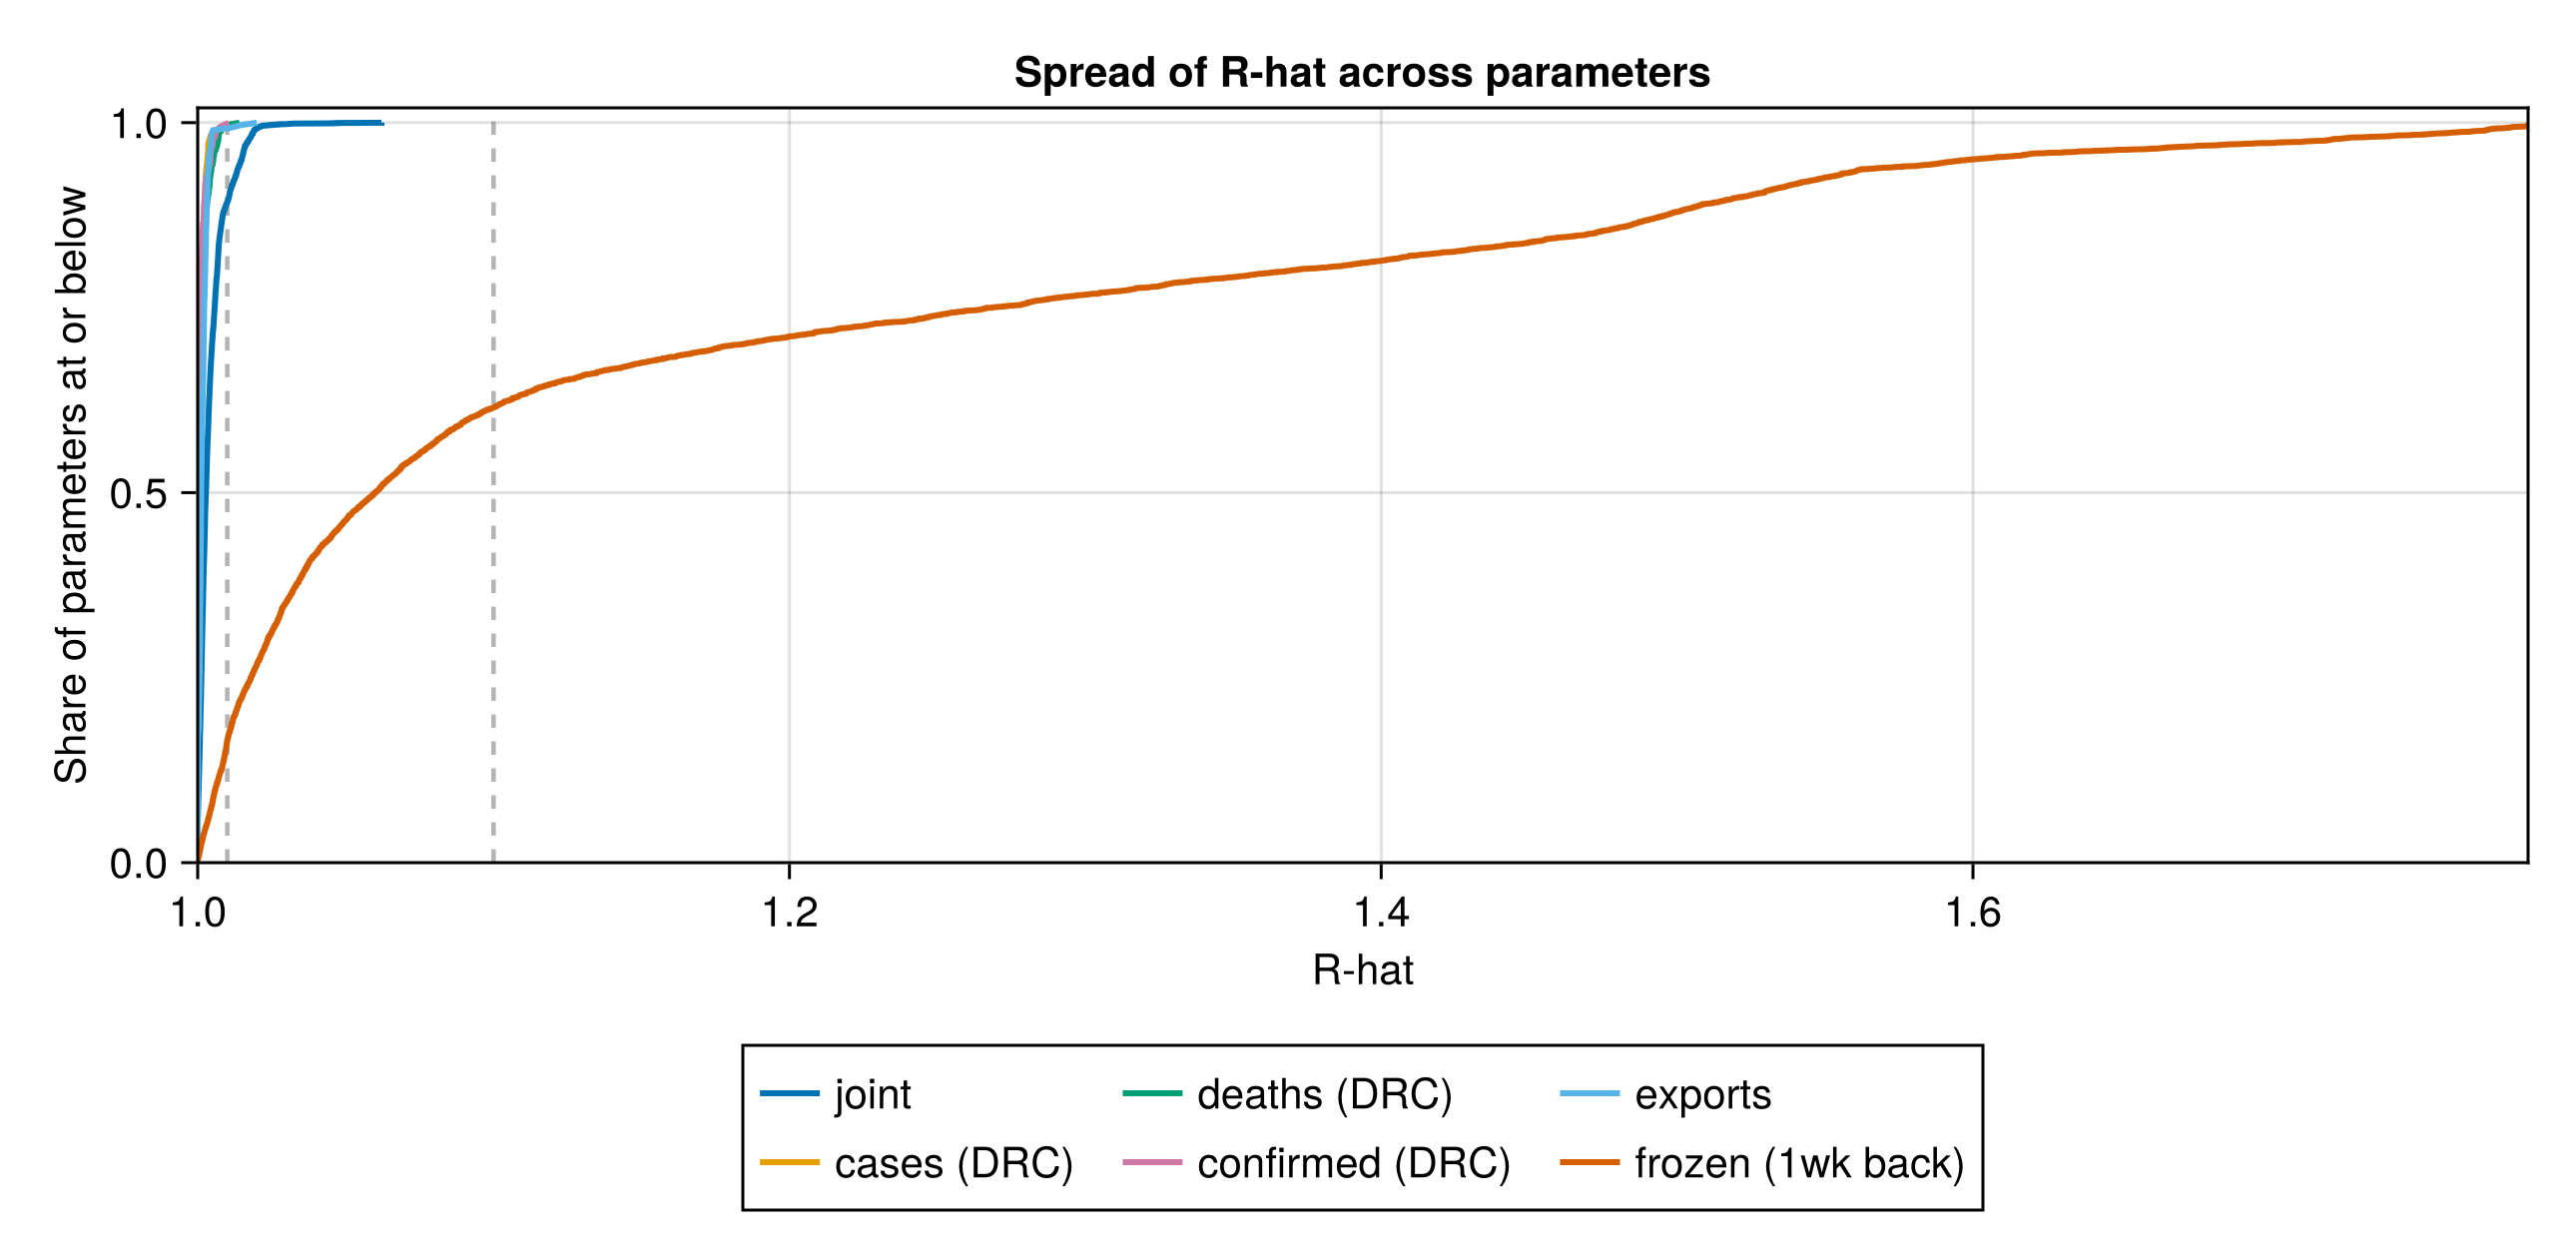
R-hat spread figure
rhat_spread_fig = plot_rhat_spread(
    "joint" => joint_diagnostics,
    "cases (DRC)" => diagnostic_frame["cases (DRC)"],
    "deaths (DRC)" => diagnostic_frame["deaths (DRC)"],
    "confirmed (DRC)" => diagnostic_frame["confirmed (DRC)"],
    "exports" => diagnostic_frame["exports"],
    "frozen (1wk back)" => diagnostic_frame["frozen (1wk back)"]
);
Which parameters mix worst
Worst-mixing parameters of the joint fit
joint_worst_parameters = MarkdownTable(
    worst_parameters_table(
        joint_diagnostics; n = 15,
        labels = display_names
    )
);| parameter | rhat | ess_bulk | ess_tail |
|---|---|---|---|
| cases_state.positivity | 1.062 | 49 | 149 |
| confirmed_state.s_test | 1.056 | 63 | 171 |
| deaths_state.cfr_state.CFR | 1.021 | 74 | 125 |
| treatment_state.sev_state.δ_iso | 1.047 | 76 | 109 |
| recovered_state.rec_state.recovery_offset | 1.021 | 79 | 131 |
| background_total | 1.04 | 79 | 181 |
| treatment_state.isolation_bvd_admission | 1.045 | 84 | 141 |
| treatment_state.recovery_los_state.delay_sd | 1.028 | 86 | 32 |
| onset_report_state.σ_h0 | 1.032 | 89 | 132 |
| treatment_state.β_iso | 1.015 | 89 | 125 |
| CFR_patch[2] | 1.021 | 92 | 201 |
| CFR_patch[4] | 1.011 | 97 | 185 |
| CFR_patch[3] | 1.008 | 97 | 160 |
| asc_state.τ_logit | 1.032 | 98 | 93 |
| CFR_patch[1] | 1.01 | 98 | 162 |
The same diagnostics grouped by parameter rather than by element.
Worst-mixing parameters, grouped
joint_worst_groups = MarkdownTable(
    family_diagnostics_table(
        joint_diagnostics; n = 12,
        labels = display_names
    )
);| parameter | elements | max_rhat | min_ess_bulk | above_1.1 |
|---|---|---|---|---|
| cases_state.positivity | 1 | 1.062 | 49 | 0 |
| confirmed_state.s_test | 1 | 1.056 | 63 | 0 |
| deaths_state.cfr_state.CFR | 1 | 1.021 | 74 | 0 |
| treatment_state.sev_state.δ_iso | 1 | 1.047 | 76 | 0 |
| recovered_state.rec_state.recovery_offset | 1 | 1.021 | 79 | 0 |
| background_total | 1 | 1.04 | 79 | 0 |
| treatment_state.isolation_bvd_admission | 1 | 1.045 | 84 | 0 |
| treatment_state.recovery_los_state.delay_sd | 1 | 1.028 | 86 | 0 |
| onset_report_state.σ_h0 | 1 | 1.032 | 89 | 0 |
| treatment_state.β_iso | 1 | 1.015 | 89 | 0 |
| CFR_patch | 4 | 1.021 | 92 | 0 |
| asc_state.τ_logit | 1 | 1.032 | 98 | 0 |
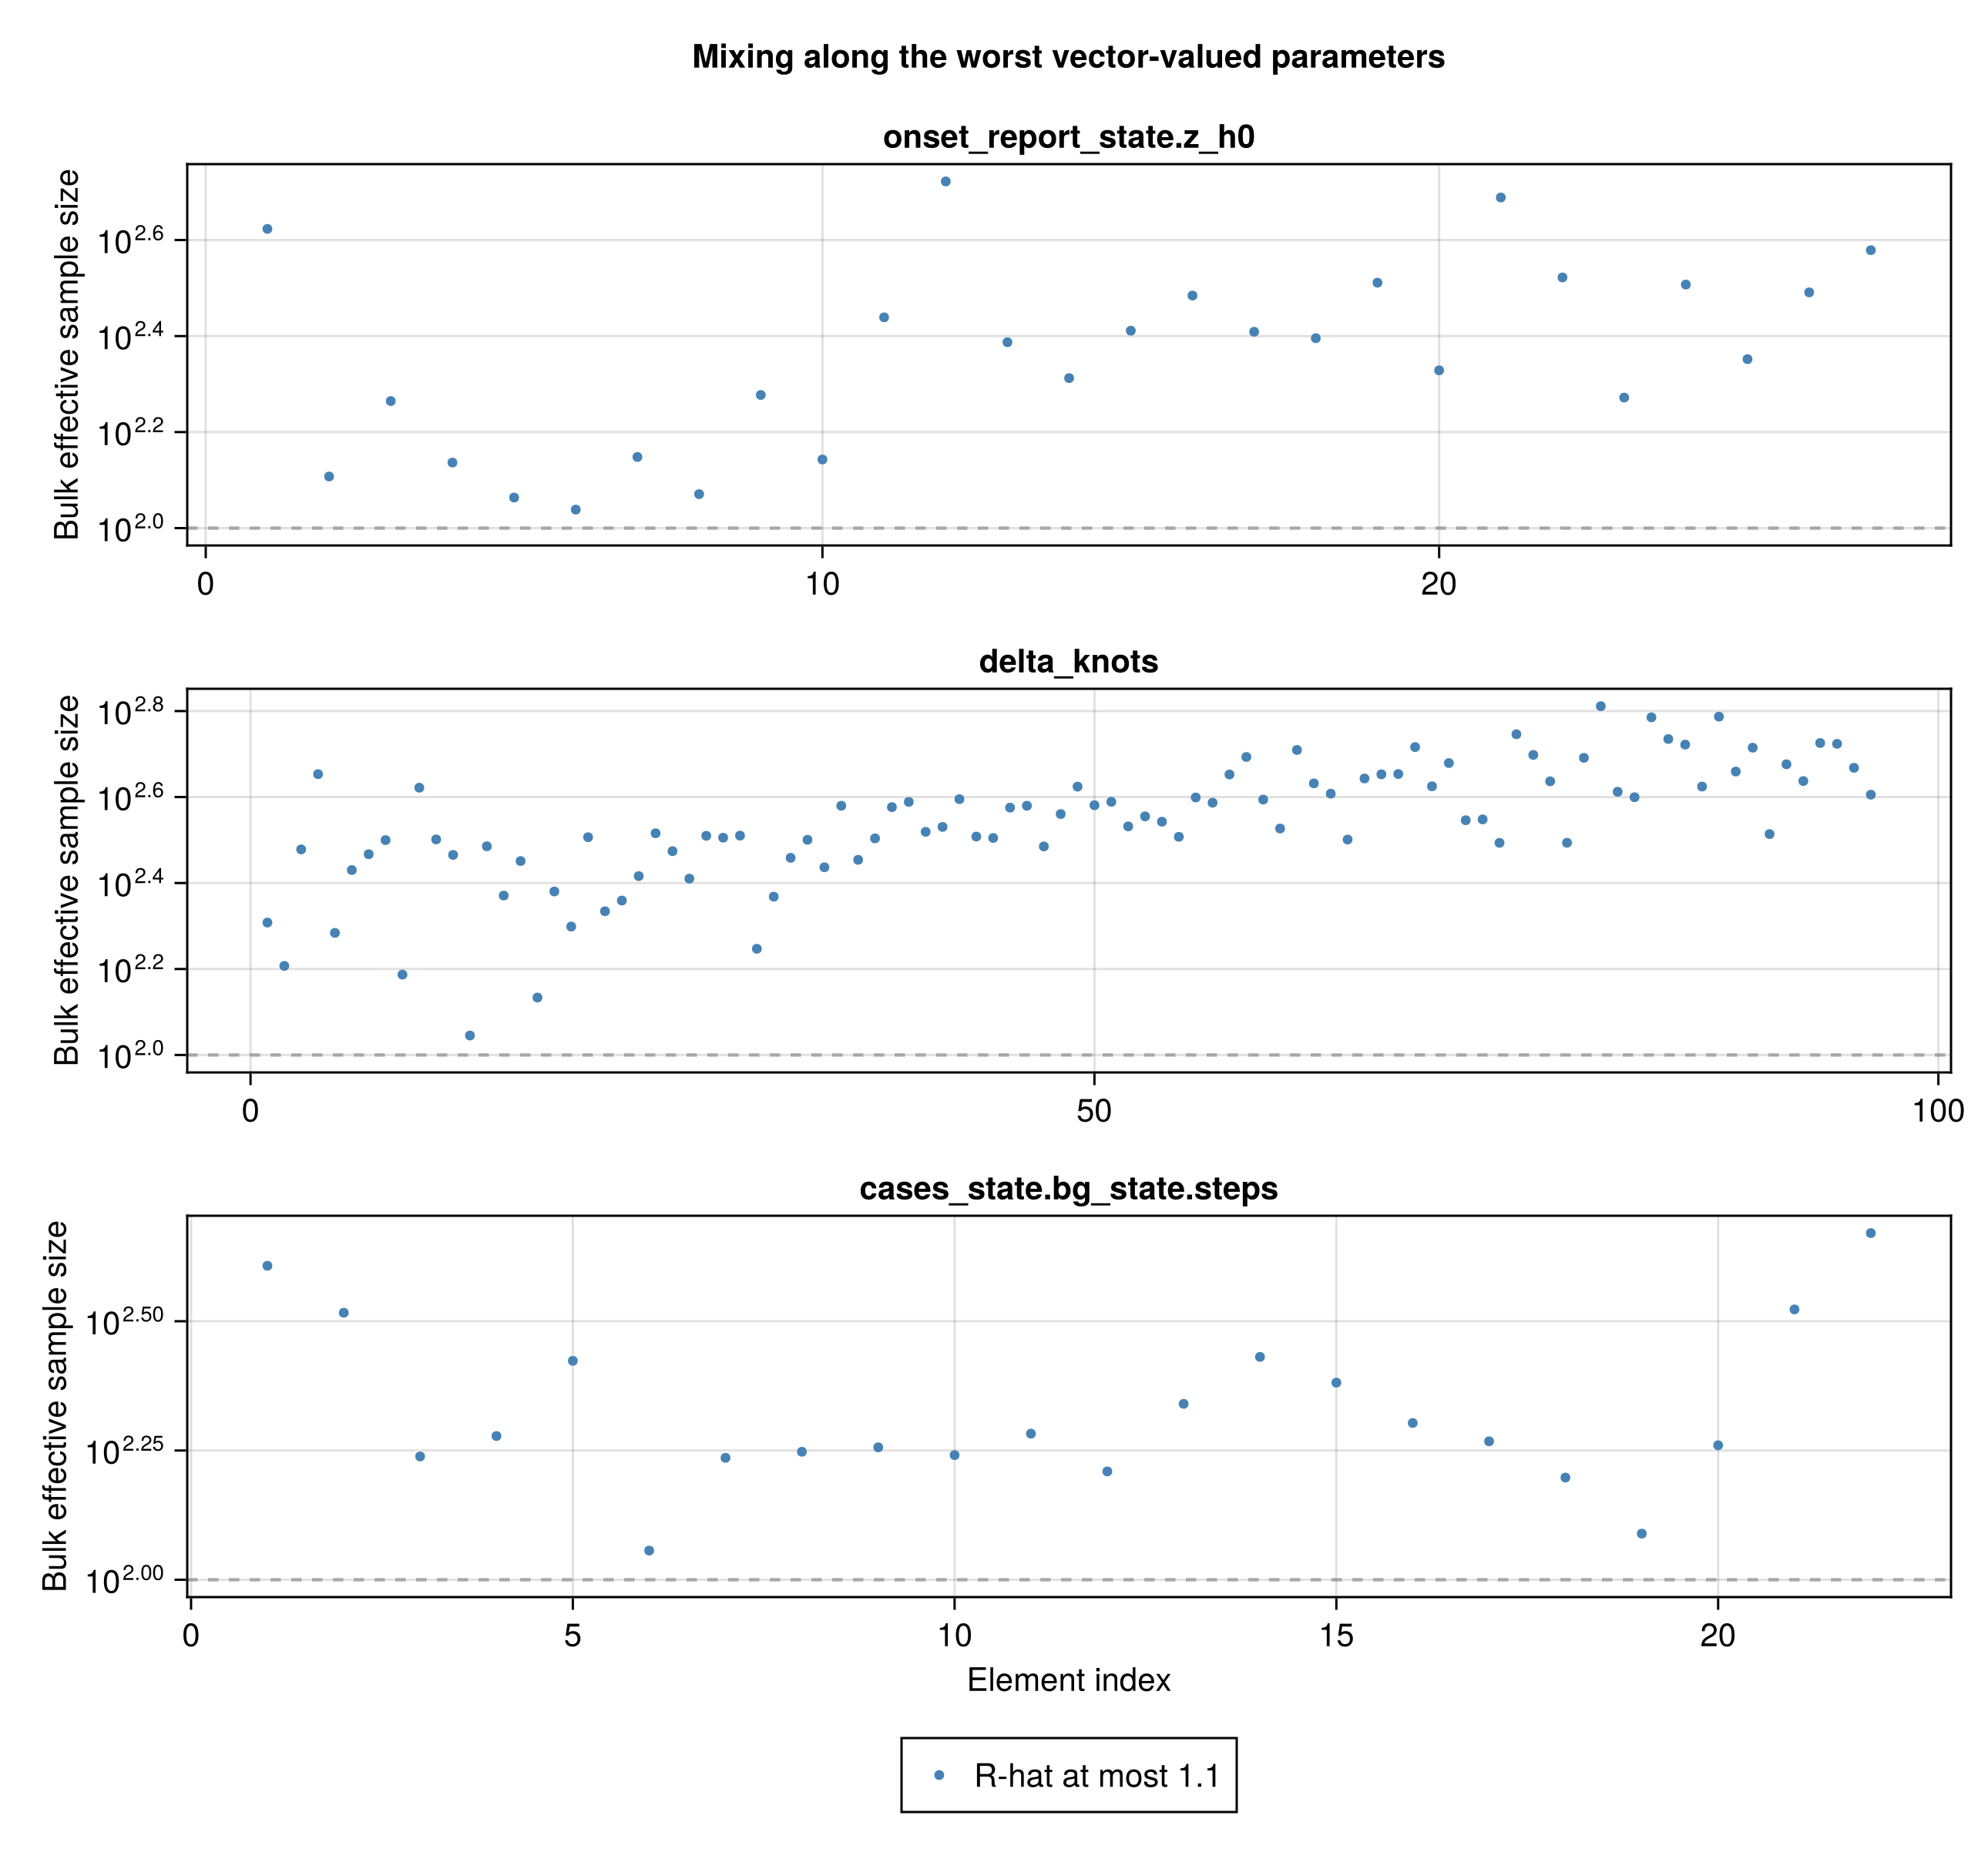
Mixing over time varying paramters
joint_index_fig = plot_parameter_index_diagnostics(
    joint_diagnostics;
    n_groups = 3, labels = display_names
);
Where the divergent transitions sit
Sampler behaviour by chain
joint_chain_table = MarkdownTable(sampler_by_chain_table(chn_joint));| chain | draws | divergences | percent_divergent | step_size | deepest_tree |
|---|---|---|---|---|---|
| 1 | 1000 | 1 | 0.1 | 0.0017 | 10 |
| 2 | 1000 | 1 | 0.1 | 0.00152 | 10 |
Divergence location table
joint_divergence_table = MarkdownTable(
    divergence_location_table(chn_joint; n = 12, labels = display_names)
);| parameter | all_draws | divergent_draws | separation |
|---|---|---|---|
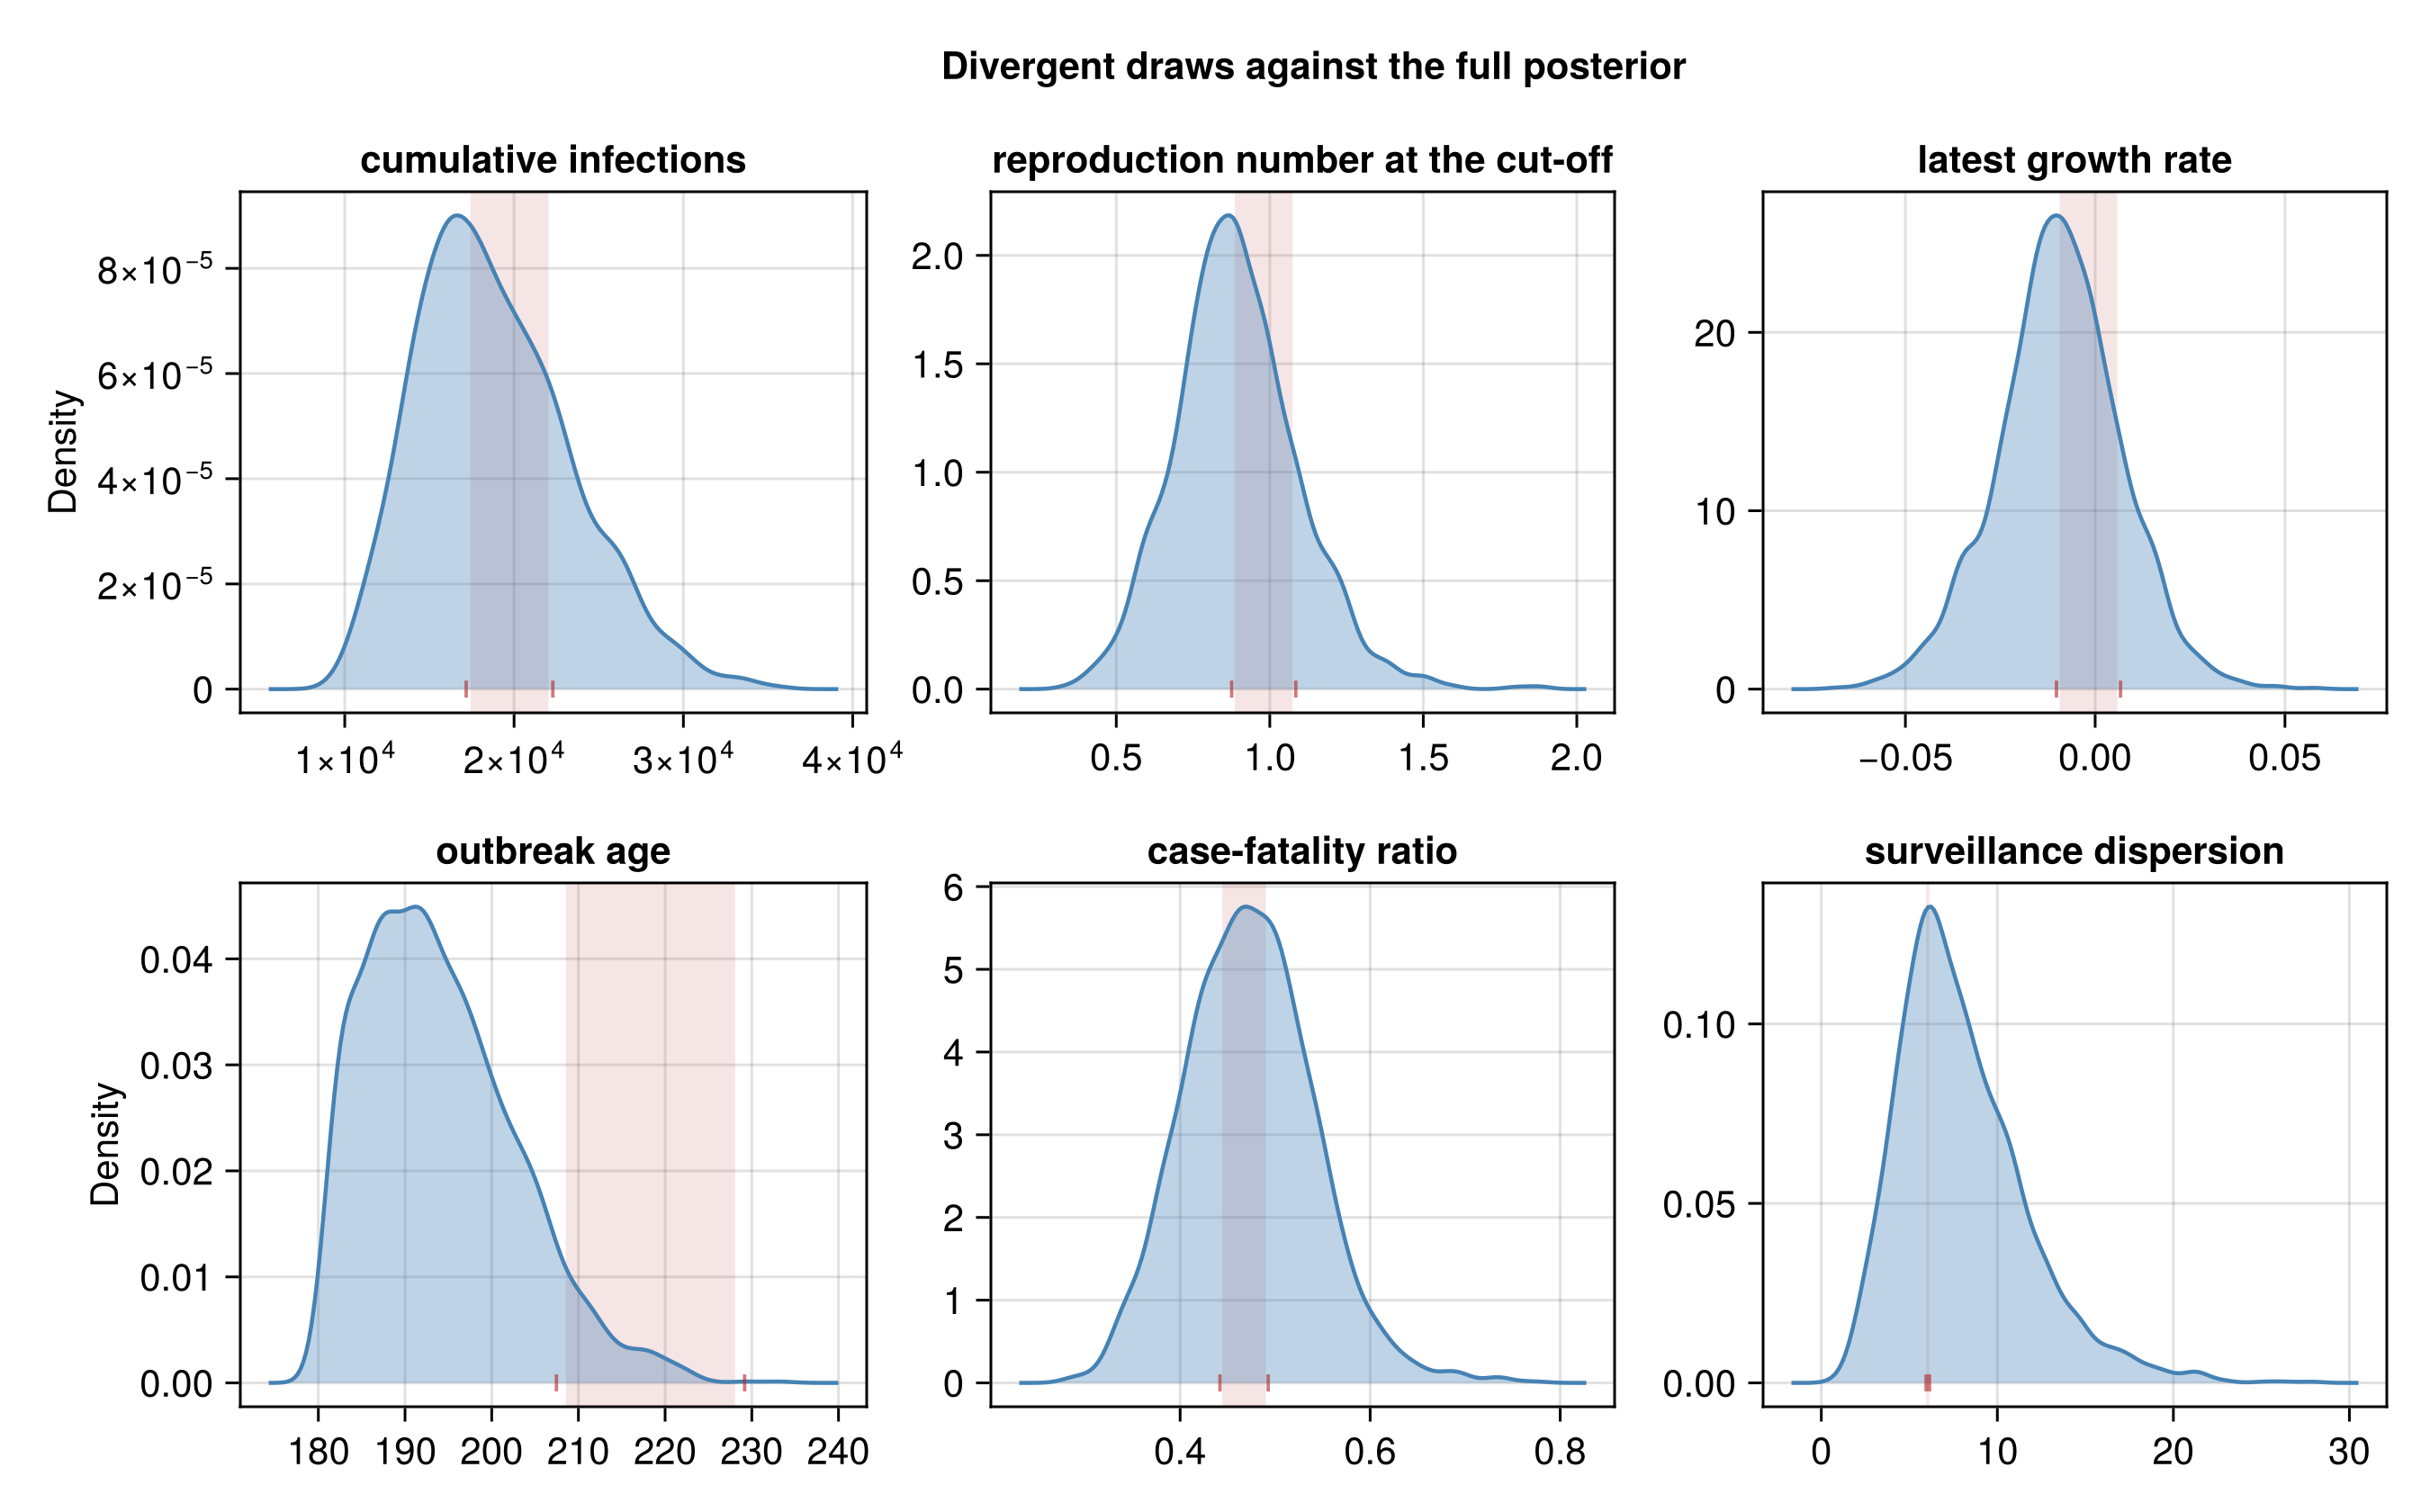
| growth_state.m | 0.099–2.21 | 2.19–3.79 | 3.14 |
| growth_state.T | 1.32–29.1 | 27.6–47.1 | 2.94 |
| T | 182.0–210.0 | 209.0–228.0 | 2.94 |
| growth_state.τ | 8.09–20.1 | 17.5–29.6 | 2.92 |
| Rt step size | 0.0681–0.237 | 0.211–0.304 | 2.2 |
| expected_onset_reported_T | 5740.0–6060.0 | 6030.0–6130.0 | 1.92 |
| deaths_state.asc_state.p_death | 0.798–0.953 | 0.729–0.891 | -1.72 |
| confirmed_state.ρ | 0.0368–0.0594 | 0.0542–0.0605 | 1.54 |
| rt_state.log_R0 | 0.407–0.944 | 0.276–0.454 | -1.53 |
| growth_state.r | 0.0345–0.0857 | 0.0238–0.0403 | -1.43 |
| recovered_state.delay_state.delay_sd | 2.01–12.6 | 11.0–12.1 | 1.35 |
| admission-to-death shape | 1.26–2.97 | 2.43–3.22 | 1.34 |
Divergent draws against the posterior
joint_divergence_fig = plot_divergence_locations(
    chn_joint,
    [:C_T, :R_T, :r, :T, :CFR, :k];
    labels = Dict(
        :C_T => "cumulative infections",
        :R_T => "reproduction number at the cut-off",
        :r => "latest growth rate", :T => "outbreak age",
        :CFR => "case-fatality ratio",
        :k => "surveillance dispersion"
    )
);
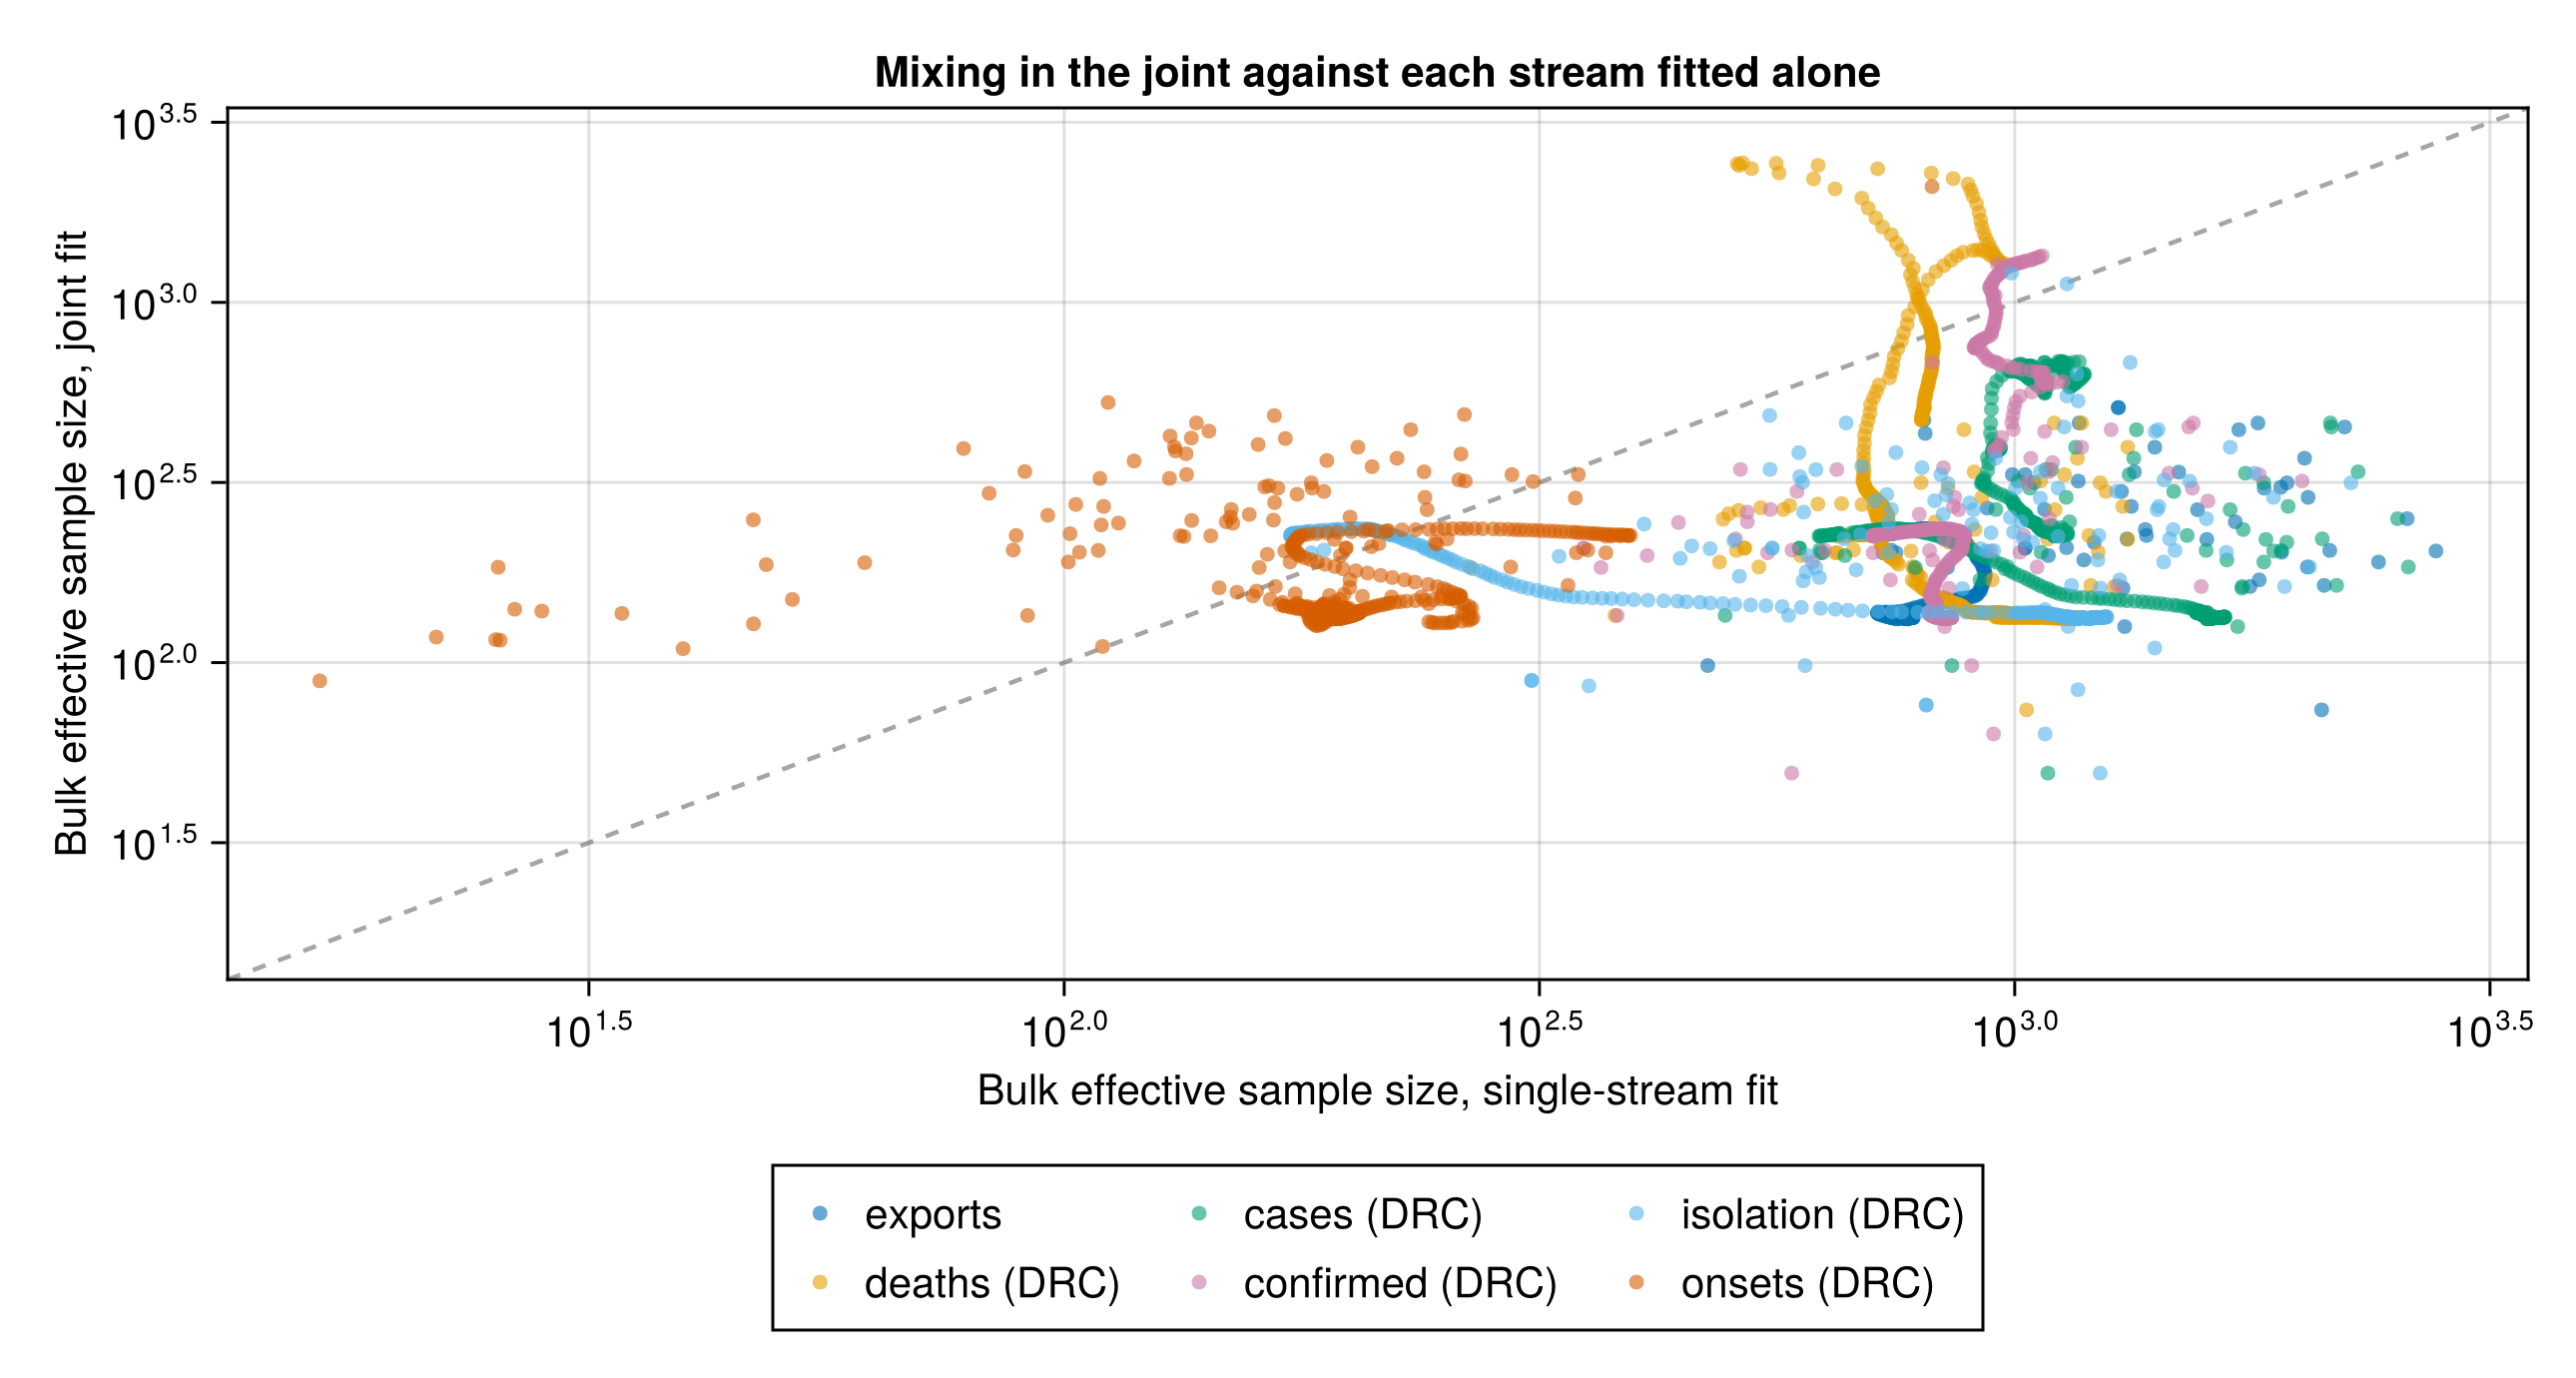
The joint fit against the single-stream fits
Joint against single-stream contrast
stream_contrast = diagnostic_contrast(
    "joint" => joint_diagnostics,
    "exports" => diagnostic_frame["exports"],
    "deaths (DRC)" => diagnostic_frame["deaths (DRC)"],
    "cases (DRC)" => diagnostic_frame["cases (DRC)"],
    "confirmed (DRC)" => diagnostic_frame["confirmed (DRC)"],
    "isolation (DRC)" => diagnostic_frame["isolation (DRC)"],
    "onsets (DRC)" => diagnostic_frame["onsets (DRC)"]
)
stream_contrast_table = MarkdownTable(
    diagnostic_contrast_table(
        stream_contrast; n = 15,
        labels = display_names
    )
);| fit | parameter | ess_bulk | ess_bulk_reference | ess_ratio |
|---|---|---|---|---|
| exports | deaths_state.cfr_state.CFR | 2103 | 74 | 0.04 |
| isolation (DRC) | cases_state.positivity | 1230 | 49 | 0.04 |
| cases (DRC) | cases_state.positivity | 1084 | 49 | 0.05 |
| isolation (DRC) | confirmed_state.s_test | 1077 | 63 | 0.06 |
| confirmed (DRC) | confirmed_state.s_test | 950 | 63 | 0.07 |
| cases (DRC) | rt_state.z[9] | 2595 | 184 | 0.07 |
| deaths (DRC) | deaths_state.cfr_state.CFR | 1029 | 74 | 0.07 |
| isolation (DRC) | treatment_state.isolation_bvd_admission | 1166 | 84 | 0.07 |
| cases (DRC) | asc_state.p_drc | 1716 | 126 | 0.07 |
| exports | rt_state.z[13] | 2774 | 204 | 0.07 |
| cases (DRC) | rt_state.z[7] | 2181 | 164 | 0.08 |
| exports | rt_state.z[7] | 2116 | 164 | 0.08 |
| isolation (DRC) | treatment_state.adm_state.p_iso | 1404 | 110 | 0.08 |
| exports | generation interval mean | 2414 | 190 | 0.08 |
| cases (DRC) | susceptible_fraction[225] | 1664 | 134 | 0.08 |
Joint against single-stream figure
stream_contrast_fig = plot_diagnostic_contrast(
    stream_contrast;
    xlabel = "Bulk effective sample size, single-stream fit",
    ylabel = "Bulk effective sample size, joint fit",
    title = "Mixing in the joint against each stream fitted alone"
);
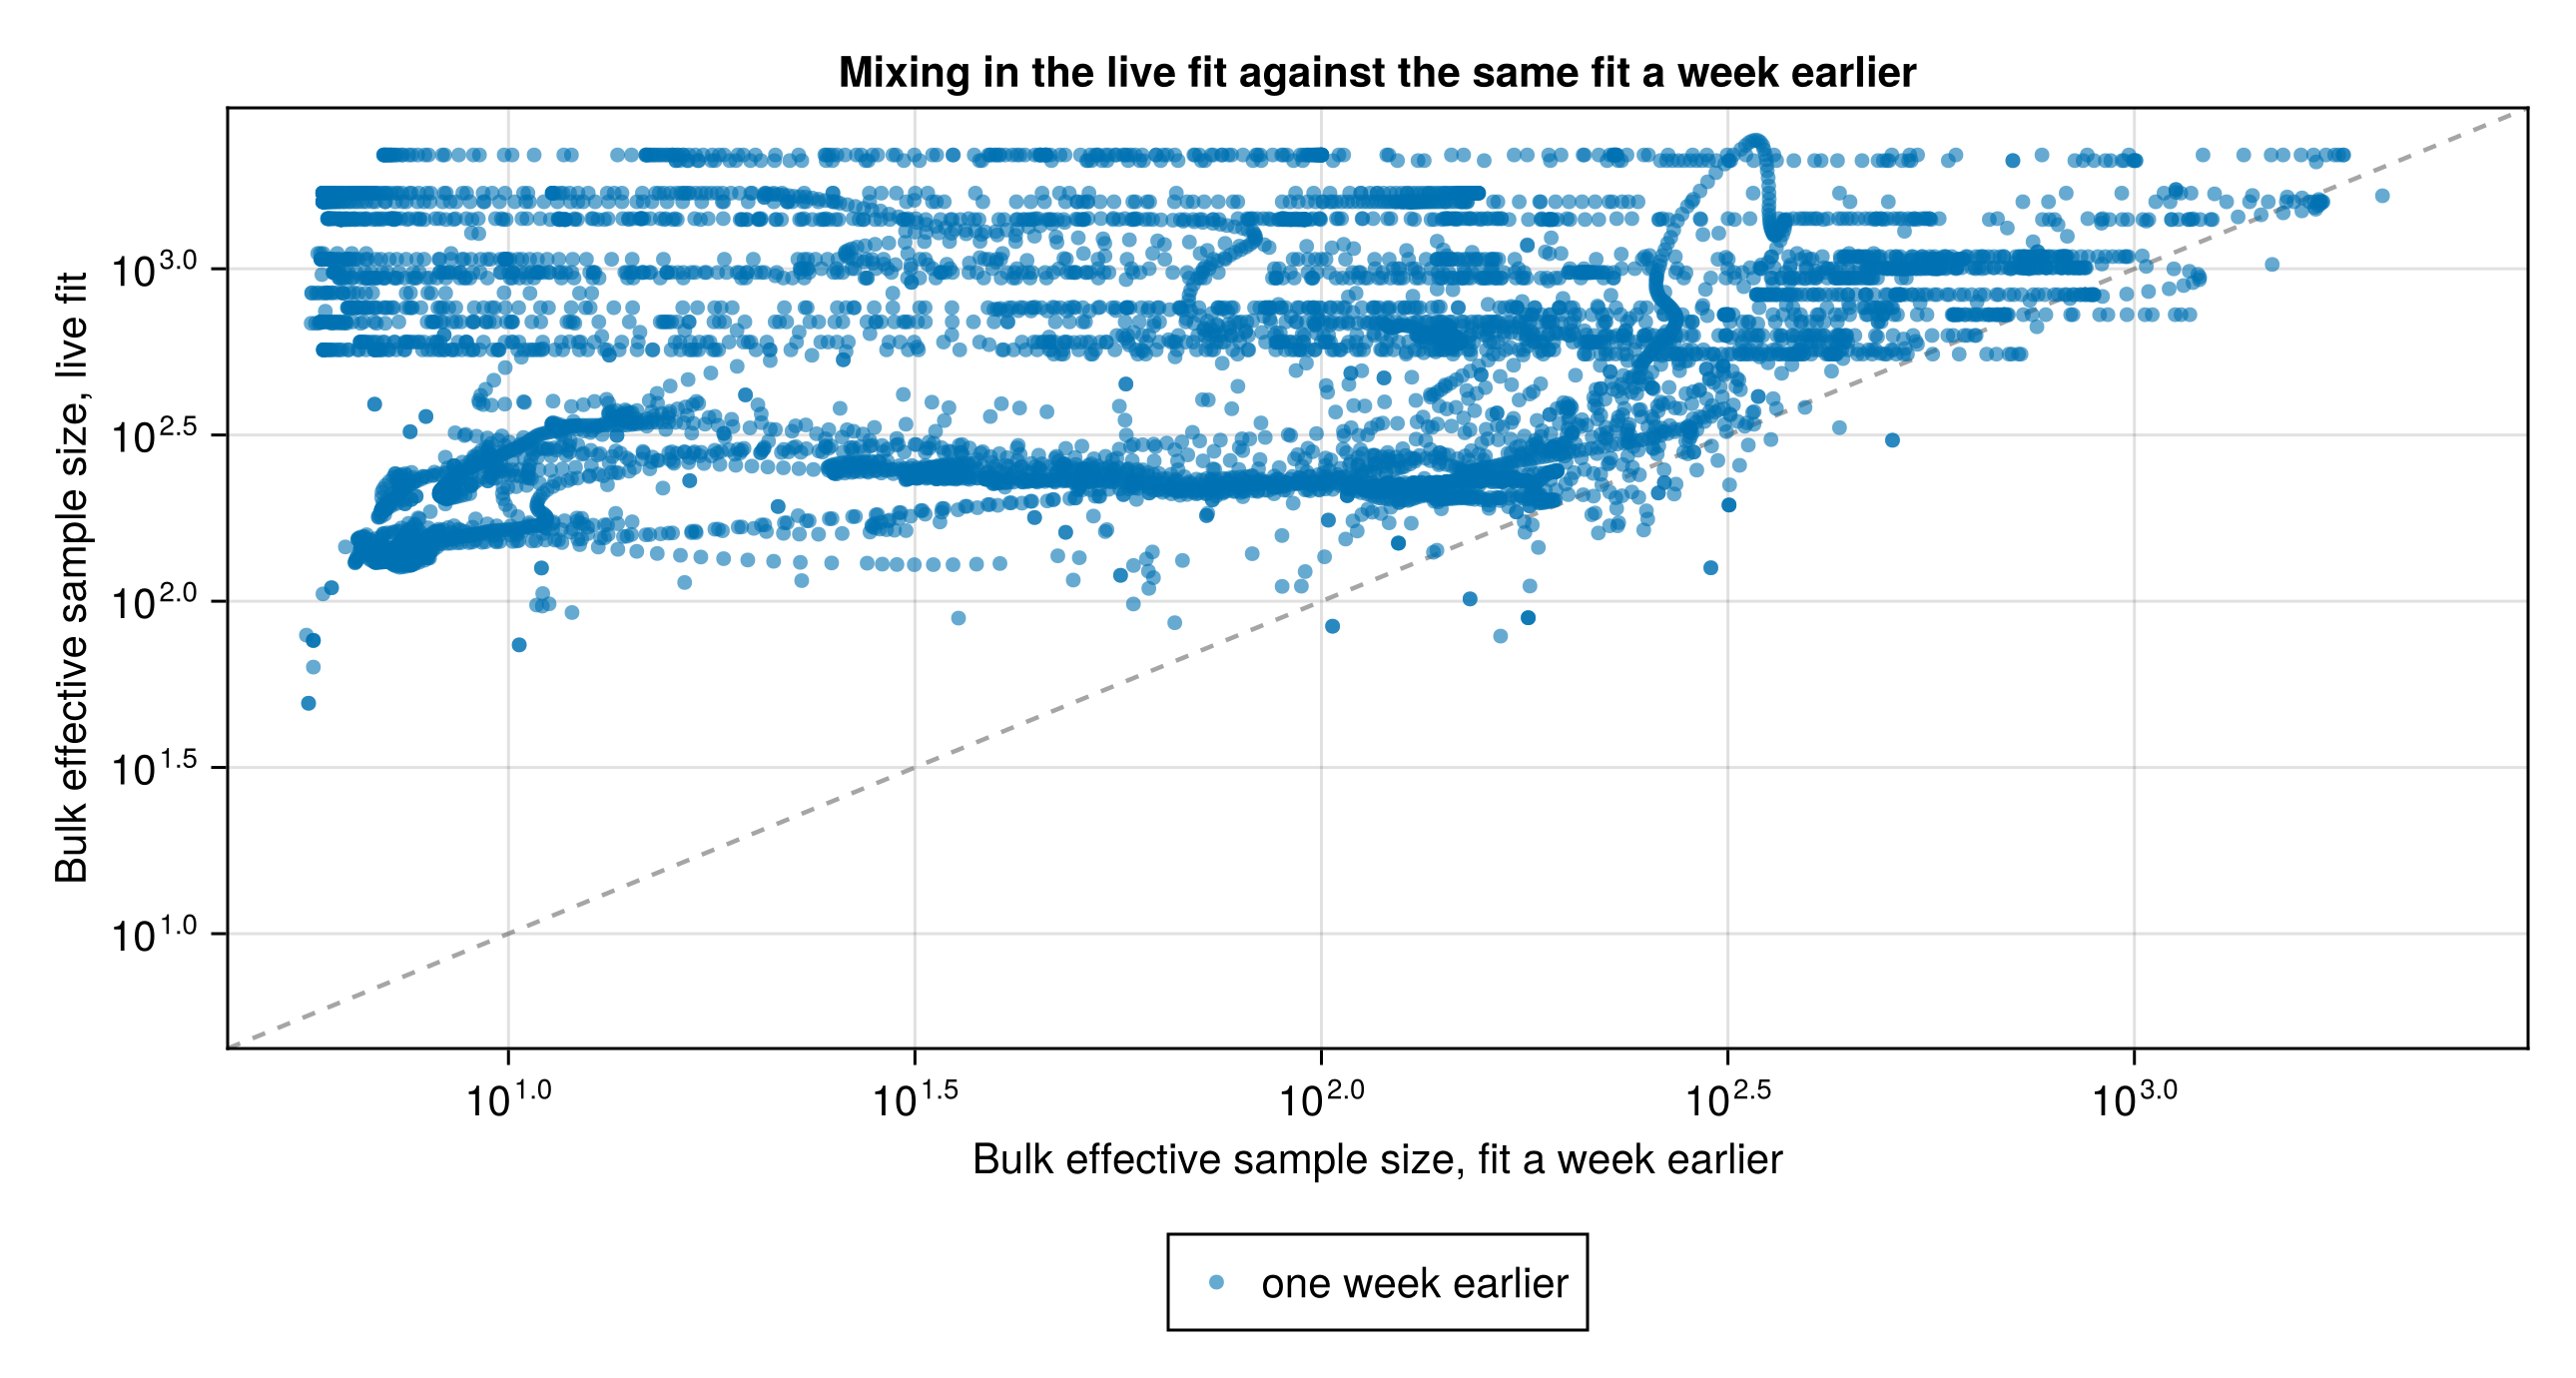
The joint fit against the same fit a week earlier
Live against frozen contrast
frozen_contrast = diagnostic_contrast(
    "joint" => joint_diagnostics,
    "one week earlier" => diagnostic_frame["frozen (1wk back)"]
)
frozen_contrast_table = MarkdownTable(
    diagnostic_contrast_table(
        frozen_contrast; n = 15,
        labels = display_names
    )
);| fit | parameter | ess_bulk | ess_bulk_reference | ess_ratio |
|---|---|---|---|---|
| one week earlier | σ_ε | 301 | 126 | 0.42 |
| one week earlier | recovered_state.rec_state.recovery_offset | 166 | 79 | 0.47 |
| one week earlier | treatment_state.β_iso | 180 | 89 | 0.5 |
| one week earlier | treatment_state.expected_bed_demand | 504 | 305 | 0.61 |
| one week earlier | treatment_state.incare_confirm_log | 317 | 195 | 0.61 |
| one week earlier | bg_split_state.z_bg[2] | 180 | 111 | 0.62 |
| one week earlier | province_shares[4] | 1170 | 728 | 0.62 |
| one week earlier | province_shares[4] | 1141 | 728 | 0.64 |
| one week earlier | province_shares[4] | 1122 | 728 | 0.65 |
| one week earlier | rt_state.z[7] | 249 | 164 | 0.66 |
| one week earlier | bg_split_state.τ_bg | 152 | 102 | 0.67 |
| one week earlier | province_shares[4] | 1052 | 728 | 0.69 |
| one week earlier | province_bed_capacity[1] | 1477 | 1031 | 0.7 |
| one week earlier | delta_knots[30] | 252 | 177 | 0.7 |
| one week earlier | onset_report_state.z_a[2] | 318 | 224 | 0.7 |
Live against frozen figure
frozen_contrast_fig = plot_diagnostic_contrast(
    frozen_contrast;
    xlabel = "Bulk effective sample size, fit a week earlier",
    ylabel = "Bulk effective sample size, live fit",
    title = "Mixing in the live fit against the same fit a week earlier"
);
By province
Spatial structure sensitivity
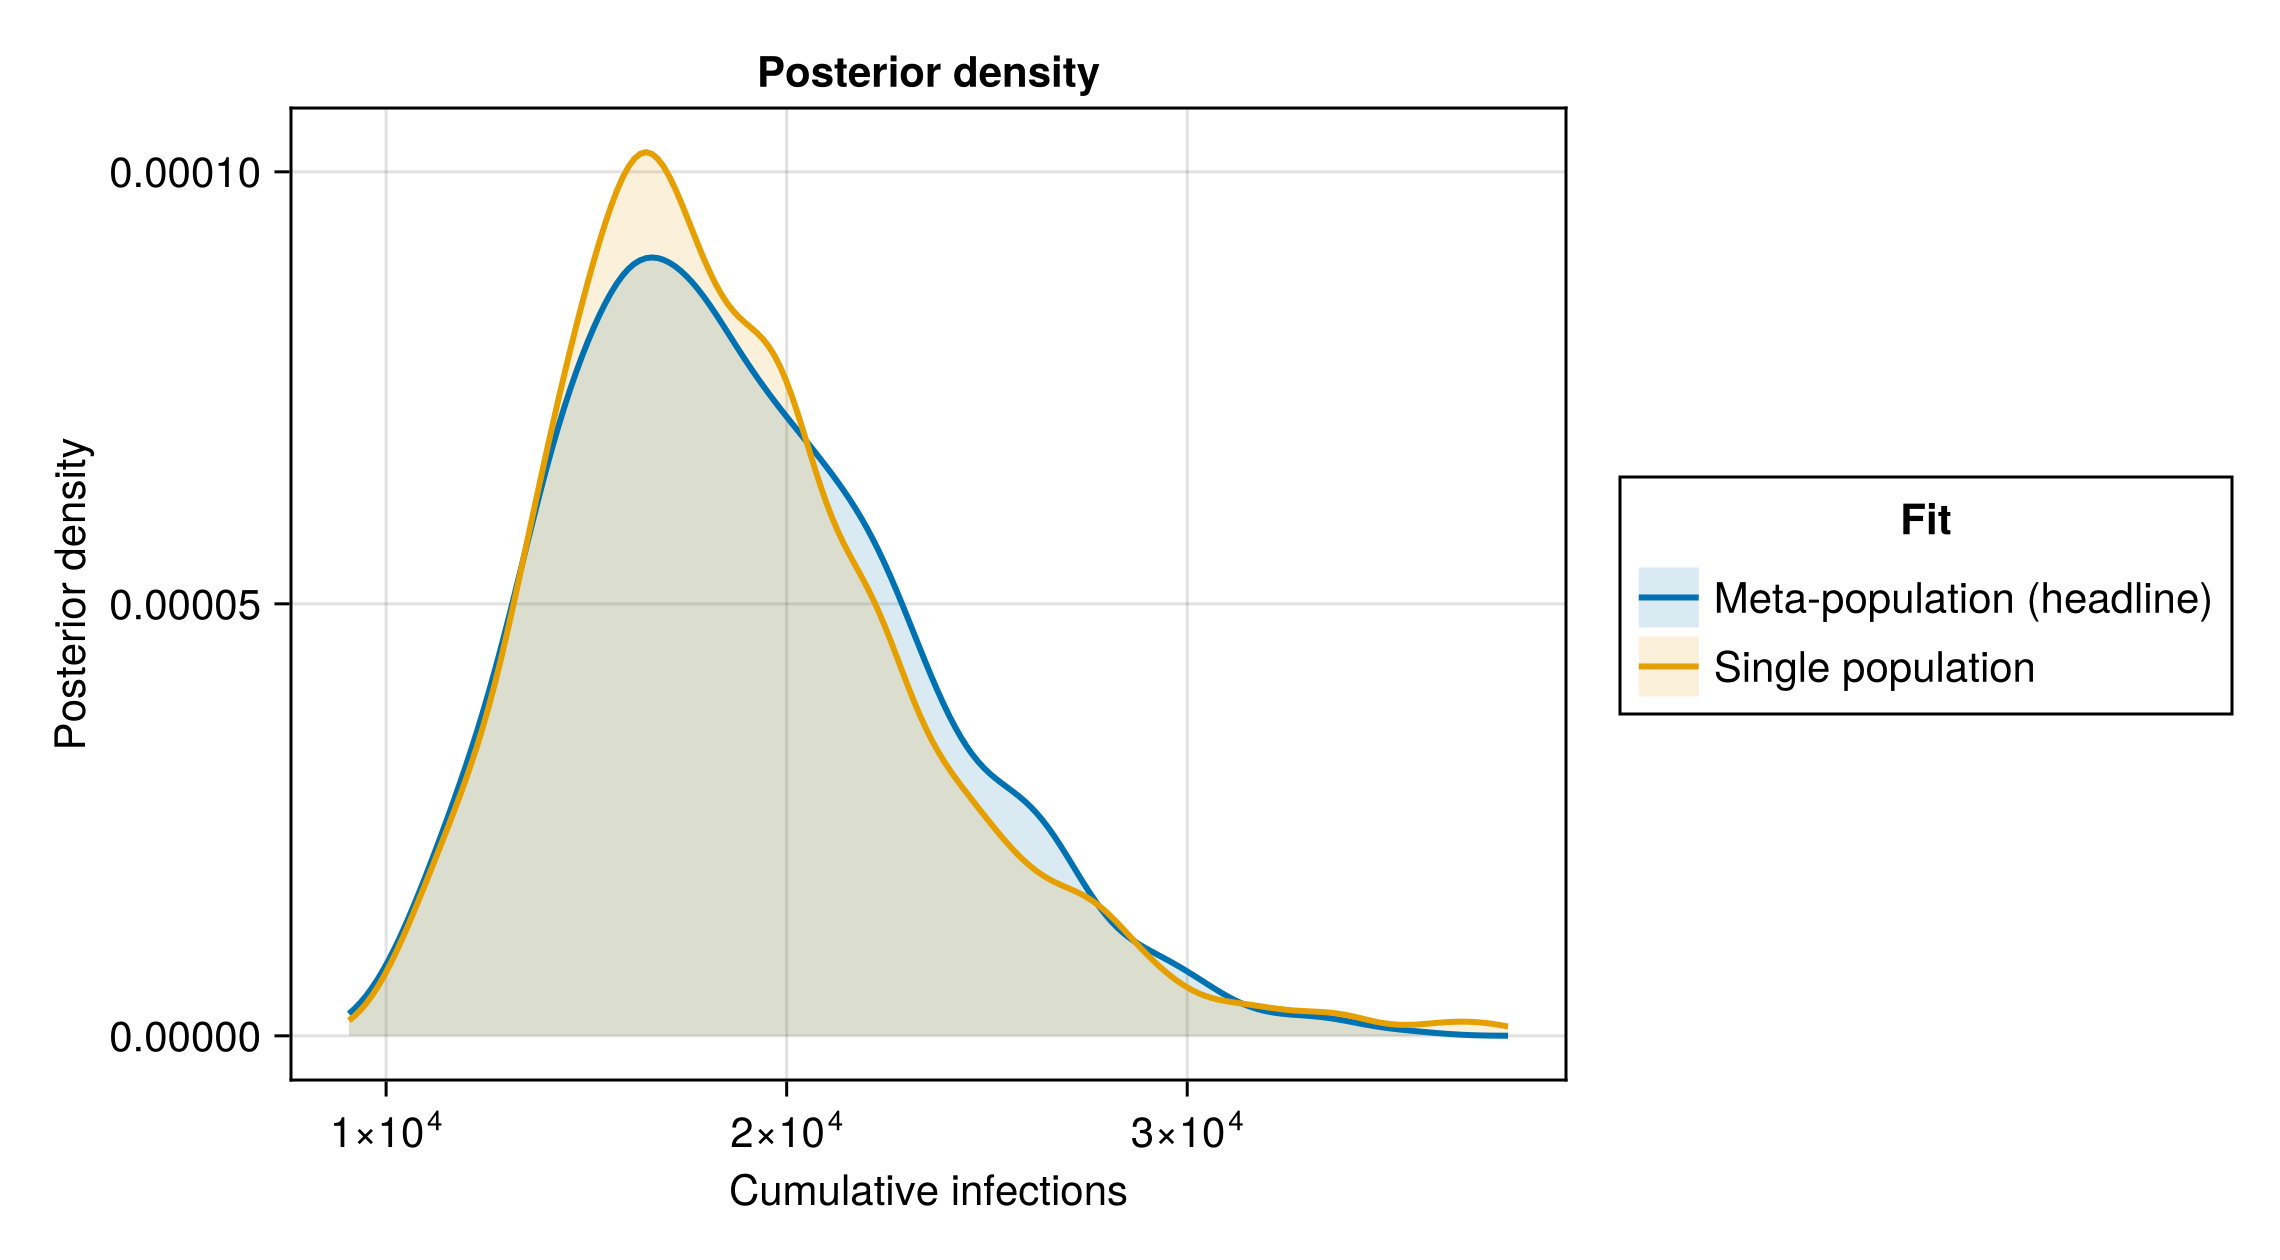
The headline runs the model over four patches, one each for Ituri, Nord-Kivu and Haut-Uele and a fourth pooling the other affected provinces. Reducing it to a single patch collapses it onto one well-mixed population, which is the model the earlier releases used. The model overview on the methods page describes what the provinces add.
Splitting the country into provinces adds no national data, so the national outbreak size should not move far either way. The two are not identical by construction: the provinces run free and the country grows at the force-weighted mean of their reproduction numbers, which sits above the central trend they pool toward. That gap is first order in the deviation scale. A large gap between the two posteriors below would therefore point at the deviation priors rather than at the data.
spatial_sensitivity_table = streams_table(
    "Meta-population (headline)" => posterior_C_joint,
    "Single population (n_patches = 1)" => posterior_C_no_patches
);
spatial_sensitivity_table| Row | Stream | Lower 90% | Lower 60% | Lower 30% | Upper 30% | Upper 60% | Upper 90% |
|---|---|---|---|---|---|---|---|
| String | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | |
| 1 | Meta-population (headline) | 12343.0 | 14887.0 | 16593.0 | 20232.0 | 22555.0 | 27006.0 |
| 2 | Single population (n_patches = 1) | 12399.0 | 14926.0 | 16421.0 | 19763.0 | 22039.0 | 27415.0 |
Spatial-structure density overlay
spatial_sensitivity_fig = plot_density_overlay(
    "Meta-population (headline)" => posterior_C_joint,
    "Single population" => posterior_C_no_patches;
    xlabel = "Cumulative infections"
);
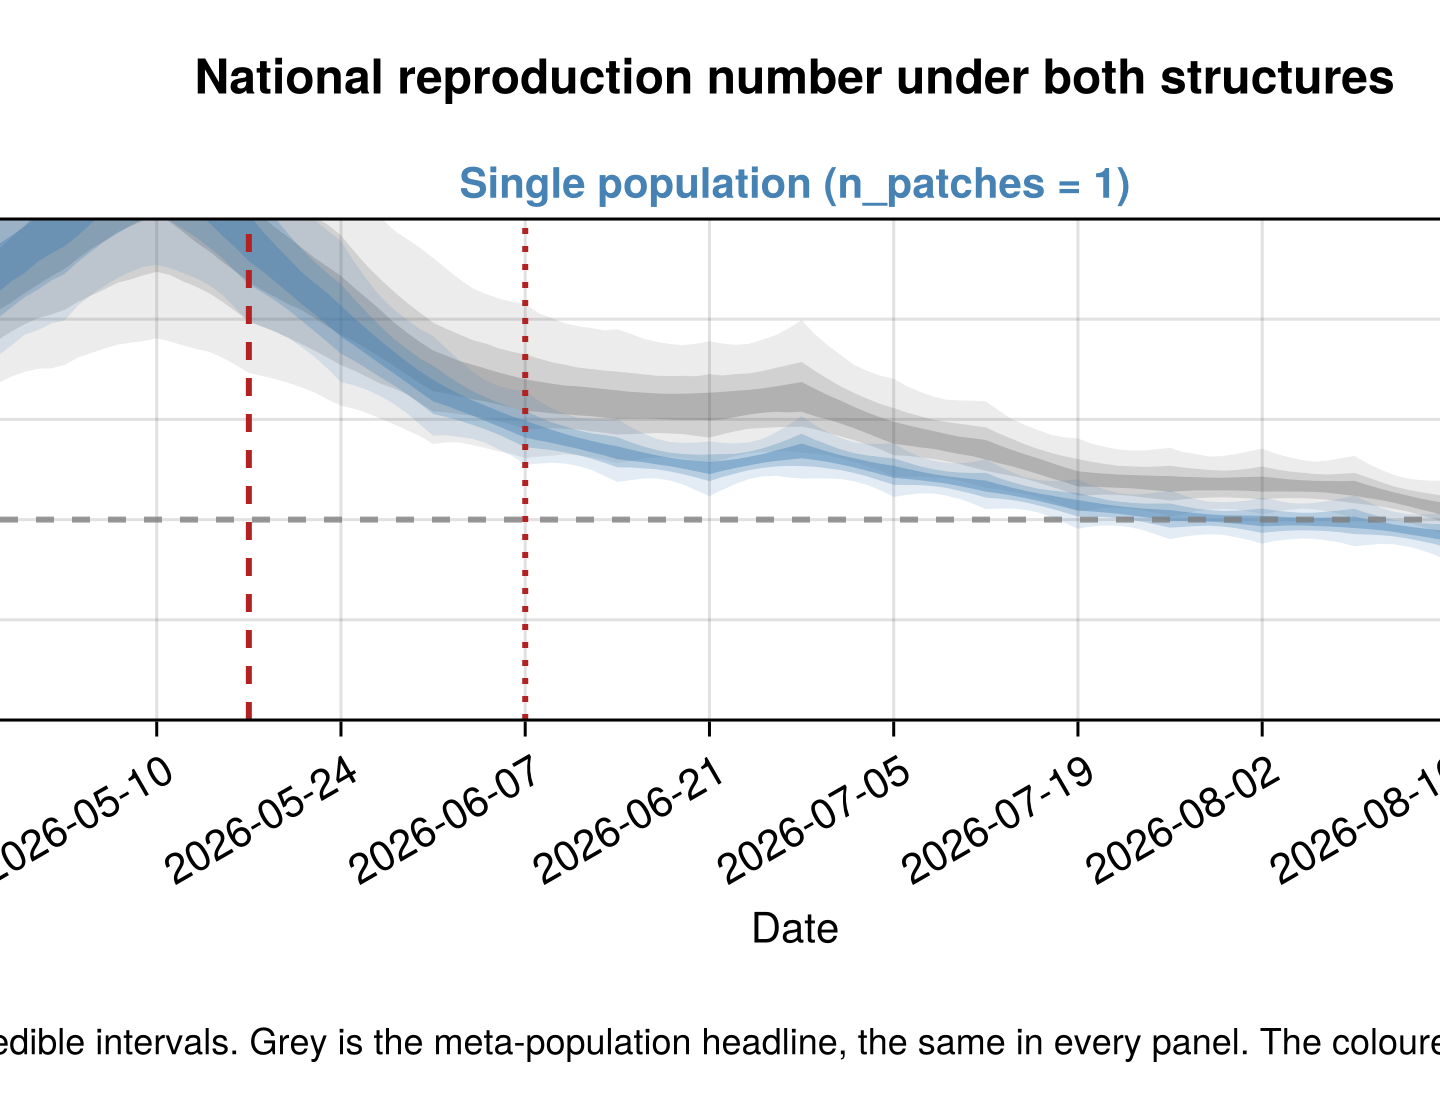
The size is the gate, but it is not the only quantity the spatial structure could move. The three figures below set the national reproduction number, the case-fatality ratio and the reproduction number at the cut-off from the two fits against each other. Each is a national quantity that both models estimate, so the two posteriors should sit on top of each other. In the trajectory figure they do, closely enough that the grey reference is hidden behind the coloured band for most of the window. The table after them gives the same quantities as numbers, which is where the agreement is read rather than eyeballed.
National quantities under both structures
spatial_rt_fig = plot_rt_streams(
    [
        (;
            label = "Single population (n_patches = 1)",
            chn = chn_no_patches, rt_start = _rt_start_plot,
            rt_walk_start = clamp(
                _BREAKPOINT - RT_WALK_LEAD, _rt_start_plot,
                obs.n
            ), colour = :steelblue,
        ),
    ];
    joint = (;
        chn = chn_joint, rt_start = _rt_start_plot,
        rt_walk_start = clamp(
            _BREAKPOINT - RT_WALK_LEAD, _rt_start_plot,
            obs.n
        ),
    ),
    n = obs.n, breakpoint = _BREAKPOINT,
    as_of_date = string(obs.cutoff), seeding = obs.seeding,
    display_start = _rt_start_plot, ncols = 1,
    title = "National reproduction number under both structures",
    reference_label = "the meta-population headline",
    panel_label = "the single-population fit"
);

spatial_cfr_fig = plot_density_overlay(
    "Meta-population (headline)" => vec(Array(chn_joint[:CFR])),
    "Single population" => vec(Array(chn_no_patches[:CFR]));
    xlabel = "Case-fatality ratio"
);

spatial_rt_density_fig = plot_density_overlay(
    "Meta-population (headline)" => vec(Array(chn_joint[:R_T])),
    "Single population" => vec(Array(chn_no_patches[:R_T]));
    xlabel = "Reproduction number at the cut-off"
);
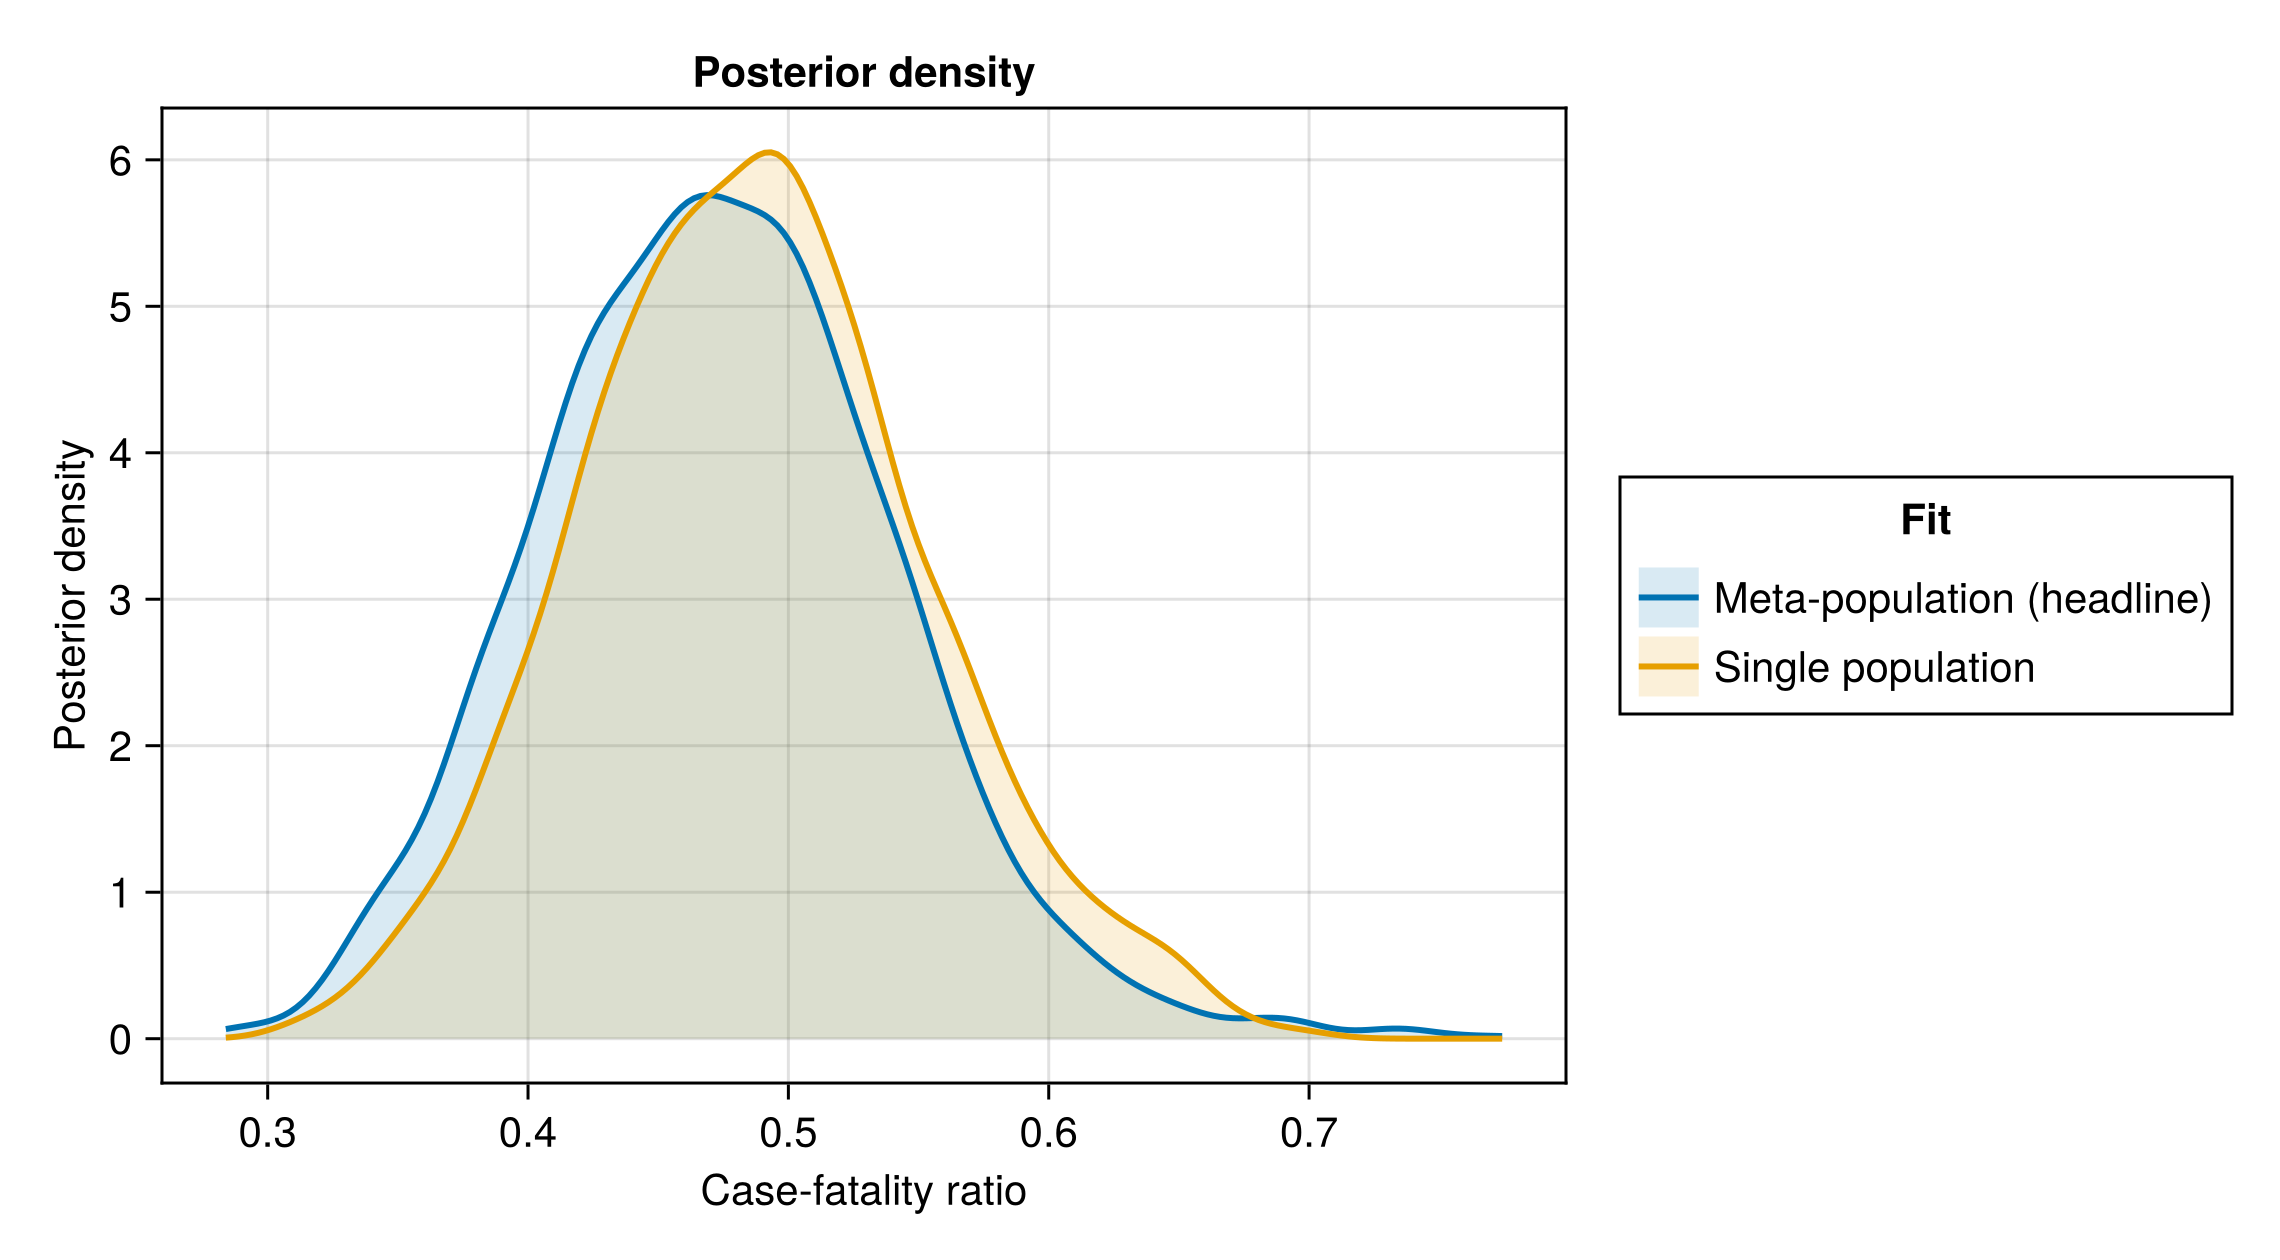
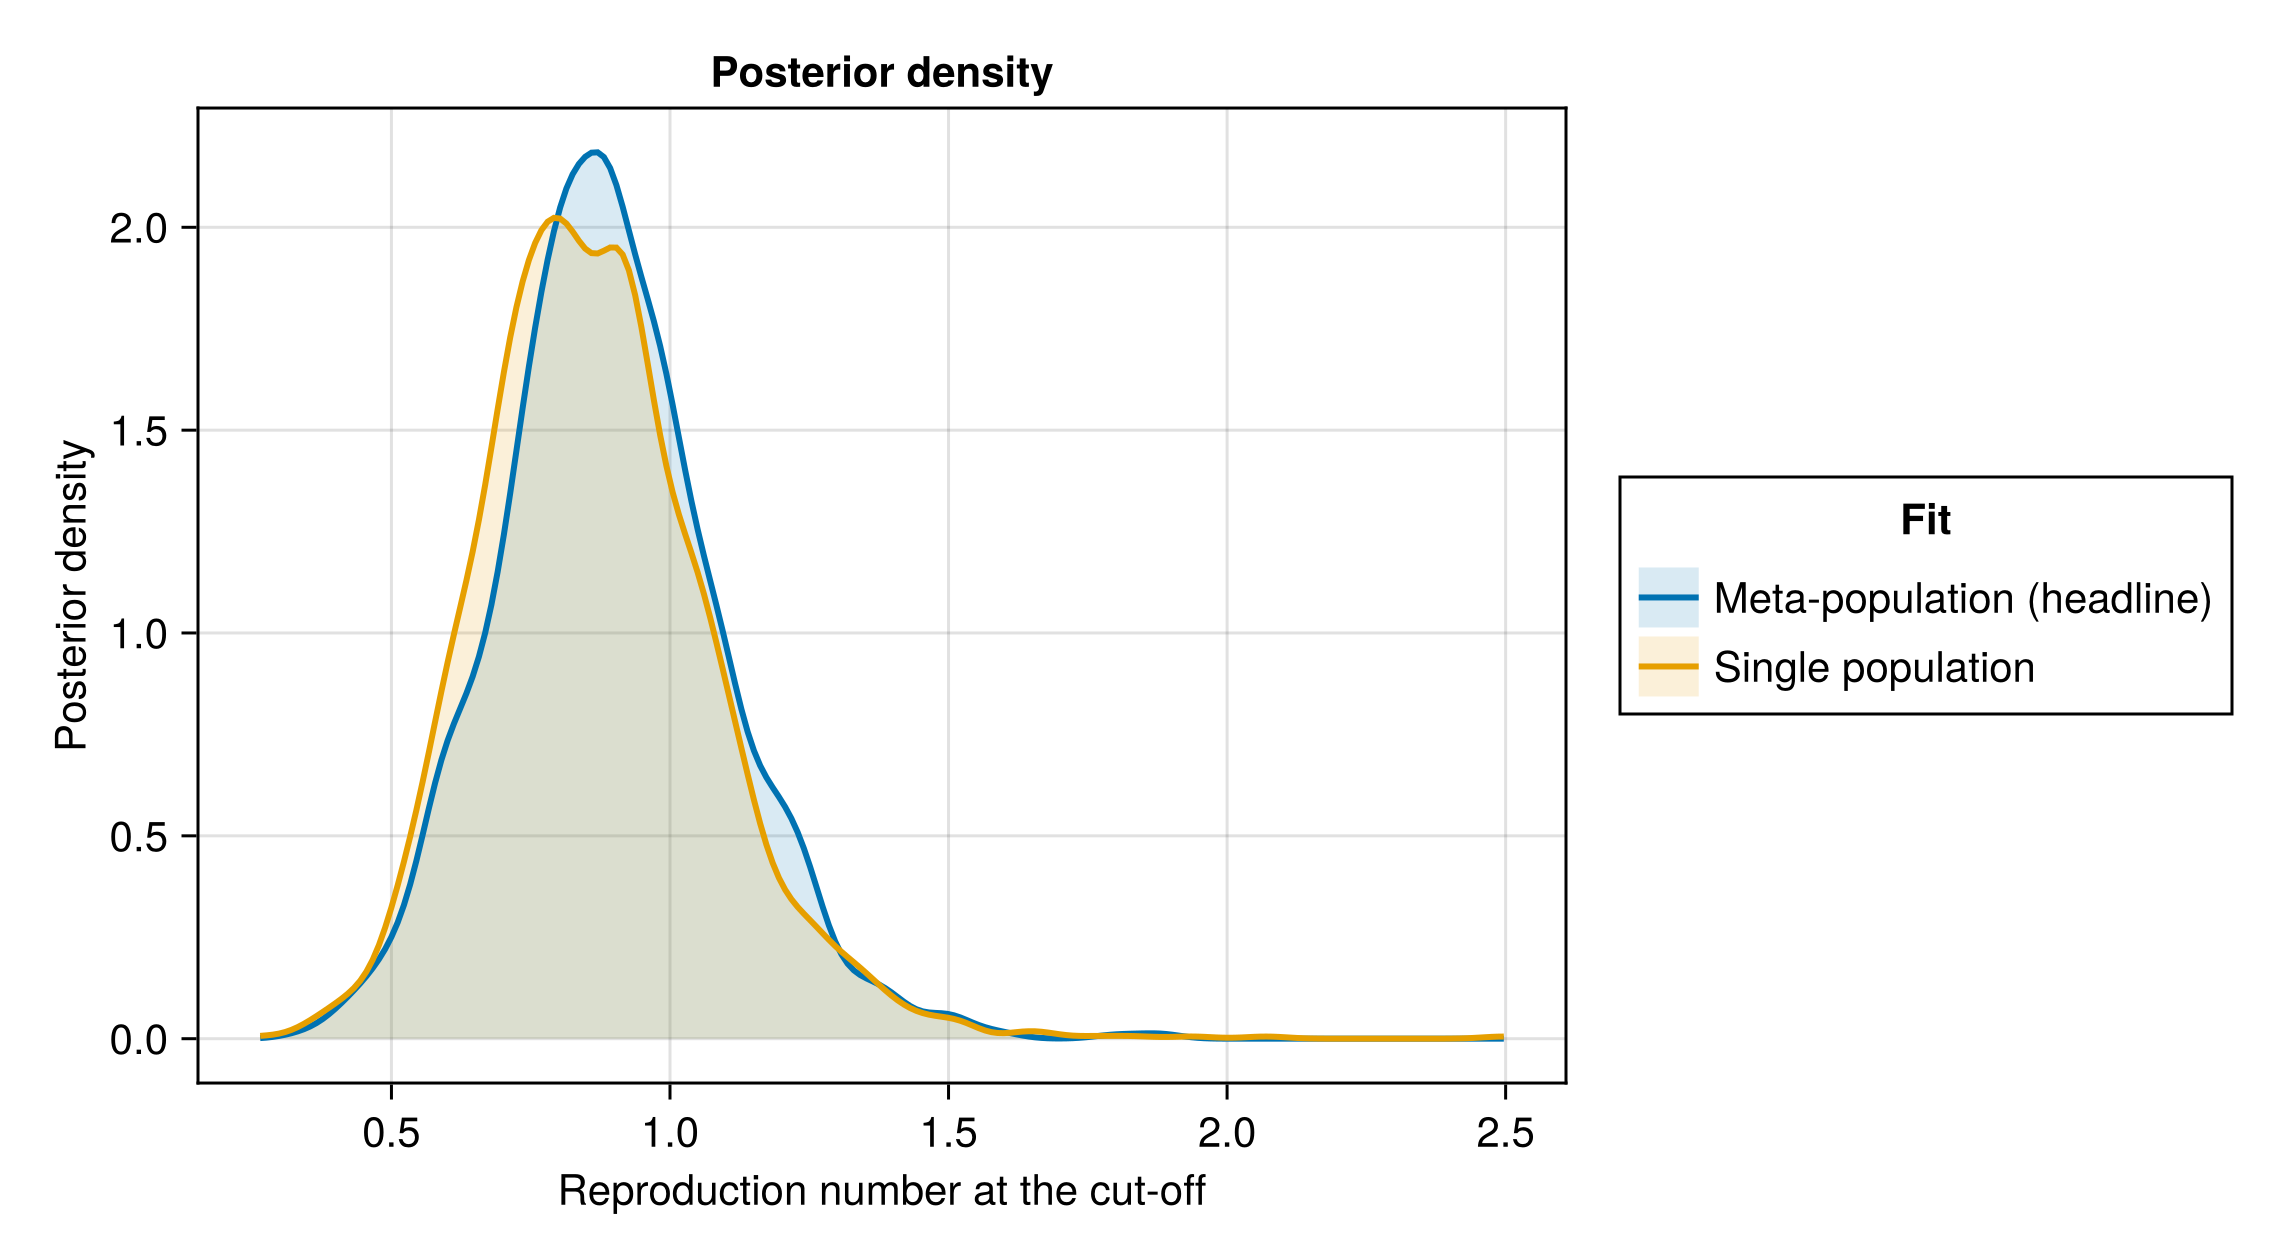
The table gathers the same three quantities as credible intervals, alongside the outbreak start date the two fits imply.
National quantities under both structures, as a table
# One row per national quantity, one column per structure, each cell a
# median with a 90% credible interval. Built here rather than by stacking
# two `summary_table` calls, so the two structures sit side by side and the
# reader compares along a row.
spatial_quantities_table = let
    # A count rounded to zero decimals still prints a trailing ".0", so
    # whole-number quantities go through `Int`.
    fmt(x, d) = d <= 0 ? string(round(Int, x)) : string(round(x; digits = d))
    cell(v, d) = string(
        fmt(quantile(v, 0.5), d), " (",
        fmt(quantile(v, 0.05), d), "–", fmt(quantile(v, 0.95), d), ")"
    )
    rows = [
        ("Cumulative infections", :C_T, 0),
        ("Reproduction number at the cut-off", :R_T, 2),
        ("Case-fatality ratio", :CFR, 2),
        ("Outbreak age (days)", :T, 0),
        ("Latest growth rate (per day)", :r, 3),
    ]
    DataFrame(
        "Quantity" => [r[1] for r in rows],
        "Meta-population (headline)" => [
            cell(
                vec(Array(chn_joint[r[2]])), r[3]
            )
                for r in rows
        ],
        "Single population" => [
            cell(vec(Array(chn_no_patches[r[2]])), r[3])
                for r in rows
        ]
    )
end;| Row | Quantity | Meta-population (headline) | Single population |
|---|---|---|---|
| String | String | String | |
| 1 | Cumulative infections | 18238 (12343–27006) | 17892 (12399–27415) |
| 2 | Reproduction number at the cut-off | 0.88 (0.58–1.24) | 0.85 (0.57–1.23) |
| 3 | Case-fatality ratio | 0.47 (0.37–0.58) | 0.49 (0.38–0.6) |
| 4 | Outbreak age (days) | 193 (182–210) | 194 (184–211) |
| 5 | Latest growth rate (per day) | -0.009 (-0.037–0.017) | -0.011 (-0.037–0.015) |
Saving sensitivity results
The stream-comparison and frozen-fit tables are written to the shared output directory. The main analysis writes the rest, so the combined release and summary dashboard pick up both pages' outputs.
Write sensitivity outputs
output_dir = get(
    ENV, "BVD_OUTPUT_DIR",
    joinpath(pkgdir(BVDOutbreakSize), "output")
)
mkpath(output_dir)
CSV.write(
    joinpath(output_dir, "cumulative_cases_by_stream.csv"),
    streams_C_table
)
CSV.write(
    joinpath(output_dir, "frozen_matched_cutoffs.csv"),
    frozen_streams_table
)
"/home/runner/work/BVDOutbreakSize/BVDOutbreakSize/output/frozen_matched_cutoffs.csv"